pax_global_header00006660000000000000000000000064152417564470014531gustar00rootroot0000000000000052 comment=f86f8b4b2eef8499ddd72ec749d4a4cdfbb37e19
cmaes-0.13.1/000077500000000000000000000000001524175644700127035ustar00rootroot00000000000000cmaes-0.13.1/.github/000077500000000000000000000000001524175644700142435ustar00rootroot00000000000000cmaes-0.13.1/.github/ISSUE_TEMPLATE/000077500000000000000000000000001524175644700164265ustar00rootroot00000000000000cmaes-0.13.1/.github/ISSUE_TEMPLATE/bug_report.md000066400000000000000000000010661524175644700211230ustar00rootroot00000000000000---
name: "Bug report"
about: Create a bug report to improve cmaes
title: ""
labels: bug
assignees: ''
---
# Bug reports
*Please file a bug report here.*
## Expected Behavior
*Please describe the behavior you are expecting*
## Current Behavior and Steps to Reproduce
*What is the current behavior? Please provide detailed steps or example for reproducing.*
## Context
Please provide any relevant information about your setup. This is important in case the issue is not reproducible except for under certain conditions.
* cmaes version or commit revision:
cmaes-0.13.1/.github/ISSUE_TEMPLATE/feature_request.md000066400000000000000000000002711524175644700221530ustar00rootroot00000000000000---
name: "Feature request"
about: Suggest an idea for new features in cmaes.
title: ""
labels: enhancement
assignees: ''
---
# Feature Request
*Please write your suggestion here.*
cmaes-0.13.1/.github/ISSUE_TEMPLATE/question.md000066400000000000000000000015511524175644700206210ustar00rootroot00000000000000---
name: "Question"
about: Ask questions about implementations, features, or any other project-related inquiries
title: "[Question] "
labels: question
assignees: ''
---
## Summary of the Question
## Detailed Explanation
## Context and Environment
## Additional Information
cmaes-0.13.1/.github/workflows/000077500000000000000000000000001524175644700163005ustar00rootroot00000000000000cmaes-0.13.1/.github/workflows/examples.yml000066400000000000000000000030111524175644700206340ustar00rootroot00000000000000name: Run examples
on:
pull_request:
paths:
- '.github/workflows/examples.yml'
- 'examples/**.py'
- 'cmaes/**.py'
jobs:
examples:
runs-on: ubuntu-latest
strategy:
matrix:
python-version: ["3.9", "3.14"]
steps:
- uses: actions/checkout@v6
- name: Install the latest version of uv and set the python version
uses: astral-sh/setup-uv@v7
with:
python-version: ${{ matrix.python-version }}
- name: Install dependencies
run: uv sync --group optional --group benchmark
- run: uv run python examples/quadratic_2d_function.py
- run: uv run python examples/ipop_cma.py
- run: uv run python examples/bipop_cma.py
- run: uv run python examples/ellipsoid_function.py
- run: uv run python examples/optuna_sampler.py
- run: uv run python examples/lra_cma.py
- run: uv run python examples/ws_cma.py
- run: uv run python examples/cma_with_margin_binary.py
- run: uv run python examples/cma_with_margin_integer.py
- run: uv run python examples/safecma.py
- run: uv run python examples/cma_sop.py
examples-cmawm-without-scipy:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v6
- name: Install the latest version of uv and set the python version
uses: astral-sh/setup-uv@v7
- name: Install dependencies
run: uv sync
- run: uv run python examples/cma_with_margin_binary.py
- run: uv run python examples/cma_with_margin_integer.py
cmaes-0.13.1/.github/workflows/pypi-publish.yml000066400000000000000000000022221524175644700214460ustar00rootroot00000000000000name: Publish distributions to TestPyPI and PyPI
on:
push:
tags:
- v*.*.*
jobs:
build-n-publish:
name: Build and publish Python distributions to TestPyPI and PyPI
runs-on: ubuntu-latest
permissions:
id-token: write
steps:
- uses: actions/checkout@v6
- name: Install the latest version of uv and set the python version
uses: astral-sh/setup-uv@v7
- name: Build distribution packages
run: uv build --sdist --wheel --no-sources
- name: Verify the distributions
run: uvx twine check dist/*
- uses: actions/upload-artifact@v7
with:
name: distribution
path: dist/
- name: Publish distribution to Test PyPI
uses: pypa/gh-action-pypi-publish@release/v1
with:
repository-url: https://test.pypi.org/legacy/
- name: Publish distribution to PyPI
uses: pypa/gh-action-pypi-publish@release/v1
- name: Create GitHub release
env:
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
run: |
export TAGNAME=$(jq --raw-output .ref "$GITHUB_EVENT_PATH" | sed -e "s/refs\/tags\///")
gh release create ${TAGNAME} --draft dist/*
cmaes-0.13.1/.github/workflows/tests.yml000066400000000000000000000016341524175644700201710ustar00rootroot00000000000000name: Run tests and linters
on:
pull_request:
paths:
- '.github/workflows/tests.yml'
- 'pyproject.toml'
- '**.py'
jobs:
lint:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v6
- name: Install uv
uses: astral-sh/setup-uv@v7
- name: Install dependencies
run: uv sync --group dev --group optional
- run: uv run ruff check .
- run: uv run ruff format --check .
- run: uv run mypy cmaes
test:
runs-on: ubuntu-latest
strategy:
matrix:
python-version: ["3.9", "3.14"]
steps:
- uses: actions/checkout@v6
- name: Install the latest version of uv and set the python version
uses: astral-sh/setup-uv@v7
with:
python-version: ${{ matrix.python-version }}
- name: Install dependencies
run: uv sync --group dev --group optional
- run: uv run pytest tests
cmaes-0.13.1/.gitignore000066400000000000000000000002051524175644700146700ustar00rootroot00000000000000venv/
dist/
build/
__pycache__/
.mypy_cache/
*.pyc
.eggs/
*.egg-info/
.hypothesis
tmp/
benchmark/*.json
*.stats
*.sqlite3
uv.lock
cmaes-0.13.1/LICENSE000066400000000000000000000020611524175644700137070ustar00rootroot00000000000000MIT License
Copyright (c) 2020 CyberAgent, Inc.
Permission is hereby granted, free of charge, to any person obtaining a copy
of this software and associated documentation files (the "Software"), to deal
in the Software without restriction, including without limitation the rights
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
copies of the Software, and to permit persons to whom the Software is
furnished to do so, subject to the following conditions:
The above copyright notice and this permission notice shall be included in all
copies or substantial portions of the Software.
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
SOFTWARE.
cmaes-0.13.1/README.md000066400000000000000000000670171524175644700141750ustar00rootroot00000000000000# cmaes
[](./LICENSE) [](https://pypistats.org/packages/cmaes)
:whale: [**Paper is now available on arXiv!**](https://arxiv.org/abs/2402.01373)
*Simple* and *Practical* Python library for CMA-ES.
Please refer to the [paper](https://arxiv.org/abs/2402.01373) [Nomura et al. 2026] for detailed information, including the design philosophy and advanced examples.
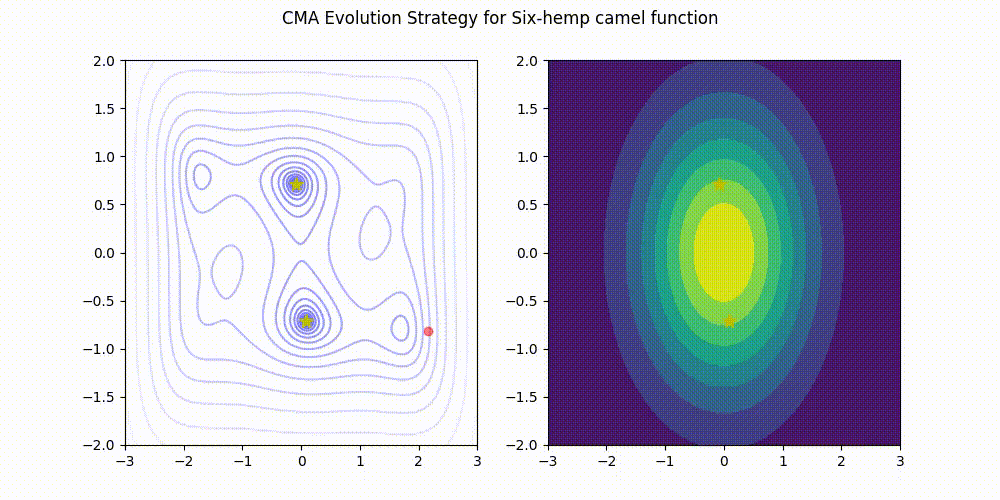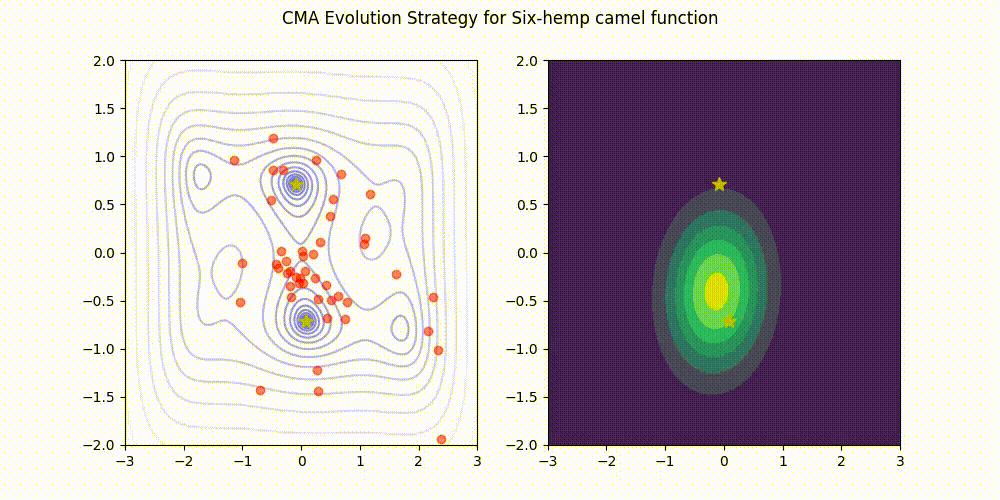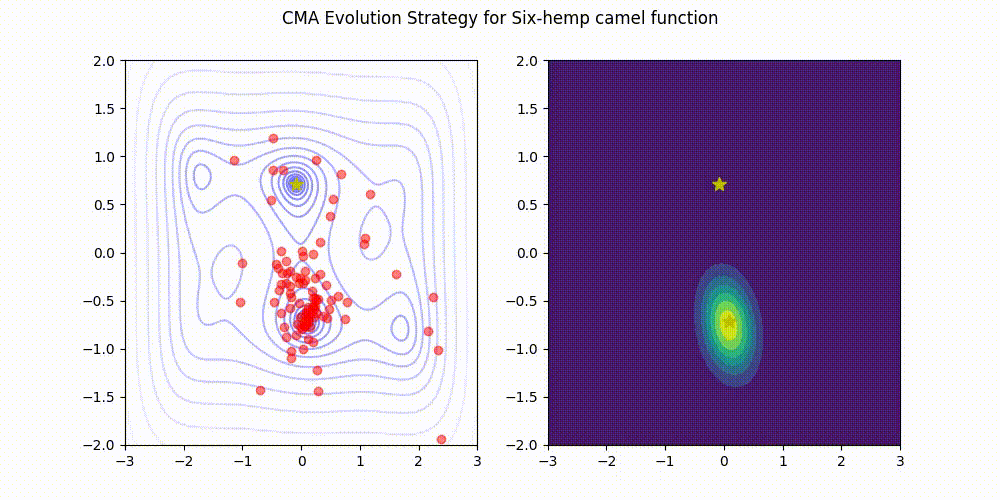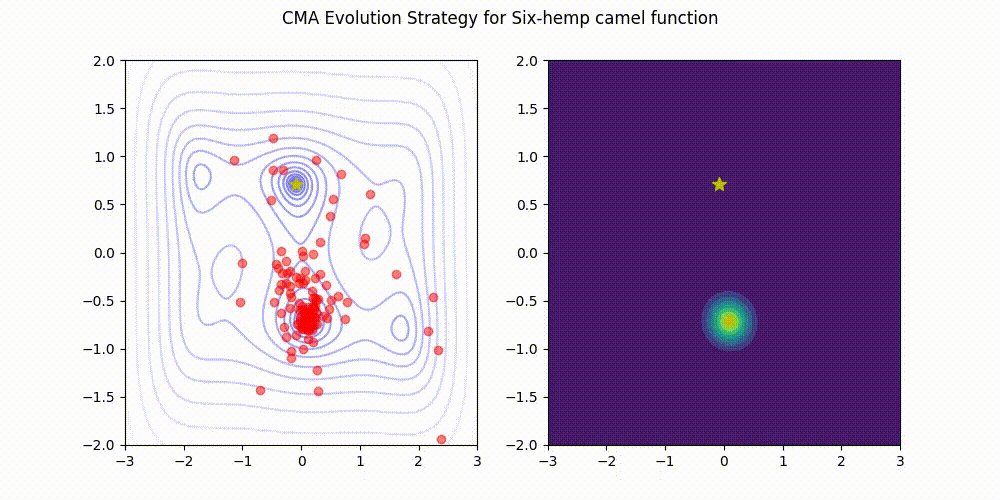
## Installation
Supported Python versions are 3.9 or later.
```
$ pip install cmaes
```
Or you can install via [conda-forge](https://anaconda.org/conda-forge/cmaes).
```
$ conda install -c conda-forge cmaes
```
## Usage
This library provides an "ask-and-tell" style interface. We employ the standard version of CMA-ES [Hansen 2016].
```python
import numpy as np
from cmaes import CMA
def quadratic(x1, x2):
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
if __name__ == "__main__":
optimizer = CMA(mean=np.zeros(2), sigma=1.3)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = quadratic(x[0], x[1])
solutions.append((x, value))
print(f"#{generation} {value} (x1={x[0]}, x2 = {x[1]})")
optimizer.tell(solutions)
```
You can also use this library via [Optuna](https://github.com/optuna/optuna) [Akiba et al. 2019], an automatic hyperparameter optimization framework.
```python
import optuna
def objective(trial: optuna.Trial):
x1 = trial.suggest_float("x1", -4, 4)
x2 = trial.suggest_float("x2", -4, 4)
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
if __name__ == "__main__":
sampler = optuna.samplers.CmaEsSampler()
study = optuna.create_study(sampler=sampler)
study.optimize(objective, n_trials=250)
```
For more information, see [the documentation](https://optuna.readthedocs.io/en/stable/reference/samplers/generated/optuna.samplers.CmaEsSampler.html).
## CMA-ES variants
#### CatCMA with Margin [Hamano et al. 2025]
CatCMA with Margin (CatCMAwM) is a method for mixed-variable optimization problems, simultaneously optimizing continuous, integer, and categorical variables. CatCMAwM extends CatCMA by introducing a novel integer handling mechanism, and supports arbitrary combinations of continuous, integer, and categorical variables in a unified framework.

Source code
```python
import numpy as np
from cmaes import CatCMAwM
def SphereIntCOM(x, z, c):
return sum(x * x) + sum(z * z) + len(c) - sum(c[:, 0])
def SphereInt(x, z):
return sum(x * x) + sum(z * z)
def SphereCOM(x, c):
return sum(x * x) + len(c) - sum(c[:, 0])
def f_cont_int_cat():
# [lower_bound, upper_bound] for each continuous variable
X = [[-5, 5], [-5, 5]]
# possible values for each integer variable
Z = [[-1, 0, 1], [-2, -1, 0, 1, 2]]
# number of categories for each categorical variable
C = [3, 3]
optimizer = CatCMAwM(x_space=X, z_space=Z, c_space=C)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
sol = optimizer.ask()
value = SphereIntCOM(sol.x, sol.z, sol.c)
solutions.append((sol, value))
print(f"#{generation} {sol} evaluation: {value}")
optimizer.tell(solutions)
def f_cont_int():
# [lower_bound, upper_bound] for each continuous variable
X = [[-np.inf, np.inf], [-np.inf, np.inf]]
# possible values for each integer variable
Z = [[-2, -1, 0, 1, 2], [-2, -1, 0, 1, 2]]
# initial distribution parameters (Optional)
# If you know a promising solution for X and Z, set init_mean to that value.
init_mean = np.ones(len(X) + len(Z))
init_cov = np.diag(np.ones(len(X) + len(Z)))
init_sigma = 1.0
optimizer = CatCMAwM(
x_space=X, z_space=Z, mean=init_mean, cov=init_cov, sigma=init_sigma
)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
sol = optimizer.ask()
value = SphereInt(sol.x, sol.z)
solutions.append((sol, value))
print(f"#{generation} {sol} evaluation: {value}")
optimizer.tell(solutions)
def f_cont_cat():
# [lower_bound, upper_bound] for each continuous variable
X = [[-5, 5], [-5, 5]]
# number of categories for each categorical variable
C = [3, 5]
# initial distribution parameters (Optional)
init_cat_param = np.array(
[
[0.5, 0.3, 0.2, 0.0, 0.0], # zero-padded at the end
[0.2, 0.2, 0.2, 0.2, 0.2], # each row must sum to 1
]
)
optimizer = CatCMAwM(x_space=X, c_space=C, cat_param=init_cat_param)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
sol = optimizer.ask()
value = SphereCOM(sol.x, sol.c)
solutions.append((sol, value))
print(f"#{generation} {sol} evaluation: {value}")
optimizer.tell(solutions)
if __name__ == "__main__":
f_cont_int_cat()
# f_cont_int()
# f_cont_cat()
```
The full source code is available [here](./examples/catcma_with_margin.py).
We recommend using CatCMAwM for continuous+integer and continuous+categorical settings. In particular, [Hamano et al. 2025] shows that CatCMAwM outperforms CMA-ES with Margin in mixed-integer scenarios. Therefore, we suggest CatCMAwM in place of CMA-ES with Margin or CatCMA.
#### COMO-CatCMA with Margin [Hamano et al. 2026]
COMO-CatCMA with Margin (COMO-CatCMAwM) performs multi-objective mixed-variable optimization by coordinating multiple CatCMAwM optimizers. It currently supports two-objective problems; support for three or more objectives is planned.
Source code
```python
import numpy as np
from cmaes import COMOCatCMAwM
def DSIntLFTL(x, z, c, cat_num):
Sphere1 = sum((x / 10) ** 2) / len(x)
Sphere2 = sum((x / 10 - 1) ** 2) / len(x)
SphereInt1 = sum((z / 10) ** 2) / len(z)
SphereInt2 = sum((z / 10 - 1) ** 2) / len(z)
c_idx = c.argmax(axis=1)
LF = (len(c) - (c_idx == 0).cumprod().sum()) / len(c)
TL = (len(c) - (c_idx == np.asarray(cat_num) - 1)[::-1].cumprod().sum()) / len(c)
obj1 = Sphere1 + SphereInt1 + LF
obj2 = Sphere2 + SphereInt2 + TL
return [obj1, obj2]
if __name__ == "__main__":
# [lower_bound, upper_bound] for each continuous variable
X = [[-5, 15]] * 3
# possible values for each integer variable
Z = [range(-5, 16)] * 3
# number of categories for each categorical variable
C = [5] * 3
optimizer = COMOCatCMAwM(x_space=X, z_space=Z, c_space=C)
evals = 0
while evals < 7000:
solutions = []
for sol in optimizer.ask_iter():
value = DSIntLFTL(sol.x, sol.z, sol.c, C)
evals += 1
solutions.append((sol, value))
optimizer.tell(solutions)
print(evals, optimizer.incumbent_objectives)
```
The full source code is available [here](./examples/como_catcma_with_margin.py).
#### CatCMA [Hamano et al. 2024a]
CatCMA is a method for mixed-category optimization problems, which is the problem of simultaneously optimizing continuous and categorical variables. CatCMA employs the joint probability distribution of multivariate Gaussian and categorical distributions as the search distribution.

Source code
```python
import numpy as np
from cmaes import CatCMA
def sphere_com(x, c):
dim_co = len(x)
dim_ca = len(c)
if dim_co < 2:
raise ValueError("dimension must be greater one")
sphere = sum(x * x)
com = dim_ca - sum(c[:, 0])
return sphere + com
def rosenbrock_clo(x, c):
dim_co = len(x)
dim_ca = len(c)
if dim_co < 2:
raise ValueError("dimension must be greater one")
rosenbrock = sum(100 * (x[:-1] ** 2 - x[1:]) ** 2 + (x[:-1] - 1) ** 2)
clo = dim_ca - (c[:, 0].argmin() + c[:, 0].prod() * dim_ca)
return rosenbrock + clo
def mc_proximity(x, c, cat_num):
dim_co = len(x)
dim_ca = len(c)
if dim_co < 2:
raise ValueError("dimension must be greater one")
if dim_co != dim_ca:
raise ValueError(
"number of dimensions of continuous and categorical variables "
"must be equal in mc_proximity"
)
c_index = np.argmax(c, axis=1) / cat_num
return sum((x - c_index) ** 2) + sum(c_index)
if __name__ == "__main__":
cont_dim = 5
cat_dim = 5
cat_num = np.array([3, 4, 5, 5, 5])
# cat_num = 3 * np.ones(cat_dim, dtype=np.int64)
optimizer = CatCMA(mean=3.0 * np.ones(cont_dim), sigma=1.0, cat_num=cat_num)
for generation in range(200):
solutions = []
for _ in range(optimizer.population_size):
x, c = optimizer.ask()
value = mc_proximity(x, c, cat_num)
if generation % 10 == 0:
print(f"#{generation} {value}")
solutions.append(((x, c), value))
optimizer.tell(solutions)
if optimizer.should_stop():
break
```
The full source code is available [here](./examples/catcma.py).
#### Safe CMA [Uchida et al. 2024a]
Safe CMA-ES is a variant of CMA-ES for safe optimization. Safe optimization is formulated as a special type of constrained optimization problem aiming to solve the optimization problem with fewer evaluations of the solutions whose safety function values exceed the safety thresholds. The safe CMA-ES requires safe seeds that do not violate the safety constraints. Note that the safe CMA-ES is designed for noiseless safe optimization. This module needs `torch` and `gpytorch`.
Source code
```python
import numpy as np
from cmaes.safe_cma import SafeCMA
# objective function
def quadratic(x):
coef = 1000 ** (np.arange(dim) / float(dim - 1))
return np.sum((x * coef) ** 2)
# safety function
def safe_function(x):
return x[0]
"""
example with a single safety function
"""
if __name__ == "__main__":
# number of dimensions
dim = 5
# safe seeds
safe_seeds_num = 10
safe_seeds = (np.random.rand(safe_seeds_num, dim) * 2 - 1) * 5
safe_seeds[:,0] = - np.abs(safe_seeds[:,0])
# evaluation of safe seeds (with a single safety function)
seeds_evals = np.array([ quadratic(x) for x in safe_seeds ])
seeds_safe_evals = np.stack([ [safe_function(x)] for x in safe_seeds ])
safety_threshold = np.array([0])
# optimizer (safe CMA-ES)
optimizer = SafeCMA(
sigma=1.,
safety_threshold=safety_threshold,
safe_seeds=safe_seeds,
seeds_evals=seeds_evals,
seeds_safe_evals=seeds_safe_evals,
)
unsafe_eval_counts = 0
best_eval = np.inf
for generation in range(400):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x = optimizer.ask()
value = quadratic(x)
safe_value = np.array([safe_function(x)])
# save best eval
best_eval = np.min((best_eval, value))
unsafe_eval_counts += (safe_value > safety_threshold)
solutions.append((x, value, safe_value))
# Tell evaluation values.
optimizer.tell(solutions)
print(f"#{generation} ({best_eval} {unsafe_eval_counts})")
if optimizer.should_stop():
break
```
The full source code is available [here](./examples/safecma.py).
#### Maximum a Posteriori CMA-ES [Hamano et al. 2024b]
MAP-CMA is a method that is introduced to interpret the rank-one update in the CMA-ES from the perspective of the natural gradient.
The rank-one update derived from the natural gradient perspective is extensible, and an additional term, called momentum update, appears in the update of the mean vector.
The performance of MAP-CMA is not significantly different from that of CMA-ES, as the primary motivation for MAP-CMA comes from the theoretical understanding of CMA-ES.
Source code
```python
import numpy as np
from cmaes import MAPCMA
def rosenbrock(x):
dim = len(x)
if dim < 2:
raise ValueError("dimension must be greater one")
return sum(100 * (x[:-1] ** 2 - x[1:]) ** 2 + (x[:-1] - 1) ** 2)
if __name__ == "__main__":
dim = 20
optimizer = MAPCMA(mean=np.zeros(dim), sigma=0.5, momentum_r=dim)
print(" evals f(x)")
print("====== ==========")
evals = 0
while True:
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = rosenbrock(x)
evals += 1
solutions.append((x, value))
if evals % 1000 == 0:
print(f"{evals:5d} {value:10.5f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
```
The full source code is available [here](./examples/mapcma.py).
#### CMA-ES-SoP [Uchida et al. 2024b]
CMA-ES on sets of points (CMA-ES-SoP) is a variant of CMA-ES for optimization on sets of points. In the optimization on sets of points, the search space consists of several disjoint subspaces containing multiple possible points where the objective function value can be computed. In the mixed-variable cases, some subspaces are continuous spaces. Note that the discrete subspaces with more than five dimensions require computational cost for the construction of the Voronoi diagrams.
Source code
```python
import numpy as np
from cmaes.cma_sop import CMASoP
# numbers of dimensions in each subspace
subspace_dim_list = [2, 3, 5]
cont_dim = 10
# numbers of points in each subspace
point_num_list = [10, 20, 40]
# number of total dimensions
dim = int(np.sum(subspace_dim_list) + cont_dim)
# objective function
def quadratic(x):
coef = 1000 ** (np.arange(dim) / float(dim - 1))
return np.sum((coef * x) ** 2)
# sets_of_points (on [-5, 5])
discrete_subspace_num = len(subspace_dim_list)
sets_of_points = [(
2 * np.random.rand(point_num_list[i], subspace_dim_list[i]) - 1) * 5
for i in range(discrete_subspace_num)]
# add the optimal solution (for benchmark function)
for i in range(discrete_subspace_num):
sets_of_points[i][-1] = np.zeros(subspace_dim_list[i])
np.random.shuffle(sets_of_points[i])
# optimizer (CMA-ES-SoP)
optimizer = CMASoP(
sets_of_points=sets_of_points,
mean=np.random.rand(dim) * 4 + 1,
sigma=2.0,
)
best_eval = np.inf
eval_count = 0
for generation in range(400):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x, enc_x = optimizer.ask()
value = quadratic(enc_x)
# save best eval
best_eval = np.min((best_eval, value))
eval_count += 1
solutions.append((x, value))
# Tell evaluation values.
optimizer.tell(solutions)
print(f"#{generation} ({best_eval} {eval_count})")
if best_eval < 1e-4 or optimizer.should_stop():
break
```
The full source code is available [here](./examples/cma_sop.py).
#### Learning Rate Adaptation CMA-ES [Nomura et al. 2023]
The performance of the CMA-ES can deteriorate when faced with *difficult* problems such as multimodal or noisy ones, if its hyperparameter values are not properly configured.
The Learning Rate Adaptation CMA-ES (LRA-CMA) effectively addresses this issue by autonomously adjusting the learning rate.
Consequently, LRA-CMA eliminates the need for expensive hyperparameter tuning.
LRA-CMA can be used by simply adding `lr_adapt=True` to the initialization of `CMA()`.
Source code
```python
import numpy as np
from cmaes import CMA
def rastrigin(x):
dim = len(x)
return 10 * dim + sum(x**2 - 10 * np.cos(2 * np.pi * x))
if __name__ == "__main__":
dim = 40
optimizer = CMA(mean=3*np.ones(dim), sigma=2.0, lr_adapt=True)
for generation in range(50000):
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = rastrigin(x)
if generation % 500 == 0:
print(f"#{generation} {value}")
solutions.append((x, value))
optimizer.tell(solutions)
if optimizer.should_stop():
break
```
The full source code is available [here](./examples/lra_cma.py).
#### CMA-ES with Margin [Hamano et al. 2022]
CMA-ES with Margin (CMAwM) introduces a lower bound on the marginal probability for each discrete dimension, ensuring that samples avoid being fixed to a single point.
This method can be applied to mixed spaces consisting of continuous (such as float) and discrete elements (including integer and binary types).
|CMA|CMAwM|
|---|---|
|||
The above figures are taken from [EvoConJP/CMA-ES_with_Margin](https://github.com/EvoConJP/CMA-ES_with_Margin).
Source code
```python
import numpy as np
from cmaes import CMAwM
def ellipsoid_onemax(x, n_zdim):
n = len(x)
n_rdim = n - n_zdim
r = 10
if len(x) < 2:
raise ValueError("dimension must be greater one")
ellipsoid = sum([(1000 ** (i / (n_rdim - 1)) * x[i]) ** 2 for i in range(n_rdim)])
onemax = n_zdim - (0.0 < x[(n - n_zdim) :]).sum()
return ellipsoid + r * onemax
def main():
binary_dim, continuous_dim = 10, 10
dim = binary_dim + continuous_dim
bounds = np.concatenate(
[
np.tile([-np.inf, np.inf], (continuous_dim, 1)),
np.tile([0, 1], (binary_dim, 1)),
]
)
steps = np.concatenate([np.zeros(continuous_dim), np.ones(binary_dim)])
optimizer = CMAwM(mean=np.zeros(dim), sigma=2.0, bounds=bounds, steps=steps)
print(" evals f(x)")
print("====== ==========")
evals = 0
while True:
solutions = []
for _ in range(optimizer.population_size):
x_for_eval, x_for_tell = optimizer.ask()
value = ellipsoid_onemax(x_for_eval, binary_dim)
evals += 1
solutions.append((x_for_tell, value))
if evals % 300 == 0:
print(f"{evals:5d} {value:10.5f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
if __name__ == "__main__":
main()
```
Source code is also available [here](./examples/cmaes_with_margin.py).
#### Warm Starting CMA-ES [Nomura et al. 2021]
Warm Starting CMA-ES (WS-CMA) is a method that transfers prior knowledge from similar tasks through the initialization of the CMA-ES.
This is useful especially when the evaluation budget is limited (e.g., hyperparameter optimization of machine learning algorithms).
Source code
```python
import numpy as np
from cmaes import CMA, get_warm_start_mgd
def source_task(x1: float, x2: float) -> float:
b = 0.4
return (x1 - b) ** 2 + (x2 - b) ** 2
def target_task(x1: float, x2: float) -> float:
b = 0.6
return (x1 - b) ** 2 + (x2 - b) ** 2
if __name__ == "__main__":
# Generate solutions from a source task
source_solutions = []
for _ in range(1000):
x = np.random.random(2)
value = source_task(x[0], x[1])
source_solutions.append((x, value))
# Estimate a promising distribution of the source task,
# then generate parameters of the multivariate gaussian distribution.
ws_mean, ws_sigma, ws_cov = get_warm_start_mgd(
source_solutions, gamma=0.1, alpha=0.1
)
optimizer = CMA(mean=ws_mean, sigma=ws_sigma, cov=ws_cov)
# Run WS-CMA-ES
print(" g f(x1,x2) x1 x2 ")
print("=== ========== ====== ======")
while True:
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = target_task(x[0], x[1])
solutions.append((x, value))
print(
f"{optimizer.generation:3d} {value:10.5f}"
f" {x[0]:6.2f} {x[1]:6.2f}"
)
optimizer.tell(solutions)
if optimizer.should_stop():
break
```
The full source code is available [here](./examples/ws_cma.py).
#### Separable CMA-ES [Ros and Hansen 2008]
Sep-CMA-ES is an algorithm that limits the covariance matrix to a diagonal form.
This reduction in the number of parameters enhances scalability, making Sep-CMA-ES well-suited for high-dimensional optimization tasks.
Additionally, the learning rate for the covariance matrix is increased, leading to superior performance over the (full-covariance) CMA-ES on separable functions.
Source code
```python
import numpy as np
from cmaes import SepCMA
def ellipsoid(x):
n = len(x)
if len(x) < 2:
raise ValueError("dimension must be greater one")
return sum([(1000 ** (i / (n - 1)) * x[i]) ** 2 for i in range(n)])
if __name__ == "__main__":
dim = 40
optimizer = SepCMA(mean=3 * np.ones(dim), sigma=2.0)
print(" evals f(x)")
print("====== ==========")
evals = 0
while True:
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = ellipsoid(x)
evals += 1
solutions.append((x, value))
if evals % 3000 == 0:
print(f"{evals:5d} {value:10.5f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
```
Full source code is available [here](./examples/sep_cma.py).
#### IPOP-CMA-ES [Auger and Hansen 2005]
IPOP-CMA-ES is a method that involves restarting the CMA-ES with an incrementally increasing population size, as described below.
Source code
```python
import math
import numpy as np
from cmaes import CMA
def ackley(x1, x2):
# https://www.sfu.ca/~ssurjano/ackley.html
return (
-20 * math.exp(-0.2 * math.sqrt(0.5 * (x1 ** 2 + x2 ** 2)))
- math.exp(0.5 * (math.cos(2 * math.pi * x1) + math.cos(2 * math.pi * x2)))
+ math.e + 20
)
if __name__ == "__main__":
bounds = np.array([[-32.768, 32.768], [-32.768, 32.768]])
lower_bounds, upper_bounds = bounds[:, 0], bounds[:, 1]
mean = lower_bounds + (np.random.rand(2) * (upper_bounds - lower_bounds))
sigma = 32.768 * 2 / 5 # 1/5 of the domain width
optimizer = CMA(mean=mean, sigma=sigma, bounds=bounds, seed=0)
for generation in range(200):
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = ackley(x[0], x[1])
solutions.append((x, value))
print(f"#{generation} {value} (x1={x[0]}, x2 = {x[1]})")
optimizer.tell(solutions)
if optimizer.should_stop():
# popsize multiplied by 2 (or 3) before each restart.
popsize = optimizer.population_size * 2
mean = lower_bounds + (np.random.rand(2) * (upper_bounds - lower_bounds))
optimizer = CMA(mean=mean, sigma=sigma, population_size=popsize)
print(f"Restart CMA-ES with popsize={popsize}")
```
Full source code is available [here](./examples/ipop_cma.py).
## Citation
If you use our library in your work, please cite our paper:
Masahiro Nomura, Masashi Shibata, Ryoki Hamano.
**cmaes: A Simple yet Practical Python Library for CMA-ES**
[https://arxiv.org/abs/2402.01373](https://arxiv.org/abs/2402.01373)
Bibtex:
```
@article{nomura2026cmaes,
title={cmaes: A Simple yet Practical Python Library for CMA-ES},
author={Nomura, Masahiro and Shibata, Masashi and Hamano, Ryoki},
journal={arXiv preprint arXiv:2402.01373},
year={2026}
}
```
## Links
**Projects using cmaes:**
* [Optuna](https://github.com/optuna/optuna) : A hyperparameter optimization framework that supports CMA-ES using this library under the hood.
* [Kubeflow/Katib](https://www.kubeflow.org/docs/components/katib/user-guides/katib-config/) : Kubernetes-based system for hyperparameter tuning and neural architecture search
* (If you are using `cmaes` in your project and would like it to be listed here, please submit a GitHub issue.)
**Other libraries:**
We have great respect for all libraries involved in CMA-ES.
* [pycma](https://github.com/CMA-ES/pycma) : Most renowned CMA-ES implementation, created and maintained by Nikolaus Hansen.
* [pymoo](https://github.com/msu-coinlab/pymoo) : A library for multi-objective optimization in Python.
* [evojax](https://github.com/google/evojax) : evojax offers a JAX-port of this library.
* [evosax](https://github.com/RobertTLange/evosax) : evosax provides a JAX-based implementation of CMA-ES and sep-CMA-ES, inspired by this library.
**References:**
* [Akiba et al. 2019] [T. Akiba, S. Sano, T. Yanase, T. Ohta, M. Koyama, Optuna: A Next-generation Hyperparameter Optimization Framework, KDD, 2019.](https://dl.acm.org/citation.cfm?id=3330701)
* [Auger and Hansen 2005] [A. Auger, N. Hansen, A Restart CMA Evolution Strategy with Increasing Population Size, CEC, 2005.](http://www.cmap.polytechnique.fr/~nikolaus.hansen/cec2005ipopcmaes.pdf)
* [Hamano et al. 2022] [R. Hamano, S. Saito, M. Nomura, S. Shirakawa, CMA-ES with Margin: Lower-Bounding Marginal Probability for Mixed-Integer Black-Box Optimization, GECCO, 2022.](https://arxiv.org/abs/2205.13482)
* [Hamano et al. 2024a] [R. Hamano, S. Saito, M. Nomura, K. Uchida, S. Shirakawa, CatCMA : Stochastic Optimization for Mixed-Category Problems, GECCO, 2024.](https://arxiv.org/abs/2405.09962)
* [Hamano et al. 2025] [R. Hamano, M. Nomura, S. Saito, K. Uchida, S. Shirakawa, CatCMA with Margin: Stochastic Optimization for Continuous, Integer, and Categorical Variables, GECCO, 2025.](https://arxiv.org/abs/2504.07884v5)
* [Hamano et al. 2026] [R. Hamano, M. Nomura, S. Saito, K. Uchida, S. Shirakawa, CatCMA with Margin for Single- and Multi-Objective Mixed-Variable Black-Box Optimization, arXiv:2504.07884, 2026.](https://arxiv.org/abs/2504.07884)
* [Hamano et al. 2024b] [R. Hamano, S. Shirakawa, M. Nomura, Natural Gradient Interpretation of Rank-One Update in CMA-ES, PPSN, 2024.](https://arxiv.org/abs/2406.16506)
* [Hansen 2016] [N. Hansen, The CMA Evolution Strategy: A Tutorial. arXiv:1604.00772, 2016.](https://arxiv.org/abs/1604.00772)
* [Nomura et al. 2021] [M. Nomura, S. Watanabe, Y. Akimoto, Y. Ozaki, M. Onishi, Warm Starting CMA-ES for Hyperparameter Optimization, AAAI, 2021.](https://arxiv.org/abs/2012.06932)
* [Nomura et al. 2023] [M. Nomura, Y. Akimoto, I. Ono, CMA-ES with Learning
Rate Adaptation: Can CMA-ES with Default Population Size Solve Multimodal
and Noisy Problems?, GECCO, 2023.](https://arxiv.org/abs/2304.03473)
* [Nomura et al. 2026] [M. Nomura, M. Shibata, R. Hamano, cmaes: A Simple yet Practical Python Library for CMA-ES, arXiv:2402.01373, 2026.](https://arxiv.org/abs/2402.01373)
* [Ros and Hansen 2008] [R. Ros, N. Hansen, A Simple Modification in CMA-ES Achieving Linear Time and Space Complexity, PPSN, 2008.](https://hal.inria.fr/inria-00287367/document)
* [Uchida et al. 2024a] [K. Uchida, R. Hamano, M. Nomura, S. Saito, S. Shirakawa, CMA-ES for Safe Optimization, GECCO, 2024.](https://arxiv.org/abs/2405.10534)
* [Uchida et al. 2024b] [K. Uchida, R. Hamano, M. Nomura, S. Saito, S. Shirakawa, CMA-ES for Discrete and Mixed-Variable Optimization on Sets of Points, PPSN, 2024.](https://arxiv.org/abs/2408.13046)
cmaes-0.13.1/benchmark/000077500000000000000000000000001524175644700146355ustar00rootroot00000000000000cmaes-0.13.1/benchmark/README.md000066400000000000000000000030521524175644700161140ustar00rootroot00000000000000# Continuous benchmarking using kurobako and GitHub Actions
Benchmark scripts are built on [kurobako](https://github.com/sile/kurobako).
See [Introduction to Kurobako: A Benchmark Tool for Hyperparameter Optimization Algorithms](https://medium.com/optuna/kurobako-a2e3f7b760c7) for more details.
## How to run benchmark scripts
GitHub Actions continuously run the benchmark scripts and comment on your pull request.
If you want to run on your local machines, please execute following after installed kurobako.
```console
$ ./benchmark/runner.sh -h
runner.sh is an entrypoint to run benchmarkers.
Usage:
$ runner.sh
Problem:
rosenbrock : https://www.sfu.ca/~ssurjano/rosen.html
six-hump-camel : https://www.sfu.ca/~ssurjano/camel6.html
himmelblau : https://en.wikipedia.org/wiki/Himmelblau%27s_function
ackley : https://www.sfu.ca/~ssurjano/ackley.html
rastrigin : https://www.sfu.ca/~ssurjano/rastr.html
Options:
--help, -h print this
Example:
$ runner.sh rosenbrock ./tmp/kurobako.json
$ cat ./tmp/kurobako.json | kurobako plot curve --errorbar -o ./tmp
$ ./benchmark/runner.sh rosenbrock ./tmp/kurobako.json
$ cat ./tmp/kurobako.json | kurobako plot curve --errorbar -o ./tmp
```
`kurobako plot curve` requires gnuplot. If you want to run on Docker container, please execute following:
```
$ docker pull sile/kurobako
$ ./benchmark/runner.sh rosenbrock ./tmp/kurobako.json
$ cat ./tmp/kurobako.json | docker run -v $PWD/tmp/images/:/images/ --rm -i sile/kurobako plot curve
```
cmaes-0.13.1/benchmark/optuna_solver.py000066400000000000000000000115771524175644700201220ustar00rootroot00000000000000import argparse
import optuna
import warnings
from kurobako import solver
from kurobako.solver.optuna import OptunaSolverFactory
warnings.filterwarnings(
"ignore",
category=optuna.exceptions.ExperimentalWarning,
module="optuna.samplers._cmaes",
)
parser = argparse.ArgumentParser()
parser.add_argument(
"sampler",
choices=["cmaes", "sep-cmaes", "ipop-cmaes", "ipop-sep-cmaes", "pycma", "ws-cmaes"],
)
parser.add_argument("--loglevel", choices=["debug", "info", "warning", "error"], default="warning")
parser.add_argument("--warm-starting-trials", type=int, default=0)
args = parser.parse_args()
if args.loglevel == "debug":
optuna.logging.set_verbosity(optuna.logging.DEBUG)
elif args.loglevel == "info":
optuna.logging.set_verbosity(optuna.logging.INFO)
elif args.loglevel == "warning":
optuna.logging.set_verbosity(optuna.logging.WARNING)
elif args.loglevel == "error":
optuna.logging.set_verbosity(optuna.logging.ERROR)
def create_cmaes_study(seed):
sampler = optuna.samplers.CmaEsSampler(seed=seed, warn_independent_sampling=True)
return optuna.create_study(sampler=sampler, pruner=optuna.pruners.NopPruner())
def create_sep_cmaes_study(seed):
sampler = optuna.samplers.CmaEsSampler(
seed=seed, warn_independent_sampling=True, use_separable_cma=True
)
return optuna.create_study(sampler=sampler, pruner=optuna.pruners.NopPruner())
def create_ipop_cmaes_study(seed):
sampler = optuna.samplers.CmaEsSampler(
seed=seed,
warn_independent_sampling=True,
restart_strategy="ipop",
inc_popsize=2,
)
return optuna.create_study(sampler=sampler, pruner=optuna.pruners.NopPruner())
def create_ipop_sep_cmaes_study(seed):
sampler = optuna.samplers.CmaEsSampler(
seed=seed,
warn_independent_sampling=True,
restart_strategy="ipop",
inc_popsize=2,
use_separable_cma=True,
)
return optuna.create_study(sampler=sampler, pruner=optuna.pruners.NopPruner())
def create_pycma_study(seed):
sampler = optuna.integration.PyCmaSampler(
seed=seed,
warn_independent_sampling=True,
)
return optuna.create_study(sampler=sampler, pruner=optuna.pruners.NopPruner())
class WarmStartingCmaEsSampler(optuna.samplers.BaseSampler):
def __init__(self, seed, warm_starting_trials: int) -> None:
self._seed = seed
self._warm_starting = True
self._warm_starting_trials = warm_starting_trials
self._sampler = optuna.samplers.RandomSampler(seed=seed)
self._source_trials = []
def infer_relative_search_space(self, study, trial):
return self._sampler.infer_relative_search_space(study, trial)
def sample_relative(
self,
study,
trial,
search_space,
):
return self._sampler.sample_relative(study, trial, search_space)
def sample_independent(self, study, trial, param_name, param_distribution):
return self._sampler.sample_independent(study, trial, param_name, param_distribution)
def after_trial(
self,
study,
trial,
state,
values,
):
if not self._warm_starting:
return self._sampler.after_trial(study, trial, state, values)
if len(self._source_trials) < self._warm_starting_trials:
assert state == optuna.trial.TrialState.PRUNED
self._source_trials.append(
optuna.create_trial(
params=trial.params,
distributions=trial.distributions,
values=values,
)
)
if len(self._source_trials) == self._warm_starting_trials:
self._sampler = optuna.samplers.CmaEsSampler(
seed=self._seed + 1, source_trials=self._source_trials or None
)
self._warm_starting = False
else:
return self._sampler.after_trial(study, trial, state, values)
def create_warm_start_study(seed):
sampler = WarmStartingCmaEsSampler(seed, args.warm_starting_trials)
return optuna.create_study(sampler=sampler, pruner=optuna.pruners.NopPruner())
if __name__ == "__main__":
if args.sampler == "cmaes":
factory = OptunaSolverFactory(create_cmaes_study)
elif args.sampler == "sep-cmaes":
factory = OptunaSolverFactory(create_sep_cmaes_study)
elif args.sampler == "ipop-cmaes":
factory = OptunaSolverFactory(create_ipop_cmaes_study)
elif args.sampler == "ipop-sep-cmaes":
factory = OptunaSolverFactory(create_ipop_sep_cmaes_study)
elif args.sampler == "pycma":
factory = OptunaSolverFactory(create_pycma_study)
elif args.sampler == "ws-cmaes":
factory = OptunaSolverFactory(
create_warm_start_study, warm_starting_trials=args.warm_starting_trials
)
else:
raise ValueError("unsupported sampler")
runner = solver.SolverRunner(factory)
runner.run()
cmaes-0.13.1/benchmark/problem_himmelblau.py000066400000000000000000000025241524175644700210510ustar00rootroot00000000000000from kurobako import problem
from kurobako.problem import Problem
from typing import List
from typing import Optional
class HimmelblauEvaluator(problem.Evaluator):
def __init__(self, params: List[Optional[float]]):
self._x1, self._x2 = params
self._current_step = 0
def evaluate(self, next_step: int) -> List[float]:
self._current_step = 1
value = (self._x1**2 + self._x2 - 11.0) ** 2 + (self._x1 + self._x2**2 - 7.0) ** 2
return [value]
def current_step(self) -> int:
return self._current_step
class HimmelblauProblem(problem.Problem):
def create_evaluator(self, params: List[Optional[float]]) -> Optional[problem.Evaluator]:
return HimmelblauEvaluator(params)
class HimmelblauProblemFactory(problem.ProblemFactory):
def create_problem(self, seed: int) -> Problem:
return HimmelblauProblem()
def specification(self) -> problem.ProblemSpec:
params = [
problem.Var("x1", problem.ContinuousRange(-4, 4)),
problem.Var("x2", problem.ContinuousRange(-4, 4)),
]
return problem.ProblemSpec(
name="Himmelblau Function",
params=params,
values=[problem.Var("Himmelblau")],
)
if __name__ == "__main__":
runner = problem.ProblemRunner(HimmelblauProblemFactory())
runner.run()
cmaes-0.13.1/benchmark/problem_rastrigin.py000066400000000000000000000027511524175644700207360ustar00rootroot00000000000000import sys
import numpy as np
from kurobako import problem
from kurobako.problem import Problem
from typing import List
from typing import Optional
class RastriginEvaluator(problem.Evaluator):
def __init__(self, params: List[Optional[float]]):
self.n = len(params)
self.x = np.array(params, dtype=float)
self._current_step = 0
def evaluate(self, next_step: int) -> List[float]:
self._current_step = 1
value = 10 * self.n + np.sum(self.x**2 - 10 * np.cos(2 * np.pi * self.x))
return [value]
def current_step(self) -> int:
return self._current_step
class RastriginProblem(problem.Problem):
def create_evaluator(self, params: List[Optional[float]]) -> Optional[problem.Evaluator]:
return RastriginEvaluator(params)
class RastriginProblemFactory(problem.ProblemFactory):
def __init__(self, dim):
self.dim = dim
def create_problem(self, seed: int) -> Problem:
return RastriginProblem()
def specification(self) -> problem.ProblemSpec:
params = [
problem.Var(f"x{i + 1}", problem.ContinuousRange(-5.12, 5.12)) for i in range(self.dim)
]
return problem.ProblemSpec(
name=f"Rastrigin (dim={self.dim})",
params=params,
values=[problem.Var("Rastrigin")],
)
if __name__ == "__main__":
dim = int(sys.argv[1]) if len(sys.argv) == 2 else 2
runner = problem.ProblemRunner(RastriginProblemFactory(dim))
runner.run()
cmaes-0.13.1/benchmark/problem_rosenbrock.py000066400000000000000000000026061524175644700211020ustar00rootroot00000000000000from kurobako import problem
from kurobako.problem import Problem
from typing import List
from typing import Optional
class RosenbrockEvaluator(problem.Evaluator):
"""
See https://www.sfu.ca/~ssurjano/rosen.html
"""
def __init__(self, params: List[Optional[float]]):
self._x1, self._x2 = params
self._current_step = 0
def evaluate(self, next_step: int) -> List[float]:
self._current_step = 1
value = 100 * (self._x2 - self._x1**2) ** 2 + (self._x1 - 1) ** 2
return [value]
def current_step(self) -> int:
return self._current_step
class RosenbrockProblem(problem.Problem):
def create_evaluator(self, params: List[Optional[float]]) -> Optional[problem.Evaluator]:
return RosenbrockEvaluator(params)
class RosenbrockProblemFactory(problem.ProblemFactory):
def create_problem(self, seed: int) -> Problem:
return RosenbrockProblem()
def specification(self) -> problem.ProblemSpec:
params = [
problem.Var("x1", problem.ContinuousRange(-5, 10)),
problem.Var("x2", problem.ContinuousRange(-5, 10)),
]
return problem.ProblemSpec(
name="Rosenbrock Function",
params=params,
values=[problem.Var("Rosenbrock")],
)
if __name__ == "__main__":
runner = problem.ProblemRunner(RosenbrockProblemFactory())
runner.run()
cmaes-0.13.1/benchmark/problem_six_hump_camel.py000066400000000000000000000030161524175644700217240ustar00rootroot00000000000000from kurobako import problem
from kurobako.problem import Problem
from typing import List
from typing import Optional
class SixHumpCamelEvaluator(problem.Evaluator):
"""
See https://www.sfu.ca/~ssurjano/camel6.html
"""
def __init__(self, params: List[Optional[float]]):
self._x1, self._x2 = params
self._current_step = 0
def evaluate(self, next_step: int) -> List[float]:
self._current_step = 1
value = (
(4 - 2.1 * (self._x1**2) + (self._x1**4) / 3) * (self._x1**2)
+ self._x1 * self._x2
+ (-4 + 4 * self._x2**2) * (self._x2**2)
)
return [value]
def current_step(self) -> int:
return self._current_step
class SixHumpCamelProblem(problem.Problem):
def create_evaluator(self, params: List[Optional[float]]) -> Optional[problem.Evaluator]:
return SixHumpCamelEvaluator(params)
class SixHumpCamelProblemFactory(problem.ProblemFactory):
def create_problem(self, seed: int) -> Problem:
return SixHumpCamelProblem()
def specification(self) -> problem.ProblemSpec:
params = [
problem.Var("x1", problem.ContinuousRange(-5, 10)),
problem.Var("x2", problem.ContinuousRange(-5, 10)),
]
return problem.ProblemSpec(
name="Six-Hump Camel Function",
params=params,
values=[problem.Var("Six-Hump Camel")],
)
if __name__ == "__main__":
runner = problem.ProblemRunner(SixHumpCamelProblemFactory())
runner.run()
cmaes-0.13.1/benchmark/problem_sphere.py000066400000000000000000000026561524175644700202260ustar00rootroot00000000000000from __future__ import annotations
import sys
import numpy as np
from kurobako import problem
from kurobako.problem import Problem
from typing import Optional
class SphereEvaluator(problem.Evaluator):
def __init__(self, params: list[Optional[float]]):
self.n = len(params)
self.x = np.array(params, dtype=float)
self._current_step = 0
def evaluate(self, next_step: int) -> list[float]:
self._current_step = 1
value = np.mean(self.x**2)
return [value]
def current_step(self) -> int:
return self._current_step
class SphereProblem(problem.Problem):
def create_evaluator(self, params: list[Optional[float]]) -> Optional[problem.Evaluator]:
return SphereEvaluator(params)
class SphereProblemFactory(problem.ProblemFactory):
def __init__(self, dim):
self.dim = dim
def create_problem(self, seed: int) -> Problem:
return SphereProblem()
def specification(self) -> problem.ProblemSpec:
params = [
problem.Var(f"x{i + 1}", problem.ContinuousRange(-5.12, 5.12)) for i in range(self.dim)
]
return problem.ProblemSpec(
name=f"Sphere (dim={self.dim})",
params=params,
values=[problem.Var("Sphere")],
)
if __name__ == "__main__":
dim = int(sys.argv[1]) if len(sys.argv) == 2 else 2
runner = problem.ProblemRunner(SphereProblemFactory(dim))
runner.run()
cmaes-0.13.1/benchmark/runner.sh000077500000000000000000000060741524175644700165140ustar00rootroot00000000000000#!/bin/sh
set -e
KUROBAKO=${KUROBAKO:-kurobako}
DIR=$(cd $(dirname $0); pwd)
REPEATS=${REPEATS:-5}
BUDGET=${BUDGET:-300}
SEED=${SEED:-1}
DIM=${DIM:-2}
SURROGATE_ROOT=${SURROGATE_ROOT:-$(dirname $DIR)/tmp/surrogate-models}
WARM_START=${WARM_START:-0}
usage() {
cat <
Problem:
rosenbrock : https://www.sfu.ca/~ssurjano/rosen.html
six-hump-camel : https://www.sfu.ca/~ssurjano/camel6.html
himmelblau : https://en.wikipedia.org/wiki/Himmelblau%27s_function
ackley : https://www.sfu.ca/~ssurjano/ackley.html
rastrigin : https://www.sfu.ca/~ssurjano/rastr.html
sphere : https://www.sfu.ca/~ssurjano/spheref.html
toxic-lightgbm : https://github.com/c-bata/benchmark-warm-starting-cmaes
Options:
--help, -h print this
Example:
$ $(basename ${0}) rosenbrock ./tmp/kurobako.json
$ cat ./tmp/kurobako.json | kurobako plot curve --errorbar -o ./tmp
EOF
}
case "$1" in
himmelblau)
PROBLEM=$($KUROBAKO problem command python $DIR/problem_himmelblau.py)
;;
rosenbrock)
PROBLEM=$($KUROBAKO problem command python $DIR/problem_rosenbrock.py)
;;
six-hump-camel)
PROBLEM=$($KUROBAKO problem command python $DIR/problem_six_hump_camel.py)
;;
ackley)
PROBLEM=$($KUROBAKO problem sigopt --dim $DIM ackley)
;;
rastrigin)
# "kurobako problem sigopt --dim 8 rastrigin" only accepts 8-dim.
PROBLEM=$($KUROBAKO problem command python $DIR/problem_rastrigin.py $DIM)
;;
sphere)
# "kurobako problem sigopt --dim 8 rastrigin" only accepts 8-dim.
PROBLEM=$($KUROBAKO problem command python $DIR/problem_sphere.py $DIM)
;;
toxic-lightgbm)
PROBLEM=$($KUROBAKO problem warm-starting \
$($KUROBAKO problem surrogate $SURROGATE_ROOT/wscmaes-toxic-source/) \
$($KUROBAKO problem surrogate $SURROGATE_ROOT/wscmaes-toxic-target/))
;;
help|--help|-h)
usage
exit 0
;;
*)
echo "[Error] Invalid problem '${1}'"
usage
exit 1
;;
esac
RANDOM_SOLVER=$($KUROBAKO solver random)
CMAES_SOLVER=$($KUROBAKO solver --name 'cmaes' command -- python $DIR/optuna_solver.py cmaes)
SEP_CMAES_SOLVER=$($KUROBAKO solver --name 'sep-cmaes' command -- python $DIR/optuna_solver.py sep-cmaes)
IPOP_CMAES_SOLVER=$($KUROBAKO solver --name 'ipop-cmaes' command -- python $DIR/optuna_solver.py ipop-cmaes)
IPOP_SEP_CMAES_SOLVER=$($KUROBAKO solver --name 'ipop-sep-cmaes' command -- python $DIR/optuna_solver.py ipop-sep-cmaes)
PYCMA_SOLVER=$($KUROBAKO solver --name 'pycma' command -- python $DIR/optuna_solver.py pycma)
WS_CMAES_SOLVER=$($KUROBAKO solver --name 'ws-cmaes' command -- python $DIR/optuna_solver.py ws-cmaes --warm-starting-trials $WARM_START)
$KUROBAKO studies \
--solvers $RANDOM_SOLVER $CMAES_SOLVER $PYCMA_SOLVER \
--problems $PROBLEM \
--seed $SEED --repeats $REPEATS --budget $BUDGET \
| $KUROBAKO run --parallelism 6 > $2
cmaes-0.13.1/cmaes/000077500000000000000000000000001524175644700137735ustar00rootroot00000000000000cmaes-0.13.1/cmaes/__init__.py000066400000000000000000000006261524175644700161100ustar00rootroot00000000000000from ._cma import CMA # NOQA
from ._sepcma import SepCMA # NOQA
from ._warm_start import get_warm_start_mgd # NOQA
from ._cmawm import CMAwM # NOQA
from ._xnes import XNES # NOQA
from ._dxnesic import DXNESIC # NOQA
from ._catcma import CatCMA # NOQA
from ._mapcma import MAPCMA # NOQA
from ._catcmawm import CatCMAwM # NOQA
from ._comocatcmawm import COMOCatCMAwM # NOQA
__version__ = "0.13.1"
cmaes-0.13.1/cmaes/_catcma.py000066400000000000000000000434221524175644700157410ustar00rootroot00000000000000from __future__ import annotations
import math
import numpy as np
from typing import Any
from typing import cast
from typing import Optional
_EPS = 1e-8
_MEAN_MAX = 1e32
_SIGMA_MAX = 1e32
class CatCMA:
"""CatCMA stochastic optimizer class with ask-and-tell interface.
Example:
.. code::
import numpy as np
from cmaes import CatCMA
def sphere_com(x, c):
return sum(x*x) + len(c) - sum(c[:,0])
optimizer = CatCMA(mean=3 * np.ones(3), sigma=2.0, cat_num=np.array([3, 3, 3]))
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x, c = optimizer.ask()
value = sphere_com(x, c)
solutions.append(((x, c), value))
print(f"#{generation} {value}")
# Tell evaluation values.
optimizer.tell(solutions)
Args:
mean:
Initial mean vector of multivariate gaussian distribution.
sigma:
Initial standard deviation of covariance matrix.
cat_num:
Numbers of categories.
bounds:
Lower and upper domain boundaries for each parameter (optional).
n_max_resampling:
A maximum number of resampling parameters (default: 100).
If all sampled parameters are infeasible, the last sampled one
will be clipped with lower and upper bounds.
seed:
A seed number (optional).
population_size:
A population size (optional).
cov:
A covariance matrix (optional).
cat_param:
A parameter of categorical distribution (optional).
margin:
A margin (lower bound) of categorical distribution (optional).
min_eigenvalue:
Lower bound of eigenvalue of multivariate Gaussian distribution (optional).
"""
# Paper: https://arxiv.org/abs/2405.09962
def __init__(
self,
mean: np.ndarray,
sigma: float,
cat_num: np.ndarray,
bounds: Optional[np.ndarray] = None,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
cov: Optional[np.ndarray] = None,
cat_param: Optional[np.ndarray] = None,
margin: Optional[np.ndarray] = None,
min_eigenvalue: Optional[float] = None,
):
assert sigma > 0, "sigma must be non-zero positive value"
assert np.all(np.abs(mean) < _MEAN_MAX), (
f"Abs of all elements of mean vector must be less than {_MEAN_MAX}"
)
self._n_co = len(mean)
self._n_ca = len(cat_num)
self._n = self._n_co + self._n_ca
assert self._n_co > 1, "The dimension of mean must be larger than 1"
assert self._n_ca > 0, "The dimension of categorical variable must be positive"
assert np.all(cat_num > 1), "The number of categories must be larger than 1"
if population_size is None:
population_size = 4 + math.floor(3 * math.log(self._n))
assert population_size > 0, "popsize must be non-zero positive value."
mu = population_size // 2
# CatCMA assumes that the weights of the lower half are zero.
# (CMA uses negative weights while CatCMA uses positive weights.)
weights_prime = np.array(
[
math.log((population_size + 1) / 2) - math.log(i + 1) if i < mu else 0
for i in range(population_size)
]
)
weights = weights_prime / weights_prime.sum()
mu_eff = 1 / ((weights**2).sum())
# learning rate for the rank-one update
alpha_cov = 2
c1 = alpha_cov / ((self._n_co + 1.3) ** 2 + mu_eff)
# learning rate for the rank-μ update
cmu = min(
1 - c1 - 1e-8, # 1e-8 is for large popsize.
alpha_cov
* (mu_eff - 2 + 1 / mu_eff)
/ ((self._n_co + 2) ** 2 + alpha_cov * mu_eff / 2),
)
assert c1 <= 1 - cmu, "invalid learning rate for the rank-one update"
assert cmu <= 1 - c1, "invalid learning rate for the rank-μ update"
cm = 1
# learning rate for the cumulation for the step-size control
c_sigma = (mu_eff + 2) / (self._n_co + mu_eff + 5)
d_sigma = 1 + 2 * max(0, math.sqrt((mu_eff - 1) / (self._n_co + 1)) - 1) + c_sigma
assert c_sigma < 1, "invalid learning rate for cumulation for the step-size control"
# learning rate for cumulation for the rank-one update
cc = (4 + mu_eff / self._n_co) / (self._n_co + 4 + 2 * mu_eff / self._n_co)
assert cc <= 1, "invalid learning rate for cumulation for the rank-one update"
self._popsize = population_size
self._mu = mu
self._mu_eff = mu_eff
self._cc = cc
self._c1 = c1
self._cmu = cmu
self._c_sigma = c_sigma
self._d_sigma = d_sigma
self._cm = cm
# E||N(0, I)||
self._chi_n = math.sqrt(self._n_co) * (
1.0 - (1.0 / (4.0 * self._n_co)) + 1.0 / (21.0 * (self._n_co**2))
)
self._weights = weights
# evolution path
self._p_sigma = np.zeros(self._n_co)
self._pc = np.zeros(self._n_co)
self._mean = mean.copy()
if cov is None:
self._C = np.eye(self._n_co)
else:
assert cov.shape == (
self._n_co,
self._n_co,
), "Invalid shape of covariance matrix"
self._C = cov
self._sigma = sigma
self._D: Optional[np.ndarray] = None
self._B: Optional[np.ndarray] = None
# categorical distribution
# Parameters in categorical distribution with fewer categories
# must be zero-padded at the end.
self._K = cat_num
self._Kmax = np.max(self._K)
if cat_param is None:
self._q = np.zeros((self._n_ca, self._Kmax))
for i in range(self._n_ca):
self._q[i, : self._K[i]] = 1 / self._K[i]
else:
assert cat_param.shape == (
self._n_ca,
self._Kmax,
), "Invalid shape of categorical distribution parameter"
for i in range(self._n_ca):
assert np.all(cat_param[i, self._K[i] :] == 0), (
"Parameters in categorical distribution with fewer categories "
"must be zero-padded at the end"
)
assert np.all((cat_param >= 0) & (cat_param <= 1)), (
"All elements in categorical distribution parameter must be between 0 and 1"
)
assert np.allclose(np.sum(cat_param, axis=1), 1), (
"Each row in categorical distribution parameter must sum to 1"
)
self._q = cat_param
self._q_min = (
margin if margin is not None else (1 - 0.73 ** (1 / self._n_ca)) / (self._K - 1)
)
self._min_eigenvalue = min_eigenvalue if min_eigenvalue is not None else 1e-30
# ASNG
self._param_sum = np.sum(cat_num - 1)
self._alpha = 1.5
self._delta_init = 1.0
self._Delta = 1.0
self._Delta_max = np.inf
self._gamma = 0.0
self._s = np.zeros(self._param_sum)
self._delta = self._delta_init / self._Delta
self._eps = self._delta
# bounds contains low and high of each parameter.
assert bounds is None or _is_valid_bounds(bounds, mean), "invalid bounds"
self._bounds = bounds
self._n_max_resampling = n_max_resampling
self._g = 0
self._rng = np.random.RandomState(seed)
# Termination criteria
self._tolxup = 1e4
self._tolfun = 1e-12
self._tolconditioncov = 1e14
self._funhist_term = 10 + math.ceil(30 * self._n_co / population_size)
self._funhist_values = np.empty(self._funhist_term)
def __getstate__(self) -> dict[str, Any]:
attrs = {}
for name in self.__dict__:
# Remove _rng in pickle serialized object.
if name == "_rng":
continue
if name == "_C":
sym1d = _compress_symmetric(self._C)
attrs["_c_1d"] = sym1d
continue
attrs[name] = getattr(self, name)
return attrs
def __setstate__(self, state: dict[str, Any]) -> None:
state["_C"] = _decompress_symmetric(state["_c_1d"])
del state["_c_1d"]
self.__dict__.update(state)
# Set _rng for unpickled object.
setattr(self, "_rng", np.random.RandomState())
@property
def cont_dim(self) -> int:
"""A number of dimensions of continuous variable"""
return self._n_co
@property
def cat_dim(self) -> int:
"""A number of dimensions of categorical variable"""
return self._n_ca
@property
def dim(self) -> int:
"""A number of dimensions"""
return self._n
@property
def cat_num(self) -> np.ndarray:
"""Numbers of categories"""
return self._K
@property
def population_size(self) -> int:
"""A population size"""
return self._popsize
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when multi-variate gaussian distribution is updated."""
return self._g
@property
def mean(self) -> np.ndarray:
"""Mean Vector"""
return self._mean
def reseed_rng(self, seed: int) -> None:
self._rng.seed(seed)
def set_bounds(self, bounds: Optional[np.ndarray]) -> None:
"""Update boundary constraints"""
assert bounds is None or _is_valid_bounds(bounds, self._mean), "invalid bounds"
self._bounds = bounds
def ask(self) -> tuple[np.ndarray, np.ndarray]:
"""Sample a parameter"""
for i in range(self._n_max_resampling):
x, c = self._sample_solution()
if self._is_feasible(x):
return x, c
x, c = self._sample_solution()
x = self._repair_infeasible_params(x)
return x, c
def _eigen_decomposition(self) -> tuple[np.ndarray, np.ndarray]:
if self._B is not None and self._D is not None:
return self._B, self._D
self._C = (self._C + self._C.T) / 2
D2, B = np.linalg.eigh(self._C)
D = np.sqrt(np.where(D2 < 0, _EPS, D2))
self._C = np.dot(np.dot(B, np.diag(D**2)), B.T)
self._B, self._D = B, D
return B, D
def _sample_solution(self) -> tuple[np.ndarray, np.ndarray]:
# x : continuous variable
B, D = self._eigen_decomposition()
z = self._rng.randn(self._n_co) # ~ N(0, I)
y = cast(np.ndarray, B.dot(np.diag(D))).dot(z) # ~ N(0, C)
x = self._mean + self._sigma * y # ~ N(m, σ^2 C)
# c : categorical variable
# Categorical variables are one-hot encoded.
# Variables with fewer categories are zero-padded at the end.
rand_q = self._rng.rand(self._n_ca, 1)
cum_q = self._q.cumsum(axis=1)
c = (cum_q - self._q <= rand_q) & (rand_q < cum_q)
return x, c
def _is_feasible(self, param: np.ndarray) -> bool:
if self._bounds is None:
return True
return cast(
bool,
np.all(param >= self._bounds[:, 0]) and np.all(param <= self._bounds[:, 1]),
) # Cast bool_ to bool.
def _repair_infeasible_params(self, param: np.ndarray) -> np.ndarray:
if self._bounds is None:
return param
# clip with lower and upper bound.
param = np.where(param < self._bounds[:, 0], self._bounds[:, 0], param)
param = np.where(param > self._bounds[:, 1], self._bounds[:, 1], param)
return param
def tell(self, solutions: list[tuple[tuple[np.ndarray, np.ndarray], float]]) -> None:
"""Tell evaluation values"""
assert len(solutions) == self._popsize, "Must tell popsize-length solutions."
for s in solutions:
assert np.all(np.abs(s[0][0]) < _MEAN_MAX), (
f"Abs of all param values must be less than {_MEAN_MAX} to avoid overflow errors"
)
self._g += 1
solutions.sort(key=lambda s: s[1])
# Stores best evaluation values of the
# last 'self._funhist_term' generations.
funhist_idx = self.generation % self._funhist_term
self._funhist_values[funhist_idx] = solutions[0][1]
# Sample new population of search_points, for k=1, ..., popsize
B, D = self._eigen_decomposition()
self._B, self._D = None, None
x_k = np.array([s[0][0] for s in solutions]) # ~ N(m, σ^2 C)
y_k = (x_k - self._mean) / self._sigma # ~ N(0, C)
# Selection and recombination
y_w = np.sum(y_k[: self._mu].T * self._weights[: self._mu], axis=1)
self._mean += self._cm * self._sigma * y_w
# Step-size control
C_2 = cast(
np.ndarray, cast(np.ndarray, B.dot(np.diag(1 / D))).dot(B.T)
) # C^(-1/2) = B D^(-1) B^T
self._p_sigma = (1 - self._c_sigma) * self._p_sigma + math.sqrt(
self._c_sigma * (2 - self._c_sigma) * self._mu_eff
) * C_2.dot(y_w)
norm_p_sigma = np.linalg.norm(self._p_sigma)
self._sigma *= np.exp((self._c_sigma / self._d_sigma) * (norm_p_sigma / self._chi_n - 1))
self._sigma = min(self._sigma, _SIGMA_MAX)
# Covariance matrix adaption
h_sigma_cond_left = norm_p_sigma / math.sqrt(
1 - (1 - self._c_sigma) ** (2 * (self._g + 1))
)
h_sigma_cond_right = (1.4 + 2 / (self._n_co + 1)) * self._chi_n
h_sigma = 1.0 if h_sigma_cond_left < h_sigma_cond_right else 0.0
self._pc = (1 - self._cc) * self._pc + h_sigma * math.sqrt(
self._cc * (2 - self._cc) * self._mu_eff
) * y_w
delta_h_sigma = (1 - h_sigma) * self._cc * (2 - self._cc)
assert delta_h_sigma <= 1
rank_one = np.outer(self._pc, self._pc)
rank_mu = np.sum(
np.array([w * np.outer(y, y) for w, y in zip(self._weights, y_k)]), axis=0
)
self._C = (
(1 + self._c1 * delta_h_sigma - self._c1 - self._cmu * np.sum(self._weights)) * self._C
+ self._c1 * rank_one
+ self._cmu * rank_mu
)
# Post-processing to prevent the minimum eigenvalue from becoming too small
B, D = self._eigen_decomposition()
sigma_min = np.sqrt(self._min_eigenvalue / np.min(D))
self._sigma = max(self._sigma, sigma_min)
# Update of categorical distribution
c = np.array([s[0][1] for s in solutions])
ngrad = (self._weights[:, np.newaxis, np.newaxis] * (c - self._q)).sum(axis=0)
# Approximation of the square root of the fisher information matrix :
# Appendix B in https://proceedings.mlr.press/v97/akimoto19a.html
sl = []
for i, K in enumerate(self._K):
q_i = self._q[i, : K - 1]
q_i_K = self._q[i, K - 1]
s_i = 1.0 / np.sqrt(q_i) * ngrad[i, : K - 1]
s_i += np.sqrt(q_i) * ngrad[i, : K - 1].sum() / (q_i_K + np.sqrt(q_i_K))
sl += list(s_i)
ngrad_sqF = np.array(sl)
pnorm = np.sqrt(np.dot(ngrad_sqF, ngrad_sqF)) + 1e-30
self._eps = self._delta / pnorm
self._q += self._eps * ngrad
# Update of ASNG
self._delta = self._delta_init / self._Delta
beta = self._delta / (self._param_sum**0.5)
self._s = (1 - beta) * self._s + np.sqrt(beta * (2 - beta)) * ngrad_sqF / pnorm
self._gamma = (1 - beta) ** 2 * self._gamma + beta * (2 - beta)
self._Delta *= np.exp(beta * (self._gamma - np.dot(self._s, self._s) / self._alpha))
self._Delta = min(self._Delta, self._Delta_max)
# Margin Correction
for i in range(self._n_ca):
Ki = self._K[i]
self._q[i, :Ki] = np.maximum(self._q[i, :Ki], self._q_min[i])
q_sum = self._q[i, :Ki].sum()
tmp = q_sum - self._q_min[i] * Ki
self._q[i, :Ki] -= (q_sum - 1) * (self._q[i, :Ki] - self._q_min[i]) / tmp
self._q[i, :Ki] /= self._q[i, :Ki].sum()
def should_stop(self) -> bool:
B, D = self._eigen_decomposition()
# Stop if the range of function values of the recent generation is below tolfun.
if (
self.generation > self._funhist_term
and np.max(self._funhist_values) - np.min(self._funhist_values) < self._tolfun
):
return True
# Stop if detecting divergent behavior.
if self._sigma * np.max(D) > self._tolxup:
return True
# Stop if the condition number of the covariance matrix exceeds 1e14.
condition_cov = np.max(D) / np.min(D)
if condition_cov > self._tolconditioncov:
return True
return False
def _is_valid_bounds(bounds: Optional[np.ndarray], mean: np.ndarray) -> bool:
if bounds is None:
return True
if (mean.size, 2) != bounds.shape:
return False
if not np.all(bounds[:, 0] <= mean):
return False
if not np.all(mean <= bounds[:, 1]):
return False
return True
def _compress_symmetric(sym2d: np.ndarray) -> np.ndarray:
assert len(sym2d.shape) == 2 and sym2d.shape[0] == sym2d.shape[1]
n = sym2d.shape[0]
dim = (n * (n + 1)) // 2
sym1d = np.zeros(dim)
start = 0
for i in range(n):
sym1d[start : start + n - i] = sym2d[i][i:] # noqa: E203
start += n - i
return sym1d
def _decompress_symmetric(sym1d: np.ndarray) -> np.ndarray:
n = int(np.sqrt(sym1d.size * 2))
assert (n * (n + 1)) // 2 == sym1d.size
R, C = np.triu_indices(n)
out = np.zeros((n, n), dtype=sym1d.dtype)
out[R, C] = sym1d
out[C, R] = sym1d
return out
cmaes-0.13.1/cmaes/_catcmawm.py000066400000000000000000001100321524175644700162750ustar00rootroot00000000000000from __future__ import annotations
import functools
import numpy as np
import math
from dataclasses import dataclass, field
from typing import cast
from typing import List, Sequence, Union, Tuple, Optional
import warnings
try:
from scipy import stats
chi2_ppf = functools.partial(stats.chi2.ppf, df=1)
norm_cdf = stats.norm.cdf
except ImportError:
from cmaes._stats import chi2_ppf # type: ignore
from cmaes._stats import norm_cdf
_EPS = 1e-8
_MEAN_MAX = 1e32
_SIGMA_MAX = 1e32
class CatCMAwM:
"""CatCMA with Margin stochastic optimizer class with ask-and-tell interface.
Example:
.. code::
import numpy as np
from cmaes import CatCMAwM
def SphereIntCOM(x, z, c):
return sum(x*x) + sum(z*z) + len(c) - sum(c[:,0])
X = [[-3.0, 3.0], [-4.0, 4.0]]
Z = [[-1, 0, 1], [-2, -1, 0, 1, 2]]
C = [5, 6]
optimizer = CatCMAwM(x_space=X, z_space=Z, c_space=C)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
sol = optimizer.ask()
value = SphereIntCOM(sol.x, sol.z, sol.c)
print(f"#{generation} {value}")
solutions.append((sol, value))
# Tell evaluation values
optimizer.tell(solutions)
Args:
x_space:
The search space for continuous variables.
Provide as a 2-dimensional sequence (e.g., a list of lists),
where each row is [lower_bound, upper_bound] for a continuous variable.
If there are no continuous variables, this parameter can be omitted.
Example: [[-3.0, 3.0], [0.0, 5.0], [-np.inf, np.inf]]
z_space:
The set of possible values for each integer variable.
Provide as a list of lists, where each inner list contains the valid
(sorted) integer or discretized values for that variable.
If there are no integer variables, this parameter can be omitted.
Example: [[-2, -1, 0, 1, 2], [0.01, 0.1, 1]]
Note: For binary variables (i.e., variables that can only take two distinct values),
it is generally recommended to use the categorical variable representation via
`c_space` rather than treating them as integer variables.
c_space:
The shape of the categorical variables' domain.
Provide as a 1-dimensional sequence (e.g., a list)
where each element specifies the number of categories (integer > 1)
for each categorical variable.
If there are no categorical variables, this parameter can be omitted.
Example: [3, 3, 2, 10]
Note: Binary variables (with only two possible values) should be represented as
categorical variables here, rather than as integer variables in `z_space`.
population_size:
A population size (optional).
mean:
Initial mean vector of multivariate gaussian distribution (optional).
sigma:
Initial step-size of multivariate gaussian distribution (optional).
cov:
Initial covariance matrix of multivariate gaussian distribution (optional).
cat_param:
Initial parameter of categorical distribution (optional).
seed:
A seed number (optional).
"""
# Paper: https://arxiv.org/abs/2504.07884v5
@dataclass(frozen=True)
class Solution:
x: Optional[np.ndarray] = None # continuous variable
z: Optional[np.ndarray] = None # integer variable
c: Optional[np.ndarray] = None # categorical variable
_v_raw: Optional[np.ndarray] = field(default=None, repr=False) # internal use
def __init__(
self,
x_space: Optional[Sequence[Sequence[float]]] = None,
z_space: Optional[Sequence[Sequence[Union[int, float]]]] = None,
c_space: Optional[Sequence[int]] = None,
population_size: Optional[int] = None,
mean: Optional[np.ndarray] = None,
sigma: Optional[float] = None,
cov: Optional[np.ndarray] = None,
cat_param: Optional[np.ndarray] = None,
seed: Optional[int] = None,
):
# Determine space sizes
self._Nco = len(x_space) if x_space is not None else 0
self._Nin = len(z_space) if z_space is not None else 0
self._Nca = len(c_space) if c_space is not None else 0
self._Nmi = self._Nco + self._Nin
if self._Nmi + self._Nca <= 0:
raise ValueError("The total number of dimensions must be positive.")
self._use_continuous = self._Nco > 0
self._use_integer = self._Nin > 0
self._use_gaussian = self._Nmi > 0
self._use_categorical = self._Nca > 0
self._continuous_idx = np.arange(self._Nco)
self._discrete_idx = np.arange(self._Nco, self._Nmi)
if population_size is None:
population_size = 4 + math.floor(3 * math.log(self._Nmi + self._Nca))
if population_size <= 0:
raise ValueError("population_size must be non-zero positive value.")
self._popsize = population_size
# --- CMA-ES weight (active covariance matrix adaptation) ---
self._mu = self._popsize // 2
weights_prime = np.array(
[math.log((self._popsize + 1) / 2) - math.log(i + 1) for i in range(self._popsize)]
)
self._mu_eff = (np.sum(weights_prime[: self._mu]) ** 2) / np.sum(
weights_prime[: self._mu] ** 2
)
mu_eff_minus = (np.sum(weights_prime[self._mu :]) ** 2) / np.sum(
weights_prime[self._mu :] ** 2
)
# learning rate for the rank-one update
alpha_cov = 2
self._c1 = alpha_cov / ((self._Nmi + 1.3) ** 2 + self._mu_eff)
# learning rate for the rank-μ update
self._cmu = min(
1 - self._c1 - _EPS, # _EPS is for large popsize.
alpha_cov
* (self._mu_eff - 2 + 1 / self._mu_eff)
/ ((self._Nmi + 2) ** 2 + alpha_cov * self._mu_eff / 2),
)
assert self._c1 <= 1 - self._cmu, "Invalid learning rate for the rank-one update."
assert self._cmu <= 1 - self._c1, "Invalid learning rate for the rank-μ update."
min_alpha = (
0
if self._Nmi == 0
else min(
1 + self._c1 / self._cmu,
1 + (2 * mu_eff_minus) / (self._mu_eff + 2),
(1 - self._c1 - self._cmu) / (self._Nmi * self._cmu),
)
)
# TODO: Handle ranking ties when computing weights.
positive_sum = np.sum(weights_prime[weights_prime > 0])
negative_sum = np.sum(np.abs(weights_prime[weights_prime < 0]))
self._weights = np.where(
weights_prime >= 0,
1 / positive_sum * weights_prime,
min_alpha / negative_sum * weights_prime,
)
# generation number
self._g = 0
self._rng = np.random.RandomState(seed)
# --- initialization for each domain ---
if self._use_integer:
self._init_discretization(z_space)
if self._use_gaussian:
self._init_gaussian(x_space, mean, sigma, cov)
if self._use_categorical:
self._init_categorical(c_space, cat_param)
def _init_discretization(
self,
z_space: Optional[Sequence[Sequence[Union[int, float]]]],
) -> None:
assert z_space is not None, "z_space must not be None for integer variables."
for i, row in enumerate(z_space):
if len(row) < 2:
raise ValueError(
f"z_space must be a sequence of arrays with length >= 2. "
f"Found length {len(row)} at index {i}: {row}"
)
if len(set(row)) < len(row):
raise ValueError(
f"Elements in each array of z_space must be unique. "
f"Found duplicate at index {i}: {row}"
)
# Pad the row with its maximum value to reach the maximum row length
max_length = max(len(row) for row in z_space)
self._z_space = np.array(
[
np.pad(
np.array(sr),
pad_width=(0, max_length - len(sr)),
mode="constant",
constant_values=(sr[-1]),
)
for row in z_space
for sr in [sorted(row)]
]
)
# discretization thresholds
self._z_lim = (self._z_space[:, 1:] + self._z_space[:, :-1]) / 2
# margin value for integer variables
self._alpha = 1 - 0.73 ** (1 / (self._Nin + self._Nca))
# mutation rates for integer variables
self._pmut = (0.5 - _EPS) * np.ones(self._Nin)
# successful integer mutation
self._int_succ = np.zeros(self._Nin, dtype=bool)
def _init_gaussian(
self,
x_space: Optional[Sequence[Sequence[float]]],
mean: Optional[np.ndarray],
sigma: Optional[float],
cov: Optional[np.ndarray],
) -> None:
if x_space is not None:
self._x_space = np.asarray(x_space, dtype=float)
if self._x_space.ndim != 2 or self._x_space.shape[1] != 2:
raise ValueError(
f"x_space must be a two-dimensional array with shape (n, 2), "
f"but got shape {self._x_space.shape}."
)
invalid = np.where(self._x_space[:, 0] >= self._x_space[:, 1])[0]
if invalid.size > 0:
i = invalid[0]
lb, ub = self._x_space[i, 0], self._x_space[i, 1]
raise ValueError(
f"Lower bound must be less than upper bound at index {i}: {lb} >= {ub}"
)
# bounds for the mixed continuous and integer space
if self._use_continuous and self._use_integer:
lower_x = self._x_space[:, 0]
upper_x = self._x_space[:, 1]
lower_z = np.min(self._z_space, axis=1)
upper_z = np.max(self._z_space, axis=1)
lower_g = np.concatenate([lower_x, lower_z])
upper_g = np.concatenate([upper_x, upper_z])
# bounds for the integer space
if not self._use_continuous and self._use_integer:
lower_g = np.min(self._z_space, axis=1)
upper_g = np.max(self._z_space, axis=1)
# bounds for the continuous space
if self._use_continuous and not self._use_integer:
lower_g = self._x_space[:, 0]
upper_g = self._x_space[:, 1]
if mean is None:
# Set initial mean to the center of the search space
self._mean = np.zeros(self._Nmi)
self._mean[(lower_g != -np.inf) & (upper_g != np.inf)] = (
lower_g[(lower_g != -np.inf) & (upper_g != np.inf)]
+ upper_g[(lower_g != -np.inf) & (upper_g != np.inf)]
) / 2
self._mean[(lower_g == -np.inf) & (upper_g != np.inf)] = (
upper_g[(lower_g == -np.inf) & (upper_g != np.inf)] - 1
)
self._mean[(lower_g != -np.inf) & (upper_g == np.inf)] = (
lower_g[(lower_g != -np.inf) & (upper_g == np.inf)] + 1
)
else:
if len(mean) != self._Nmi:
raise ValueError(
f"Invalid shape of mean: expected length {self._Nmi}, but got {len(mean)}."
)
self._mean = mean
assert np.all(np.abs(self._mean) < _MEAN_MAX), (
f"Abs of all elements of mean vector must be less than {_MEAN_MAX}."
)
if sigma is None:
self._sigma = 1.0
else:
if sigma <= 0:
raise ValueError("sigma must be non-zero positive value.")
self._sigma = sigma
if cov is None:
# Set initial standard deviation to
# width / 6 (continuous)
# width / 5 (integer)
width = np.minimum(self._mean - lower_g, upper_g - self._mean)
width /= np.where(np.arange(self._Nmi) < self._Nco, 6, 5)
self._C = np.diag(np.where(np.isfinite(width), width**2, 1.0))
else:
if cov.shape != (self._Nmi, self._Nmi):
raise ValueError(
f"Invalid shape of covariance matrix: expected "
f"({self._Nmi}, {self._Nmi}), but got {cov.shape}."
)
self._C = cov
self._D: Optional[np.ndarray] = None
self._B: Optional[np.ndarray] = None
# --- Other CMA-ES parameters ---
# learning rate for the mean
self._cm = 1.0
# learning rate for the cumulation for the step-size control
self._c_sigma = (self._mu_eff + 2) / (self._Nmi + self._mu_eff + 5)
self._d_sigma = (
1 + 2 * max(0, math.sqrt((self._mu_eff - 1) / (self._Nmi + 1)) - 1) + self._c_sigma
)
assert self._c_sigma < 1, "Invalid learning rate for cumulation for the step-size control."
# learning rate for cumulation for the rank-one update
self._cc = (4 + self._mu_eff / self._Nmi) / (self._Nmi + 4 + 2 * self._mu_eff / self._Nmi)
assert self._cc <= 1, "Invalid learning rate for cumulation for the rank-one update."
# E||N(0, I_Nmi)||
self._chi_n = math.sqrt(self._Nmi) * (
1.0 - (1.0 / (4.0 * self._Nmi)) + 1.0 / (21.0 * (self._Nmi**2))
)
# evolution paths
self._p_sigma = np.zeros(self._Nmi)
self._pc = np.zeros(self._Nmi)
# matrix for margin correction
self._A = np.full(self._Nmi, 1.0)
# minimum eigenvalue of covariance matrix
self._min_eigenvalue = 1e-30
# history of interquartile range of the unpenalized objective function values
self._iqhist_term = 20 + math.ceil(3 * self._Nmi / self._popsize)
self._iqhist_values: List[float] = []
# termination criteria based on CMA-ES
self._tolx = 1e-12 * self._sigma
self._tolxup = 1e4
self._tolfun = 1e-12
self._tolconditioncov = 1e14
self._funhist_term = 10 + math.ceil(30 * self._Nmi / self._popsize)
self._funhist_values = np.empty(self._funhist_term * 2)
def _init_categorical(
self,
c_space: Optional[Sequence[int]],
cat_param: Optional[np.ndarray],
) -> None:
assert c_space is not None, "c_space must not be None for categorical variables."
self._K = np.asarray(c_space, dtype=int)
if not np.all(self._K >= 2):
invalid = np.where(self._K < 2)[0][0]
raise ValueError(
f"All elements of c_space must be >= 2. "
f"Found {self._K[invalid]} at index {invalid}."
)
self._Kmax = np.max(self._K)
if cat_param is None:
self._q = np.zeros((self._Nca, self._Kmax))
for i in range(self._Nca):
self._q[i, : self._K[i]] = 1 / self._K[i]
else:
if cat_param.shape != (self._Nca, self._Kmax):
raise ValueError(
f"Invalid shape of categorical distribution parameter: "
f"expected ({self._Nca}, {self._Kmax}), got {cat_param.shape}."
)
for i in range(self._Nca):
if not np.all(cat_param[i, self._K[i] :] == 0):
raise ValueError(
f"Parameters in categorical distribution with fewer categories "
f"must be zero-padded at the end. "
f"Non-zero padding found at row {i}: {cat_param[i]}"
)
if not np.all((cat_param >= 0) & (cat_param <= 1)):
raise ValueError(
"All elements in categorical distribution parameter must be between 0 and 1."
)
if not np.allclose(np.sum(cat_param, axis=1), 1):
raise ValueError("Each row in categorical distribution parameter must sum to 1.")
self._q = cat_param
# margin value for categorical variables
self._qmin = (1 - 0.73 ** (1 / (self._Nin + self._Nca))) / (self._K - 1)
# --- ASNG parameters ---
# Adaptive Stochastic Natural Gradient method:
# https://proceedings.mlr.press/v97/akimoto19a.html
self._param_sum = np.sum(self._K - 1)
self._alpha_snr = 1.5
self._delta_init = 1.0
self._Delta = 1.0
self._Delta_max = np.inf
self._gamma = 0.0
self._s = np.zeros(self._param_sum)
self._delta = self._delta_init / self._Delta
self._eps = self._delta
@property
def n_continuous(self) -> int:
"""Number of continuous variables"""
return self._Nco
@property
def n_integer(self) -> int:
"""Number of integer variables"""
return self._Nin
@property
def n_categorical(self) -> int:
"""Number of categorical variables"""
return self._Nca
@property
def population_size(self) -> int:
"""A population size"""
return self._popsize
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when the distribution is updated."""
return self._g
def reseed_rng(self, seed: int) -> None:
"""Reseeds the internal random number generator."""
self._rng.seed(seed)
def _eigen_decomposition(self) -> Tuple[np.ndarray, np.ndarray]:
if self._B is not None and self._D is not None:
return self._B, self._D
self._C = (self._C + self._C.T) / 2
D2, B = np.linalg.eigh(self._C)
D = np.sqrt(np.where(D2 < 0, _EPS, D2))
self._C = np.dot(np.dot(B, np.diag(D**2)), B.T)
self._B, self._D = B, D
return B, D
def _sample_from_gaussian(self) -> np.ndarray:
B, D = self._eigen_decomposition()
xi = self._rng.randn(self._Nmi) # ~ N(0, I)
y = cast(np.ndarray, B.dot(np.diag(D))).dot(xi) # ~ N(0, C)
v = self._mean + self._sigma * self._A * y # ~ N(m, σ^2 A C A)
return v
def _sample_from_categorical(self) -> np.ndarray:
# Categorical variables are one-hot encoded.
# Variables with fewer categories are zero-padded at the end.
rand_q = self._rng.rand(self._Nca, 1)
cum_q = self._q.cumsum(axis=1)
c = (cum_q - self._q <= rand_q) & (rand_q < cum_q)
return c
def _repair_continuous_params(self, continuous_param: np.ndarray) -> np.ndarray:
if self._x_space is None:
return continuous_param
# clip with lower and upper bound.
param = np.where(
continuous_param < self._x_space[:, 0],
self._x_space[:, 0],
continuous_param,
)
param = np.where(param > self._x_space[:, 1], self._x_space[:, 1], param)
return param
def _discretization(self, v_discrete: np.ndarray) -> np.ndarray:
z_pos = np.array(
[np.searchsorted(self._z_lim[i], v_discrete[i]) for i in range(len(v_discrete))]
)
z = self._z_space[np.arange(len(self._z_space)), z_pos]
return z
def _calc_continuous_penalty(self, v_raw: np.ndarray, sorted_fvals: np.ndarray) -> np.ndarray:
# penalty values for box constraint handling:
# https://ieeexplore.ieee.org/document/4634579
iq_range = sorted_fvals[3 * self._popsize // 4] - sorted_fvals[self._popsize // 4]
# insert iq_range in history
if np.isfinite(iq_range) and iq_range > 0:
self._iqhist_values.insert(0, iq_range)
elif iq_range == np.inf and len(self._iqhist_values) > 1:
self._iqhist_values.insert(0, max(self._iqhist_values))
else:
pass # ignore 0 or nan values
if len(self._iqhist_values) > self._iqhist_term:
self._iqhist_values.pop()
bound_low = np.concatenate((self._x_space[:, 0], np.full(self._Nin, -np.inf)))
bound_up = np.concatenate((self._x_space[:, 1], np.full(self._Nin, np.inf)))
diag_CA = np.diag(self._C) * self._A
delta_fit = np.median(self._iqhist_values)
gamma = np.ones(self._Nmi) * 2 * delta_fit / (self._sigma**2 * np.sum(diag_CA))
gamma_inc_low = (self._mean < bound_low) * (
np.abs(self._mean - bound_low)
> 3 * self._sigma * np.sqrt(diag_CA) * max(1, np.sqrt(self._Nmi) / self._mu_eff)
)
gamma_inc_up = (bound_up < self._mean) * (
np.abs(bound_up - self._mean)
> 3 * self._sigma * np.sqrt(diag_CA) * max(1, np.sqrt(self._Nmi) / self._mu_eff)
)
gamma_inc = np.logical_or(gamma_inc_low, gamma_inc_up)
gamma[gamma_inc] *= 1.1 ** (max(1, self._mu_eff / (10 * self._Nmi)))
xis = np.exp(0.9 * (np.log(diag_CA) - np.sum(np.log(diag_CA)) / self._Nmi))
v_feas = np.where(
v_raw < bound_low, bound_low, np.where(v_raw > bound_up, bound_up, v_raw)
)
penalties = np.sum(gamma * ((v_feas - v_raw) ** 2) / xis, axis=1)
return penalties
def _integer_centering(self, v_raw: np.ndarray) -> np.ndarray:
# integer centering and
# calculation of whether a successful integer mutation occurred
v_old = np.copy(v_raw)
int_m = self._discretization(self._mean[self._discrete_idx])
mpos = np.zeros(self._Nin)
mneg = np.zeros(self._Nin)
self._int_succ = np.zeros(self._Nin, dtype=bool)
for i in range(self._mu):
vin_i = v_raw[i, self._discrete_idx]
int_vin_i = self._discretization(vin_i)
mutated = int_vin_i != int_m
self._int_succ = np.logical_or(self._int_succ, mutated)
mpos += (~mutated) * ((int_vin_i - vin_i) > 0) * (int_vin_i - vin_i)
mneg += (~mutated) * ((int_vin_i - vin_i) < 0) * (int_vin_i - vin_i)
v_raw[i, self._discrete_idx[mutated]] = int_vin_i[mutated]
bias = np.sum((v_raw - v_old)[: self._mu, self._discrete_idx], axis=0)
alphas = np.zeros(self._Nin)
for moves in [mpos, mneg]:
idx = bias * moves < 0
alphas[idx] = np.minimum(1, -bias[idx] / moves[idx])
for i in range(self._mu):
int_voldin_i = self._discretization(v_old[i, self._discrete_idx])
int_vin_i = self._discretization(v_raw[i, self._discrete_idx])
Delta = int_voldin_i - v_old[i, self._discrete_idx]
non_mutated = int_vin_i == int_m
bias_Delta_cond = bias * Delta < 0
indic = np.logical_and(bias_Delta_cond, non_mutated)
v_raw[i, self._discrete_idx] += indic * alphas * Delta
return v_raw
def _update_gaussian(self, sv: np.ndarray) -> None:
x_k = (sv - self._mean) / self._A + self._mean # ~ N(m, σ^2 C)
y_k = (x_k - self._mean) / self._sigma # ~ N(0, C)
B, D = self._eigen_decomposition()
# Selection and recombination
y_w = np.sum(y_k[: self._mu].T * self._weights[: self._mu], axis=1)
self._mean += self._cm * self._sigma * y_w
# Step-size control
C_2 = cast(
np.ndarray, cast(np.ndarray, B.dot(np.diag(1 / D))).dot(B.T)
) # C^(-1/2) = B D^(-1) B^T
self._p_sigma = (1 - self._c_sigma) * self._p_sigma + math.sqrt(
self._c_sigma * (2 - self._c_sigma) * self._mu_eff
) * C_2.dot(y_w)
norm_p_sigma = np.linalg.norm(self._p_sigma)
self._sigma *= np.exp((self._c_sigma / self._d_sigma) * (norm_p_sigma / self._chi_n - 1))
self._sigma = min(self._sigma, _SIGMA_MAX)
# Covariance matrix adaption
h_sigma_cond_left = norm_p_sigma / math.sqrt(
1 - (1 - self._c_sigma) ** (2 * (self._g + 1))
)
h_sigma_cond_right = (1.4 + 2 / (self._Nmi + 1)) * self._chi_n
h_sigma = 1.0 if h_sigma_cond_left < h_sigma_cond_right else 0.0 # (p.28)
self._pc = (1 - self._cc) * self._pc + h_sigma * math.sqrt(
self._cc * (2 - self._cc) * self._mu_eff
) * y_w
w_io = self._weights * np.where(
self._weights >= 0,
1,
self._Nmi / (np.linalg.norm(C_2.dot(y_k.T), axis=0) ** 2 + _EPS),
)
delta_h_sigma = (1 - h_sigma) * self._cc * (2 - self._cc)
assert delta_h_sigma <= 1
rank_one = np.outer(self._pc, self._pc)
rank_mu = np.sum(np.array([w * np.outer(y, y) for w, y in zip(w_io, y_k)]), axis=0)
self._C = (
(1 + self._c1 * delta_h_sigma - self._c1 - self._cmu * np.sum(self._weights)) * self._C
+ self._c1 * rank_one
+ self._cmu * rank_mu
)
# post-processing to prevent the minimum eigenvalue from becoming too small
self._B, self._D = None, None
B_updated, D_updated = self._eigen_decomposition()
sigma_min = np.sqrt(self._min_eigenvalue / np.min(D_updated))
self._sigma = max(self._sigma, sigma_min)
def _margin_correction(self) -> None:
updated_m_integer = self._mean[self._discrete_idx]
# nearest discretization thresholds
m_pos = np.array(
[
np.searchsorted(self._z_lim[i], updated_m_integer[i])
for i in range(len(updated_m_integer))
]
)
z_lim_low_index = np.clip(m_pos - 1, 0, self._z_lim.shape[1] - 1)
z_lim_up_index = np.clip(m_pos, 0, self._z_lim.shape[1] - 1)
m_z_lim_low = self._z_lim[np.arange(len(self._z_lim)), z_lim_low_index]
m_z_lim_up = self._z_lim[np.arange(len(self._z_lim)), z_lim_up_index]
# low_cdf := Pr(X <= m_z_lim_low)
# up_cdf := Pr(m_z_lim_up < X)
z_scale = (
self._sigma
* self._A[self._discrete_idx]
* np.sqrt(np.diag(self._C)[self._discrete_idx])
)
low_cdf = norm_cdf(m_z_lim_low, loc=updated_m_integer, scale=z_scale)
up_cdf = 1.0 - norm_cdf(m_z_lim_up, loc=updated_m_integer, scale=z_scale)
mid_cdf = 1.0 - (low_cdf + up_cdf)
# edge case
edge_mask = np.maximum(low_cdf, up_cdf) > 0.5
# otherwise
side_mask = np.maximum(low_cdf, up_cdf) <= 0.5
# indices of successful integer mutations
suc_idx = np.where(self._int_succ)
nsuc_idx = np.where(~self._int_succ)
if np.any(edge_mask):
# modify sign
modify_sign = np.sign(self._mean[self._discrete_idx] - m_z_lim_up)
# clip mutation rates
p_mut = np.minimum(low_cdf, up_cdf)
p_mut = np.maximum(p_mut, self._alpha)
p_mut[nsuc_idx] = np.minimum(p_mut[nsuc_idx], self._pmut[nsuc_idx])
indices_to_update = self._discrete_idx[edge_mask]
# avoid numerical errors
p_mut = np.clip(p_mut, _EPS, 0.5 - _EPS)
# modify A
m_int = self._discretization(updated_m_integer)
A_lower = np.abs(m_int - m_z_lim_up) / (
self._sigma
* np.sqrt(
chi2_ppf(q=1.0 - 2.0 * self._alpha) * np.diag(self._C)[self._discrete_idx]
)
)
self._A[indices_to_update] = np.maximum(self._A[indices_to_update], A_lower[edge_mask])
# distance from m_z_lim_up
dist = (
self._sigma
* self._A[self._discrete_idx]
* np.sqrt(chi2_ppf(q=1.0 - 2.0 * p_mut) * np.diag(self._C)[self._discrete_idx])
)
# modify mean vector
self._mean[self._discrete_idx] = self._mean[self._discrete_idx] + edge_mask * (
m_z_lim_up + modify_sign * dist - self._mean[self._discrete_idx]
)
# save mutation rates for the next generation
self._pmut[edge_mask] = p_mut[edge_mask]
if np.any(side_mask):
low_cdf = np.maximum(low_cdf, self._alpha / 2)
up_cdf = np.maximum(up_cdf, self._alpha / 2)
mid_cdf[nsuc_idx] = np.maximum(mid_cdf[nsuc_idx], 1 - self._pmut[nsuc_idx])
Delta_cdf = 1 - low_cdf - up_cdf - mid_cdf
Delta_cdf[suc_idx] /= (
low_cdf[suc_idx] + up_cdf[suc_idx] + mid_cdf[suc_idx] - 3 * self._alpha / 2
)
Delta_cdf[nsuc_idx] /= (
low_cdf[nsuc_idx]
+ up_cdf[nsuc_idx]
+ mid_cdf[nsuc_idx]
- self._alpha
- (1 - self._pmut[nsuc_idx])
)
low_cdf += Delta_cdf * (low_cdf - self._alpha / 2)
up_cdf += Delta_cdf * (up_cdf - self._alpha / 2)
# avoid numerical errors
low_cdf = np.clip(low_cdf, _EPS, 0.5 - _EPS)
up_cdf = np.clip(up_cdf, _EPS, 0.5 - _EPS)
# modify mean vector and A (with sigma and C fixed)
chi_low_sq = np.sqrt(chi2_ppf(q=1.0 - 2 * low_cdf))
chi_up_sq = np.sqrt(chi2_ppf(q=1.0 - 2 * up_cdf))
C_diag_sq = np.sqrt(np.diag(self._C))[self._discrete_idx]
self._A[self._discrete_idx] = self._A[self._discrete_idx] + side_mask * (
(m_z_lim_up - m_z_lim_low) / ((chi_low_sq + chi_up_sq) * self._sigma * C_diag_sq)
- self._A[self._discrete_idx]
)
self._mean[self._discrete_idx] = self._mean[self._discrete_idx] + side_mask * (
(m_z_lim_low * chi_up_sq + m_z_lim_up * chi_low_sq) / (chi_low_sq + chi_up_sq)
- self._mean[self._discrete_idx]
)
# save mutation rates for the next generation
self._pmut[side_mask] = low_cdf[side_mask] + up_cdf[side_mask]
def _update_categorical(self, sc: np.ndarray) -> None:
# natural gradient
ngrad = (
self._weights[: self._mu, np.newaxis, np.newaxis] * (sc[: self._mu, :, :] - self._q)
).sum(axis=0)
# approximation of the square root of the fisher information matrix:
# Appendix B in https://proceedings.mlr.press/v97/akimoto19a.html
sl = []
for i, K in enumerate(self._K):
q_i = self._q[i, : K - 1]
q_i_K = self._q[i, K - 1]
s_i = 1.0 / np.sqrt(q_i) * ngrad[i, : K - 1]
s_i += np.sqrt(q_i) * ngrad[i, : K - 1].sum() / (q_i_K + np.sqrt(q_i_K))
sl += list(s_i)
ngrad_sqF = np.array(sl)
pnorm = np.sqrt(np.dot(ngrad_sqF, ngrad_sqF))
self._eps = self._delta / (pnorm + _EPS)
self._q += self._eps * ngrad
# update of ASNG
self._delta = self._delta_init / self._Delta
beta = self._delta / (self._param_sum**0.5)
self._s = (1 - beta) * self._s + np.sqrt(beta * (2 - beta)) * ngrad_sqF / pnorm
self._gamma = (1 - beta) ** 2 * self._gamma + beta * (2 - beta)
self._Delta *= np.exp(beta * (self._gamma - np.dot(self._s, self._s) / self._alpha_snr))
self._Delta = min(self._Delta, self._Delta_max)
# margin correction for categorical distribution
for i in range(self._Nca):
Ki = self._K[i]
self._q[i, :Ki] = np.maximum(self._q[i, :Ki], self._qmin[i])
q_sum = self._q[i, :Ki].sum()
tmp = q_sum - self._qmin[i] * Ki
self._q[i, :Ki] -= (q_sum - 1) * (self._q[i, :Ki] - self._qmin[i]) / tmp
self._q[i, :Ki] /= self._q[i, :Ki].sum()
def ask(self) -> CatCMAwM.Solution:
"""Sample a solution from the current search distribution.
Returns:
Solution: A sampled Solution object containing continuous (x),
integer (z), and/or categorical (c) variables.
"""
x = None
z = None
c = None
v_raw = None
if self._use_gaussian:
v_raw = self._sample_from_gaussian()
if self._use_continuous:
x_raw = v_raw[self._continuous_idx]
x = self._repair_continuous_params(x_raw)
if self._use_integer:
z = self._discretization(v_raw[self._discrete_idx])
if self._use_categorical:
c = self._sample_from_categorical()
return CatCMAwM.Solution(x, z, c, v_raw)
def tell(self, solutions: List[Tuple[CatCMAwM.Solution, float]]) -> None:
"""Tell evaluation values"""
if len(solutions) != self._popsize:
raise ValueError(
f"Must tell population_size-length solutions: "
f"expected {self._popsize}, but got {len(solutions)}."
)
solutions.sort(key=lambda s: s[1])
fvals = np.stack([sol[1] for sol in solutions])
# calculate penalty values for infeasible continuous solutions
penalties = np.zeros(self._popsize)
if self._use_continuous:
v_raw = np.stack([cast(np.ndarray, sol[0]._v_raw) for sol in solutions])
penalties = self._calc_continuous_penalty(v_raw, fvals)
for i in range(self._popsize):
solutions[i] = (solutions[i][0], solutions[i][1] + penalties[i])
solutions.sort(key=lambda s: s[1])
sv = None
sc = None
if self._use_gaussian:
sv = np.stack([cast(np.ndarray, sol[0]._v_raw) for sol in solutions])
assert np.all(np.abs(sv) < _MEAN_MAX), (
f"Abs of all param values must be less than {_MEAN_MAX} to avoid overflow errors."
)
if self._use_categorical:
sc = np.stack([cast(np.ndarray, sol[0].c) for sol in solutions])
self._g += 1
# Stores 'best' and 'worst' values of the
# last 'self._funhist_term' generations.
if self._use_gaussian:
funhist_idx = 2 * (self.generation % self._funhist_term)
self._funhist_values[funhist_idx] = fvals[0]
self._funhist_values[funhist_idx + 1] = fvals[-1]
# integer centering
if self._use_integer:
assert sv is not None, "sv (sample from gaussian) must not be None."
sv = self._integer_centering(sv)
# --- update distribution parameters ---
if self._use_gaussian:
assert sv is not None, "sv (sample from gaussian) must not be None."
self._update_gaussian(sv)
if self._use_integer:
self._margin_correction()
if self._use_categorical:
assert sc is not None, "sc (sample from categorical) must not be None."
self._update_categorical(sc)
def should_stop(self) -> bool:
"""Termination conditions specifically tailored for mixed-variable
cases are not yet implemented. Currently, only standard CMA-ES conditions for
Gaussian distributions are used."""
if not self._use_gaussian:
warnings.warn("Termination conditions are only applicable for Gaussian distribution.")
return False
B, D = self._eigen_decomposition()
dC = np.diag(self._C)
# Stop if the range of function values of the recent generation is below tolfun.
if (
self.generation > self._funhist_term
and np.max(self._funhist_values) - np.min(self._funhist_values) < self._tolfun
):
return True
# Stop if the std of the normal distribution is smaller than tolx
# in all coordinates and pc is smaller than tolx in all components.
if np.all(self._sigma * dC < self._tolx) and np.all(self._sigma * self._pc < self._tolx):
return True
# Stop if detecting divergent behavior.
if self._sigma * np.max(D) > self._tolxup:
return True
# No effect coordinates: stop if adding 0.2-standard deviations
# in any single coordinate does not change m.
if np.any(self._mean == self._mean + (0.2 * self._sigma * np.sqrt(dC))):
return True
# No effect axis: stop if adding 0.1-standard deviation vector in
# any principal axis direction of C does not change m. "pycma" check
# axis one by one at each generation.
i = self.generation % self._Nmi
if np.all(self._mean == self._mean + (0.1 * self._sigma * D[i] * B[:, i])):
return True
# Stop if the condition number of the covariance matrix exceeds 1e14.
condition_cov = np.max(D) / np.min(D)
if condition_cov > self._tolconditioncov:
return True
return False
cmaes-0.13.1/cmaes/_cma.py000066400000000000000000000446221524175644700152540ustar00rootroot00000000000000from __future__ import annotations
import math
import numpy as np
from typing import Any
from typing import cast
from typing import Optional
_EPS = 1e-8
_MEAN_MAX = 1e32
_SIGMA_MAX = 1e32
class CMA:
"""CMA-ES stochastic optimizer class with ask-and-tell interface.
Example:
.. code::
import numpy as np
from cmaes import CMA
def quadratic(x1, x2):
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
optimizer = CMA(mean=np.zeros(2), sigma=1.3)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x = optimizer.ask()
value = quadratic(x[0], x[1])
solutions.append((x, value))
print(f"#{generation} {value} (x1={x[0]}, x2 = {x[1]})")
# Tell evaluation values.
optimizer.tell(solutions)
Args:
mean:
Initial mean vector of multi-variate gaussian distributions.
sigma:
Initial standard deviation of covariance matrix.
bounds:
Lower and upper domain boundaries for each parameter (optional).
n_max_resampling:
A maximum number of resampling parameters (default: 100).
If all sampled parameters are infeasible, the last sampled one
will be clipped with lower and upper bounds.
seed:
A seed number (optional).
population_size:
A population size (optional).
cov:
A covariance matrix (optional).
lr_adapt:
Flag for learning rate adaptation (optional; default=False)
"""
def __init__(
self,
mean: np.ndarray,
sigma: float,
bounds: Optional[np.ndarray] = None,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
cov: Optional[np.ndarray] = None,
lr_adapt: bool = False,
):
assert sigma > 0, "sigma must be non-zero positive value"
assert np.all(np.abs(mean) < _MEAN_MAX), (
f"Abs of all elements of mean vector must be less than {_MEAN_MAX}"
)
n_dim = len(mean)
assert n_dim > 0, "The dimension of mean must be positive"
if population_size is None:
population_size = 4 + math.floor(3 * math.log(n_dim)) # (eq. 48)
assert population_size > 0, "popsize must be non-zero positive value."
mu = population_size // 2
# (eq.49)
weights_prime = np.array(
[math.log((population_size + 1) / 2) - math.log(i + 1) for i in range(population_size)]
)
mu_eff = (np.sum(weights_prime[:mu]) ** 2) / np.sum(weights_prime[:mu] ** 2)
mu_eff_minus = (np.sum(weights_prime[mu:]) ** 2) / np.sum(weights_prime[mu:] ** 2)
# learning rate for the rank-one update
alpha_cov = 2
c1 = alpha_cov / ((n_dim + 1.3) ** 2 + mu_eff)
# learning rate for the rank-μ update
cmu = min(
1 - c1 - 1e-8, # 1e-8 is for large popsize.
alpha_cov * (mu_eff - 2 + 1 / mu_eff) / ((n_dim + 2) ** 2 + alpha_cov * mu_eff / 2),
)
assert c1 <= 1 - cmu, "invalid learning rate for the rank-one update"
assert cmu <= 1 - c1, "invalid learning rate for the rank-μ update"
min_alpha = min(
1 + c1 / cmu, # eq.50
1 + (2 * mu_eff_minus) / (mu_eff + 2), # eq.51
(1 - c1 - cmu) / (n_dim * cmu), # eq.52
)
# (eq.53)
positive_sum = np.sum(weights_prime[weights_prime > 0])
negative_sum = np.sum(np.abs(weights_prime[weights_prime < 0]))
weights = np.where(
weights_prime >= 0,
1 / positive_sum * weights_prime,
min_alpha / negative_sum * weights_prime,
)
cm = 1 # (eq. 54)
# learning rate for the cumulation for the step-size control (eq.55)
c_sigma = (mu_eff + 2) / (n_dim + mu_eff + 5)
d_sigma = 1 + 2 * max(0, math.sqrt((mu_eff - 1) / (n_dim + 1)) - 1) + c_sigma
assert c_sigma < 1, "invalid learning rate for cumulation for the step-size control"
# learning rate for cumulation for the rank-one update (eq.56)
cc = (4 + mu_eff / n_dim) / (n_dim + 4 + 2 * mu_eff / n_dim)
assert cc <= 1, "invalid learning rate for cumulation for the rank-one update"
self._n_dim = n_dim
self._popsize = population_size
self._mu = mu
self._mu_eff = mu_eff
self._cc = cc
self._c1 = c1
self._cmu = cmu
self._c_sigma = c_sigma
self._d_sigma = d_sigma
self._cm = cm
# E||N(0, I)|| (p.28)
self._chi_n = math.sqrt(self._n_dim) * (
1.0 - (1.0 / (4.0 * self._n_dim)) + 1.0 / (21.0 * (self._n_dim**2))
)
self._weights = weights
# evolution path
self._p_sigma = np.zeros(n_dim)
self._pc = np.zeros(n_dim)
self._mean = mean.copy()
if cov is None:
self._C = np.eye(n_dim)
else:
assert cov.shape == (n_dim, n_dim), "Invalid shape of covariance matrix"
self._C = cov
self._sigma = sigma
self._D: Optional[np.ndarray] = None
self._B: Optional[np.ndarray] = None
# bounds contains low and high of each parameter.
assert bounds is None or _is_valid_bounds(bounds, mean), "invalid bounds"
self._bounds = bounds
self._n_max_resampling = n_max_resampling
self._g = 0
self._rng = np.random.RandomState(seed)
# for learning rate adaptation
self._lr_adapt = lr_adapt
self._alpha = 1.4
self._beta_mean = 0.1
self._beta_Sigma = 0.03
self._gamma = 0.1
self._Emean = np.zeros([self._n_dim, 1])
self._ESigma = np.zeros([self._n_dim * self._n_dim, 1])
self._Vmean = 0.0
self._VSigma = 0.0
self._eta_mean = 1.0
self._eta_Sigma = 1.0
# Termination criteria
self._tolx = 1e-12 * sigma
self._tolxup = 1e4
self._tolfun = 1e-12
self._tolconditioncov = 1e14
self._funhist_term = 10 + math.ceil(30 * n_dim / population_size)
self._funhist_values = np.empty(self._funhist_term * 2)
def __getstate__(self) -> dict[str, Any]:
attrs = {}
for name in self.__dict__:
# Remove _rng in pickle serialized object.
if name == "_rng":
continue
if name == "_C":
sym1d = _compress_symmetric(self._C)
attrs["_c_1d"] = sym1d
continue
attrs[name] = getattr(self, name)
return attrs
def __setstate__(self, state: dict[str, Any]) -> None:
state["_C"] = _decompress_symmetric(state["_c_1d"])
del state["_c_1d"]
self.__dict__.update(state)
# Set _rng for unpickled object.
setattr(self, "_rng", np.random.RandomState())
@property
def dim(self) -> int:
"""A number of dimensions"""
return self._n_dim
@property
def population_size(self) -> int:
"""A population size"""
return self._popsize
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when multi-variate gaussian distribution is updated."""
return self._g
@property
def mean(self) -> np.ndarray:
"""Mean Vector"""
return self._mean
def reseed_rng(self, seed: int) -> None:
self._rng.seed(seed)
def set_bounds(self, bounds: Optional[np.ndarray]) -> None:
"""Update boundary constraints"""
assert bounds is None or _is_valid_bounds(bounds, self._mean), "invalid bounds"
self._bounds = bounds
def ask(self) -> np.ndarray:
"""Sample a parameter"""
for i in range(self._n_max_resampling):
x = self._sample_solution()
if self._is_feasible(x):
return x
x = self._sample_solution()
x = self._repair_infeasible_params(x)
return x
def _eigen_decomposition(self) -> tuple[np.ndarray, np.ndarray]:
if self._B is not None and self._D is not None:
return self._B, self._D
self._C = (self._C + self._C.T) / 2
D2, B = np.linalg.eigh(self._C)
D = np.sqrt(np.where(D2 < 0, _EPS, D2))
self._C = np.dot(np.dot(B, np.diag(D**2)), B.T)
self._B, self._D = B, D
return B, D
def _sample_solution(self) -> np.ndarray:
B, D = self._eigen_decomposition()
z = self._rng.randn(self._n_dim) # ~ N(0, I)
y = cast(np.ndarray, B.dot(np.diag(D))).dot(z) # ~ N(0, C)
x = self._mean + self._sigma * y # ~ N(m, σ^2 C)
return x
def _is_feasible(self, param: np.ndarray) -> bool:
if self._bounds is None:
return True
return cast(
bool,
np.all(param >= self._bounds[:, 0]) and np.all(param <= self._bounds[:, 1]),
) # Cast bool_ to bool.
def _repair_infeasible_params(self, param: np.ndarray) -> np.ndarray:
if self._bounds is None:
return param
# clip with lower and upper bound.
param = np.where(param < self._bounds[:, 0], self._bounds[:, 0], param)
param = np.where(param > self._bounds[:, 1], self._bounds[:, 1], param)
return param
def tell(self, solutions: list[tuple[np.ndarray, float]]) -> None:
"""Tell evaluation values"""
assert len(solutions) == self._popsize, "Must tell popsize-length solutions."
for s in solutions:
assert np.all(np.abs(s[0]) < _MEAN_MAX), (
f"Abs of all param values must be less than {_MEAN_MAX} to avoid overflow errors"
)
self._g += 1
solutions.sort(key=lambda s: s[1])
# Stores 'best' and 'worst' values of the
# last 'self._funhist_term' generations.
funhist_idx = 2 * (self.generation % self._funhist_term)
self._funhist_values[funhist_idx] = solutions[0][1]
self._funhist_values[funhist_idx + 1] = solutions[-1][1]
# Sample new population of search_points, for k=1, ..., popsize
B, D = self._eigen_decomposition()
self._B, self._D = None, None
# keep old values for learning rate adaptation
if self._lr_adapt:
old_mean = np.copy(self._mean)
old_sigma = self._sigma
old_Sigma = self._sigma**2 * self._C
old_invsqrtC = B @ np.diag(1 / D) @ B.T
else:
old_mean, old_sigma, old_Sigma, old_invsqrtC = None, None, None, None
x_k = np.array([s[0] for s in solutions]) # ~ N(m, σ^2 C)
y_k = (x_k - self._mean) / self._sigma # ~ N(0, C)
# Selection and recombination
y_w = np.sum(y_k[: self._mu].T * self._weights[: self._mu], axis=1) # eq.41
self._mean += self._cm * self._sigma * y_w
# Step-size control
C_2 = cast(
np.ndarray, cast(np.ndarray, B.dot(np.diag(1 / D))).dot(B.T)
) # C^(-1/2) = B D^(-1) B^T
self._p_sigma = (1 - self._c_sigma) * self._p_sigma + math.sqrt(
self._c_sigma * (2 - self._c_sigma) * self._mu_eff
) * C_2.dot(y_w)
norm_p_sigma = np.linalg.norm(self._p_sigma)
self._sigma *= np.exp((self._c_sigma / self._d_sigma) * (norm_p_sigma / self._chi_n - 1))
self._sigma = min(self._sigma, _SIGMA_MAX)
# Covariance matrix adaption
h_sigma_cond_left = norm_p_sigma / math.sqrt(
1 - (1 - self._c_sigma) ** (2 * (self._g + 1))
)
h_sigma_cond_right = (1.4 + 2 / (self._n_dim + 1)) * self._chi_n
h_sigma = 1.0 if h_sigma_cond_left < h_sigma_cond_right else 0.0 # (p.28)
# (eq.45)
self._pc = (1 - self._cc) * self._pc + h_sigma * math.sqrt(
self._cc * (2 - self._cc) * self._mu_eff
) * y_w
# (eq.46)
w_io = self._weights * np.where(
self._weights >= 0,
1,
self._n_dim / (np.linalg.norm(C_2.dot(y_k.T), axis=0) ** 2 + _EPS),
)
delta_h_sigma = (1 - h_sigma) * self._cc * (2 - self._cc) # (p.28)
assert delta_h_sigma <= 1
# (eq.47)
rank_one = np.outer(self._pc, self._pc)
rank_mu = np.sum(w_io.reshape(-1, 1, 1) * np.einsum("...i,...j->...ij", y_k, y_k), axis=0)
# The above line is equivalent to:
# rank_mu = np.sum(np.array([w * np.outer(y, y) for w, y in zip(w_io, y_k)]), axis=0)
self._C = (
(1 + self._c1 * delta_h_sigma - self._c1 - self._cmu * np.sum(self._weights)) * self._C
+ self._c1 * rank_one
+ self._cmu * rank_mu
)
# Learning rate adaptation: https://arxiv.org/abs/2304.03473
if self._lr_adapt:
assert isinstance(old_mean, np.ndarray)
assert isinstance(old_sigma, (int, float))
assert isinstance(old_Sigma, np.ndarray)
assert isinstance(old_invsqrtC, np.ndarray)
self._lr_adaptation(old_mean, old_sigma, old_Sigma, old_invsqrtC)
def _lr_adaptation(
self,
old_mean: np.ndarray,
old_sigma: float,
old_Sigma: np.ndarray,
old_invsqrtC: np.ndarray,
) -> None:
# calculate one-step difference of the parameters
Deltamean = (self._mean - old_mean).reshape([self._n_dim, 1])
Sigma = (self._sigma**2) * self._C
# note that we use here matrix representation instead of vec one
DeltaSigma = Sigma - old_Sigma
# local coordinate
old_inv_sqrtSigma = old_invsqrtC / old_sigma
locDeltamean = old_inv_sqrtSigma.dot(Deltamean)
locDeltaSigma = (old_inv_sqrtSigma.dot(DeltaSigma.dot(old_inv_sqrtSigma))).reshape(
self.dim * self.dim, 1
) / np.sqrt(2)
# moving average E and V
self._Emean = (1 - self._beta_mean) * self._Emean + self._beta_mean * locDeltamean
self._ESigma = (1 - self._beta_Sigma) * self._ESigma + self._beta_Sigma * locDeltaSigma
self._Vmean = (1 - self._beta_mean) * self._Vmean + self._beta_mean * (
float(np.linalg.norm(locDeltamean)) ** 2
)
self._VSigma = (1 - self._beta_Sigma) * self._VSigma + self._beta_Sigma * (
float(np.linalg.norm(locDeltaSigma)) ** 2
)
# estimate SNR
sqnormEmean = np.linalg.norm(self._Emean) ** 2
hatSNRmean = (sqnormEmean - (self._beta_mean / (2 - self._beta_mean)) * self._Vmean) / (
self._Vmean - sqnormEmean
)
sqnormESigma = np.linalg.norm(self._ESigma) ** 2
hatSNRSigma = (
sqnormESigma - (self._beta_Sigma / (2 - self._beta_Sigma)) * self._VSigma
) / (self._VSigma - sqnormESigma)
# update learning rate
before_eta_mean = self._eta_mean
relativeSNRmean = np.clip((hatSNRmean / self._alpha / self._eta_mean) - 1, -1, 1)
self._eta_mean = self._eta_mean * np.exp(
min(self._gamma * self._eta_mean, self._beta_mean) * relativeSNRmean
)
relativeSNRSigma = np.clip((hatSNRSigma / self._alpha / self._eta_Sigma) - 1, -1, 1)
self._eta_Sigma = self._eta_Sigma * np.exp(
min(self._gamma * self._eta_Sigma, self._beta_Sigma) * relativeSNRSigma
)
# cap
self._eta_mean = min(self._eta_mean, 1.0)
self._eta_Sigma = min(self._eta_Sigma, 1.0)
# update parameters
self._mean = old_mean + self._eta_mean * Deltamean.reshape(self._n_dim)
Sigma = old_Sigma + self._eta_Sigma * DeltaSigma
# decompose Sigma to sigma and C
eigs, _ = np.linalg.eigh(Sigma)
logeigsum = sum([np.log(e) for e in eigs])
self._sigma = np.exp(logeigsum / 2.0 / self._n_dim)
self._sigma = min(self._sigma, _SIGMA_MAX)
self._C = (Sigma / (self._sigma**2)).astype(np.float64)
# step-size correction
self._sigma *= before_eta_mean / self._eta_mean
def should_stop(self) -> bool:
B, D = self._eigen_decomposition()
dC = np.diag(self._C)
# Stop if the range of function values of the recent generation is below tolfun.
if (
self.generation > self._funhist_term
and np.max(self._funhist_values) - np.min(self._funhist_values) < self._tolfun
):
return True
# Stop if the std of the normal distribution is smaller than tolx
# in all coordinates and pc is smaller than tolx in all components.
if np.all(self._sigma * dC < self._tolx) and np.all(self._sigma * self._pc < self._tolx):
return True
# Stop if detecting divergent behavior.
if self._sigma * np.max(D) > self._tolxup:
return True
# No effect coordinates: stop if adding 0.2-standard deviations
# in any single coordinate does not change m.
if np.any(self._mean == self._mean + (0.2 * self._sigma * np.sqrt(dC))):
return True
# No effect axis: stop if adding 0.1-standard deviation vector in
# any principal axis direction of C does not change m. "pycma" check
# axis one by one at each generation.
i = self.generation % self.dim
if np.all(self._mean == self._mean + (0.1 * self._sigma * D[i] * B[:, i])):
return True
# Stop if the condition number of the covariance matrix exceeds 1e14.
condition_cov = np.max(D) / np.min(D)
if condition_cov > self._tolconditioncov:
return True
return False
def _is_valid_bounds(bounds: Optional[np.ndarray], mean: np.ndarray) -> bool:
if bounds is None:
return True
if (mean.size, 2) != bounds.shape:
return False
if not np.all(bounds[:, 0] <= mean):
return False
if not np.all(mean <= bounds[:, 1]):
return False
return True
def _compress_symmetric(sym2d: np.ndarray) -> np.ndarray:
assert len(sym2d.shape) == 2 and sym2d.shape[0] == sym2d.shape[1]
n = sym2d.shape[0]
dim = (n * (n + 1)) // 2
sym1d = np.zeros(dim)
start = 0
for i in range(n):
sym1d[start : start + n - i] = sym2d[i][i:] # noqa: E203
start += n - i
return sym1d
def _decompress_symmetric(sym1d: np.ndarray) -> np.ndarray:
n = int(np.sqrt(sym1d.size * 2))
assert (n * (n + 1)) // 2 == sym1d.size
R, C = np.triu_indices(n)
out = np.zeros((n, n), dtype=sym1d.dtype)
out[R, C] = sym1d
out[C, R] = sym1d
return out
cmaes-0.13.1/cmaes/_cmawm.py000066400000000000000000000323441524175644700156160ustar00rootroot00000000000000from __future__ import annotations
import functools
import numpy as np
from typing import cast
from typing import Optional
from cmaes import CMA
from cmaes._cma import _is_valid_bounds
try:
from scipy import stats
chi2_ppf = functools.partial(stats.chi2.ppf, df=1)
norm_cdf = stats.norm.cdf
except ImportError:
from cmaes._stats import chi2_ppf # type: ignore
from cmaes._stats import norm_cdf
class CMAwM:
"""CMA-ES with Margin class with ask-and-tell interface.
The code is adapted from https://github.com/EvoConJP/CMA-ES_with_Margin.
Example:
.. code::
import numpy as np
from cmaes import CMAwM
def ellipsoid_onemax(x, n_zdim):
n = len(x)
n_rdim = n - n_zdim
ellipsoid = sum([(1000 ** (i / (n_rdim - 1)) * x[i]) ** 2 for i in range(n_rdim)])
onemax = n_zdim - (0. < x[(n - n_zdim):]).sum()
return ellipsoid + 10 * onemax
binary_dim, continuous_dim = 10, 10
dim = binary_dim + continuous_dim
bounds = np.concatenate(
[
np.tile([0, 1], (binary_dim, 1)),
np.tile([-np.inf, np.inf], (continuous_dim, 1)),
]
)
steps = np.concatenate([np.ones(binary_dim), np.zeros(continuous_dim)])
optimizer = CMAwM(mean=np.zeros(dim), sigma=2.0, bounds=bounds, steps=steps)
evals = 0
while True:
solutions = []
for _ in range(optimizer.population_size):
x_for_eval, x_for_tell = optimizer.ask()
value = ellipsoid_onemax(x_for_eval, binary_dim)
evals += 1
solutions.append((x_for_tell, value))
optimizer.tell(solutions)
if optimizer.should_stop():
break
Args:
mean:
Initial mean vector of multi-variate gaussian distributions.
sigma:
Initial standard deviation of covariance matrix.
bounds:
Lower and upper domain boundaries for each parameter.
steps:
Each value represents a step of discretization for each dimension.
Zero (or negative value) means a continuous space.
n_max_resampling:
A maximum number of resampling parameters (default: 100).
If all sampled parameters are infeasible, the last sampled one
will be clipped with lower and upper bounds.
seed:
A seed number (optional).
population_size:
A population size (optional).
cov:
A covariance matrix (optional).
margin:
A margin parameter (optional).
"""
# Paper: https://arxiv.org/abs/2205.13482
def __init__(
self,
mean: np.ndarray,
sigma: float,
bounds: np.ndarray,
steps: np.ndarray,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
cov: Optional[np.ndarray] = None,
margin: Optional[float] = None,
):
# initialize `CMA`
self._cma = CMA(mean, sigma, bounds, n_max_resampling, seed, population_size, cov)
n_dim = self._cma.dim
population_size = self._cma.population_size
self._n_max_resampling = n_max_resampling
# split discrete space and continuous space
assert len(bounds) == len(steps), "bounds and steps must be the same length"
assert not np.isnan(steps).any(), "steps should not include NaN"
self._discrete_idx = np.where(steps > 0)[0]
self._discrete_space_low = bounds[self._discrete_idx, 0]
requested_steps = steps[self._discrete_idx]
self._discrete_space_size = np.ceil(
(bounds[self._discrete_idx, 1] + requested_steps / 2 - self._discrete_space_low)
/ requested_steps
).astype(int)
# np.arange uses dtype(start + step) - dtype(start) as its actual step.
# Retain that behavior without materializing every value in the range.
self._discrete_space_step = (
self._discrete_space_low + requested_steps - self._discrete_space_low
)
# continuous_space contains low and high of each parameter.
self._continuous_idx = np.where(steps <= 0)[0]
self._continuous_space = bounds[self._continuous_idx]
assert _is_valid_bounds(self._continuous_space, mean[self._continuous_idx]), (
"invalid bounds"
)
# discrete_space
self._n_zdim = len(self._discrete_idx)
if self._n_zdim == 0:
return
assert np.all(self._discrete_space_size >= 2), (
"each discrete parameter must have at least two choices"
)
self.margin = margin if margin is not None else 1 / (n_dim * population_size)
assert self.margin > 0, "margin must be non-zero positive value."
m_z = self._cma._mean[self._discrete_idx]
# m_z_lim_low ->| mean vector |<- m_z_lim_up
self.m_z_lim_low, self.m_z_lim_up = self._get_discrete_param_limits(m_z)
self._A = np.full(n_dim, 1.0)
@property
def dim(self) -> int:
"""A number of dimensions"""
return self._cma.dim
@property
def population_size(self) -> int:
"""A population size"""
return self._cma.population_size
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when multi-variate gaussian distribution is updated."""
return self._cma.generation
@property
def mean(self) -> np.ndarray:
"""Mean Vector"""
return self._cma.mean
@property
def _rng(self) -> np.random.RandomState:
return self._cma._rng
def reseed_rng(self, seed: int) -> None:
self._cma.reseed_rng(seed)
def ask(self) -> tuple[np.ndarray, np.ndarray]:
"""Sample a parameter and return (i) encoded x and (ii) raw x.
The encoded x is used for the evaluation.
The raw x is used for updating the distribution."""
for i in range(self._n_max_resampling):
x = self._cma._sample_solution()
if self._is_continuous_feasible(x[self._continuous_idx]):
x_encoded = x.copy()
if self._n_zdim > 0:
x_encoded[self._discrete_idx] = self._encode_discrete_params(
x[self._discrete_idx]
)
return x_encoded, x
x = self._cma._sample_solution()
x[self._continuous_idx] = self._repair_continuous_params(x[self._continuous_idx])
x_encoded = x.copy()
if self._n_zdim > 0:
x_encoded[self._discrete_idx] = self._encode_discrete_params(x[self._discrete_idx])
return x_encoded, x
def _is_continuous_feasible(self, continuous_param: np.ndarray) -> bool:
if self._continuous_space is None:
return True
return cast(
bool,
np.all(continuous_param >= self._continuous_space[:, 0])
and np.all(continuous_param <= self._continuous_space[:, 1]),
) # Cast bool_ to bool.
def _repair_continuous_params(self, continuous_param: np.ndarray) -> np.ndarray:
if self._continuous_space is None:
return continuous_param
# clip with lower and upper bound.
param = np.where(
continuous_param < self._continuous_space[:, 0],
self._continuous_space[:, 0],
continuous_param,
)
param = np.where(param > self._continuous_space[:, 1], self._continuous_space[:, 1], param)
return param
def _encode_discrete_params(self, discrete_param: np.ndarray) -> np.ndarray:
"""Encode the values into discrete domain."""
mean = self._cma._mean
x = (discrete_param - mean[self._discrete_idx]) * self._A[self._discrete_idx] + mean[
self._discrete_idx
]
x_pos = self._get_discrete_param_indices(x)
return self._get_discrete_param_values(x_pos)
def _get_discrete_param_indices(self, values: np.ndarray) -> np.ndarray:
"""Return indices of the closest discrete values, preferring the lower value on ties."""
indices = np.floor(
(values - self._discrete_space_low) / self._discrete_space_step + 0.5
).astype(int)
indices = np.clip(indices, 0, self._discrete_space_size - 1)
# ``floor(x + 0.5)`` selects the upper value at an exact midpoint, while
# ``np.searchsorted`` used by the previous implementation selected the lower one.
has_lower_limit = indices > 0
lower_limits = self._get_discrete_param_limit_values(np.maximum(indices - 1, 0))
indices -= has_lower_limit & (values <= lower_limits)
# Correct a possible one-position error caused by floating-point division.
has_upper_limit = indices < self._discrete_space_size - 1
upper_limits = self._get_discrete_param_limit_values(
np.minimum(indices, self._discrete_space_size - 2)
)
indices += has_upper_limit & (values > upper_limits)
return indices
def _get_discrete_param_values(self, indices: np.ndarray) -> np.ndarray:
return self._discrete_space_low + indices * self._discrete_space_step
def _get_discrete_param_limit_values(self, indices: np.ndarray) -> np.ndarray:
lower_values = self._get_discrete_param_values(indices)
upper_values = self._get_discrete_param_values(indices + 1)
return (lower_values + upper_values) / 2
def _get_discrete_param_limits(self, values: np.ndarray) -> tuple[np.ndarray, np.ndarray]:
positions = self._get_discrete_param_indices(values)
lower_indices = np.clip(positions - 1, 0, self._discrete_space_size - 2)
upper_indices = np.clip(positions, 0, self._discrete_space_size - 2)
return (
self._get_discrete_param_limit_values(lower_indices),
self._get_discrete_param_limit_values(upper_indices),
)
def tell(self, solutions: list[tuple[np.ndarray, float]]) -> None:
"""Tell evaluation values"""
self._cma.tell(solutions)
mean = self._cma._mean
sigma = self._cma._sigma
C = self._cma._C
if self._n_zdim == 0:
return
# margin correction
updated_m_integer = mean[self._discrete_idx]
self.m_z_lim_low, self.m_z_lim_up = self._get_discrete_param_limits(updated_m_integer)
# calculate probability low_cdf := Pr(X <= m_z_lim_low) and up_cdf := Pr(m_z_lim_up < X)
# sig_z_sq_Cdiag = self.model.sigma * self.model.A * np.sqrt(np.diag(self.model.C))
z_scale = sigma * self._A[self._discrete_idx] * np.sqrt(np.diag(C)[self._discrete_idx])
low_cdf = norm_cdf(self.m_z_lim_low, loc=updated_m_integer, scale=z_scale)
up_cdf = 1.0 - norm_cdf(self.m_z_lim_up, loc=updated_m_integer, scale=z_scale)
mid_cdf = 1.0 - (low_cdf + up_cdf)
# edge case
edge_mask = np.maximum(low_cdf, up_cdf) > 0.5
# otherwise
side_mask = np.maximum(low_cdf, up_cdf) <= 0.5
if np.any(edge_mask):
# modify mask (modify or not)
modify_mask = np.minimum(low_cdf, up_cdf) < self.margin
# modify sign
modify_sign = np.sign(mean[self._discrete_idx] - self.m_z_lim_up)
# distance from m_z_lim_up
dist = (
sigma
* self._A[self._discrete_idx]
* np.sqrt(chi2_ppf(q=1.0 - 2.0 * self.margin) * np.diag(C)[self._discrete_idx])
)
# modify mean vector
mean[self._discrete_idx] = mean[self._discrete_idx] + modify_mask * edge_mask * (
self.m_z_lim_up + modify_sign * dist - mean[self._discrete_idx]
)
# correct probability
low_cdf = np.maximum(low_cdf, self.margin / 2.0)
up_cdf = np.maximum(up_cdf, self.margin / 2.0)
modified_low_cdf = low_cdf + (1.0 - low_cdf - up_cdf - mid_cdf) * (
low_cdf - self.margin / 2
) / (low_cdf + mid_cdf + up_cdf - 3.0 * self.margin / 2)
modified_up_cdf = up_cdf + (1.0 - low_cdf - up_cdf - mid_cdf) * (
up_cdf - self.margin / 2
) / (low_cdf + mid_cdf + up_cdf - 3.0 * self.margin / 2)
modified_low_cdf = np.clip(modified_low_cdf, 1e-10, 0.5 - 1e-10)
modified_up_cdf = np.clip(modified_up_cdf, 1e-10, 0.5 - 1e-10)
# modify mean vector and A (with sigma and C fixed)
chi_low_sq = np.sqrt(chi2_ppf(q=1.0 - 2 * modified_low_cdf))
chi_up_sq = np.sqrt(chi2_ppf(q=1.0 - 2 * modified_up_cdf))
C_diag_sq = np.sqrt(np.diag(C))[self._discrete_idx]
# simultaneous equations
self._A[self._discrete_idx] = self._A[self._discrete_idx] + side_mask * (
(self.m_z_lim_up - self.m_z_lim_low) / ((chi_low_sq + chi_up_sq) * sigma * C_diag_sq)
- self._A[self._discrete_idx]
)
mean[self._discrete_idx] = mean[self._discrete_idx] + side_mask * (
(self.m_z_lim_low * chi_up_sq + self.m_z_lim_up * chi_low_sq)
/ (chi_low_sq + chi_up_sq)
- mean[self._discrete_idx]
)
def should_stop(self) -> bool:
return self._cma.should_stop()
cmaes-0.13.1/cmaes/_comocatcmawm.py000066400000000000000000000564551524175644700171750ustar00rootroot00000000000000from __future__ import annotations
import numpy as np
from collections import deque
from dataclasses import dataclass, field
from typing import overload
from typing import List, Deque, Sequence, Union, Tuple, Iterator, Optional
from ._catcmawm import CatCMAwM
from ._uhvi_archiving import UHVIArchive2D
class AskQueueEmpty(RuntimeError):
"""No askable solutions are available right now."""
class COMOCatCMAwM:
"""COMO-CatCMA with Margin stochastic multi-objective optimizer class with
ask-and-tell interface.
Example:
.. code::
from cmaes import COMOCatCMAwM
def DSInt(x, z):
f1 = sum(x ** 2) + sum(z ** 2)
f2 = sum((x - 1) ** 2) + sum((z - 1) ** 2)
return [f1, f2]
X = [[-1, 2], [-1, 2]]
Z = [[0, 0.5, 1], [-0.5, 0, 0.5, 1, 1.5]]
optimizer = COMOCatCMAwM(x_space=X, z_space=Z)
evals = 0
while evals < 1000:
solutions = []
for sol in optimizer.ask_iter():
value = DSInt(sol.x, sol.z)
evals += 1
solutions.append((sol, value))
optimizer.tell(solutions)
print(evals, optimizer.incumbent_objectives)
Args:
x_space:
The search space for continuous variables.
Provide as a 2-dimensional sequence (e.g., a list of lists),
where each row is [lower_bound, upper_bound] for a continuous variable.
If there are no continuous variables, this parameter can be omitted.
Example: [[-3.0, 3.0], [0.0, 5.0], [-np.inf, np.inf]]
z_space:
The set of possible values for each integer variable.
Provide as a list of lists, where each inner list contains the valid
(sorted) integer or discretized values for that variable.
If there are no integer variables, this parameter can be omitted.
Example: [[-2, -1, 0, 1, 2], [0.01, 0.1, 1]]
Note: For binary variables (i.e., variables that can only take two distinct values),
it is generally recommended to use the categorical variable representation via
`c_space` rather than treating them as integer variables.
c_space:
The shape of the categorical variables' domain.
Provide as a 1-dimensional sequence (e.g., a list)
where each element specifies the number of categories (integer > 1)
for each categorical variable.
If there are no categorical variables, this parameter can be omitted.
Example: [3, 3, 2, 10]
Note: Binary variables (with only two possible values) should be represented as
categorical variables here, rather than as integer variables in `z_space`.
reference_point:
A fixed reference point for the objective space (optional).
kernels:
Initial CatCMAwM optimizers to run in parallel (optional).
kernel_size:
Number of internal CatCMAwM optimizers when 'kernels' is not supplied
(optional, default: 10).
seed:
A seed number (optional).
"""
# Paper: https://arxiv.org/abs/2504.07884
# Currently limited to 2 objectives due to 2D UHVI constraints; expansion is planned.
_MAX_OBJECTIVES: int = 2
@dataclass(frozen=True)
class Solution:
x: Optional[np.ndarray] = None # continuous variable
z: Optional[np.ndarray] = None # integer variable
c: Optional[np.ndarray] = None # categorical variable
_v_raw: Optional[np.ndarray] = field(default=None, repr=False) # internal use
_kernel_id: Optional[int] = field(default=None, repr=False) # internal use
_incumbent_id: Optional[int] = field(default=None, repr=False) # internal use
def __init__(
self,
x_space: Optional[Sequence[Sequence[float]]] = None,
z_space: Optional[Sequence[Sequence[Union[int, float]]]] = None,
c_space: Optional[Sequence[int]] = None,
reference_point: Optional[Sequence[float]] = None,
kernels: Optional[Sequence[CatCMAwM]] = None,
kernel_size: Optional[int] = None,
seed: Optional[int] = None,
):
# Determine space sizes
self._Nco = len(x_space) if x_space is not None else 0
self._Nin = len(z_space) if z_space is not None else 0
self._Nca = len(c_space) if c_space is not None else 0
self._Nmi = self._Nco + self._Nin
if self._Nmi + self._Nca <= 0:
raise ValueError("The total number of dimensions must be positive.")
self._use_continuous = self._Nco > 0
self._use_integer = self._Nin > 0
self._use_gaussian = self._Nmi > 0
self._use_categorical = self._Nca > 0
# global seed
self._rng = np.random.RandomState(seed)
# initialization of kernels
if kernels is None:
if kernel_size is None:
kernel_size = 10
if kernel_size <= 0:
raise ValueError("kernel_size must be positive.")
kernels = self._init_kernels(kernel_size, x_space, z_space, c_space)
self._kernel_size = len(kernels)
if self._kernel_size <= 0:
raise ValueError("The number of kernels must be positive.")
self._kernels = kernels
# Seed the global RNG and all internal kernels
if seed is not None:
self.reseed_rng(seed)
# generation number
self._g: int = 0
# Randomize kernel update sequence
self._kernel_pi: List[int] = (self._rng.permutation(self._kernel_size)).tolist()
self._kernel_index: int = 0
# Set up incumbent solutions and evaluation status
self._incumbents_sol = np.array(
[self.calc_incumbent_solution(i) for i in range(self._kernel_size)]
)
self._incumbents_obj: np.ndarray | None = None
self._incumbents_mask: int = 0
# Initialize objective dimension and user-provided reference point
self._n_obj: int | None = None
self._fixed_ref_point: np.ndarray | None = None
if reference_point is not None:
self._fixed_ref_point = self._coerce_objective_space_point(reference_point)
# for dynamic reference point
self._ideal_point: np.ndarray | None = None
self._nadir_point: np.ndarray | None = None
self._dynamic_ref_scale: float = 0.1
self._dynamic_ref_min_range: float = 1e-7
# queue for pending candidate solutions
self._ask_queue: Deque[COMOCatCMAwM.Solution] = deque()
# per-kernel buffers for tell observations
self._tell_lists: List[List[Tuple[COMOCatCMAwM.Solution, Sequence[float]]]] = [
[] for _ in range(self._kernel_size)
]
# Enqueue incumbent solutions of all kernels for evaluation
for i in range(self._kernel_size):
(
self._enqueue_kernel_asks
if i == self.current_kernel_id
else self._enqueue_kernel_incumbent
)(i)
def _init_kernels(
self,
kernel_size: int,
x_space: Optional[Sequence[Sequence[float]]] = None,
z_space: Optional[Sequence[Sequence[Union[int, float]]]] = None,
c_space: Optional[Sequence[int]] = None,
) -> Sequence[CatCMAwM]:
if not self._use_gaussian:
kernels = [
CatCMAwM(
x_space=x_space,
z_space=z_space,
c_space=c_space,
# CatCMAwM initializes cat_param uniformly
)
for _ in range(kernel_size)
]
return kernels
if x_space is not None:
x_range = np.asarray(x_space, dtype=float)
if x_range.ndim != 2 or x_range.shape[1] != 2:
raise ValueError(
f"x_space must be a two-dimensional array with shape (n, 2), "
f"but got shape {x_range.shape}."
)
invalid = np.where(x_range[:, 0] >= x_range[:, 1])[0]
if invalid.size > 0:
i = invalid[0]
lb, ub = x_range[i, 0], x_range[i, 1]
raise ValueError(
f"Lower bound must be less than upper bound at index {i}: {lb} >= {ub}."
)
if z_space is not None:
z_range = np.empty((len(z_space), 2), dtype=float)
for i, row in enumerate(z_space):
if len(row) < 2:
raise ValueError(
f"z_space must be a sequence of arrays with length >= 2. "
f"Found length {len(row)} at index {i}: {row}."
)
s = set(row)
if len(s) < len(row):
raise ValueError(
f"Elements in each array of z_space must be unique. "
f"Found duplicate at index {i}: {row}."
)
z_range[i, 0] = min(s)
z_range[i, 1] = max(s)
# bounds for the mixed continuous and integer space
if self._use_continuous and self._use_integer:
lower_x = x_range[:, 0]
upper_x = x_range[:, 1]
lower_z = z_range[:, 0]
upper_z = z_range[:, 1]
lower_g = np.concatenate([lower_x, lower_z])
upper_g = np.concatenate([upper_x, upper_z])
# bounds for the integer space
if not self._use_continuous and self._use_integer:
lower_g = z_range[:, 0]
upper_g = z_range[:, 1]
# bounds for the continuous space
if self._use_continuous and not self._use_integer:
lower_g = x_range[:, 0]
upper_g = x_range[:, 1]
# limit to finite range
neg_inf = np.isneginf(lower_g)
pos_inf = np.isposinf(upper_g)
both = neg_inf & pos_inf
only_low = neg_inf & ~pos_inf
only_up = pos_inf & ~neg_inf
lower_g[both] = -1.0
upper_g[both] = 1.0
lower_g[only_low] = upper_g[only_low] - 2.0
upper_g[only_up] = lower_g[only_up] + 2.0
# Uniform sampling for initial mean vectors
init_means = self._rng.uniform(lower_g, upper_g, size=(kernel_size, self._Nmi))
# Set initial standard deviation to
# width / 6 (continuous)
# width / 5 (integer)
width = upper_g - lower_g
init_cov = np.diag(width / np.where(np.arange(self._Nmi) < self._Nco, 6, 5))
kernels = [
CatCMAwM(
x_space=x_space,
z_space=z_space,
c_space=c_space,
mean=init_mean,
cov=init_cov,
# CatCMAwM initializes cat_param uniformly
)
for init_mean in init_means
]
return kernels
@property
def generation(self) -> int:
"""Generation number incremented after all kernels are updated once."""
return self._g
@property
def kernel_size(self) -> int:
"""Number of kernels."""
return self._kernel_size
@property
def ask_queue_size(self) -> int:
"""Number of solutions currently available to ask."""
return len(self._ask_queue)
@property
def current_kernel_id(self) -> int:
"""ID of the currently active kernel."""
return self._kernel_pi[self._kernel_index]
@property
def kernels(self) -> Sequence[CatCMAwM]:
"""List of all internal kernel optimizers."""
return self._kernels
@property
def current_kernel(self) -> CatCMAwM:
"""The currently active kernel instance."""
return self._kernels[self.current_kernel_id]
@property
def incumbent_solutions(self) -> np.ndarray:
"""Incumbent solutions for all kernels."""
return self._incumbents_sol
@property
def incumbent_objectives(self) -> np.ndarray | None:
"""Objective values of the incumbent solutions."""
return self._incumbents_obj
def reseed_rng(self, seed: int) -> None:
"""Set the global seed and reseed the kernels."""
self._rng.seed(seed)
subseeds = self._rng.randint(0, 2**32, size=self._kernel_size, dtype=np.uint32)
for kernel, s in zip(self._kernels, subseeds):
kernel.reseed_rng(int(s))
def calc_incumbent_solution(self, kernel_id: int) -> CatCMAwM.Solution:
"""Compute a kernel's incumbent solution."""
if not (0 <= kernel_id < self._kernel_size):
raise IndexError(f"kernel_id must be in [0, {self._kernel_size}), got {kernel_id}.")
ker = self._kernels[kernel_id]
x = None
z = None
c = None
v_raw = None
if ker._use_gaussian:
v_raw = ker._mean
if ker._use_continuous:
x = ker._mean[ker._continuous_idx]
if ker._use_integer:
z = ker._discretization(ker._mean[ker._discrete_idx])
if ker._use_categorical:
row_max = ker._q.max(axis=1, keepdims=True)
tie_mask = ker._q == row_max
argmax_index = np.where(tie_mask, ker._rng.random(ker._q.shape), -np.inf).argmax(
axis=1
)
c = np.zeros_like(ker._q, dtype=bool)
c[np.arange(ker._q.shape[0]), argmax_index] = True
return CatCMAwM.Solution(x, z, c, v_raw)
def _coerce_objective_space_point(self, point: Sequence[float]) -> np.ndarray:
"""
Coerce and validate a point in objective space.
Accepts array-like input and returns a 1-D float numpy array.
"""
# Coerce array-like input (e.g., list/tuple) to a float numpy array
p = np.asarray(point, dtype=float)
# Objective-space points are represented as 1-D vectors of length = number of objectives
if p.ndim != 1:
raise ValueError(f"Objective-space point must be 1-D, got shape={p.shape}.")
p_n_obj: int = p.shape[0]
# Infer the objective dimension from the first observed point
# Subsequent points must be consistent with the configured dimension
if self._n_obj is None:
self._n_obj = p_n_obj
# Initialize objective tracking array once the dimension is known
self._incumbents_obj = np.full((self._kernel_size, self._n_obj), np.nan, dtype=float)
else:
if self._n_obj != p_n_obj:
raise ValueError(
f"Inconsistent objective dimension: expected {self._n_obj}, got {p_n_obj}."
)
# This optimizer is multi-objective; single-objective (dim=1) is not supported here
if p_n_obj <= 1:
raise ValueError(f"Objective dimension must be >= 2, got {p_n_obj}.")
# Guardrail for future extensions: the supported objective dimension may be increased later
if p_n_obj > self._MAX_OBJECTIVES:
raise NotImplementedError(
f"Objective dimension {p_n_obj} is not supported yet "
f"(currently supports up to {self._MAX_OBJECTIVES})."
)
# Return the coerced numpy representation
return p
def _increment_kernel_index(self) -> None:
self._kernel_index += 1
if self._kernel_index == self._kernel_size:
self._g += 1
self._kernel_index = 0
self._kernel_pi = (self._rng.permutation(self._kernel_size)).tolist()
def _update_ideal_nadir(self, obj: np.ndarray) -> None:
if self._ideal_point is None or self._nadir_point is None:
self._ideal_point = obj.copy()
self._nadir_point = obj.copy()
else:
self._ideal_point = np.minimum(self._ideal_point, obj)
self._nadir_point = np.maximum(self._nadir_point, obj)
def _get_reference_point(self) -> np.ndarray:
"""Return the reference point (fixed if provided; otherwise inferred from ideal/nadir).
Dynamic inference mirrors BoTorch's `infer_reference_point`.
Default scaling is motivated by Ishibuchi et al. (GECCO 2011).
BoTorch source:
https://botorch.readthedocs.io/en/latest/_modules/botorch/utils/multi_objective/hypervolume.html
Ishibuchi et al. (GECCO 2011):
Hisao Ishibuchi, Naoya Akedo, and Yusuke Nojima. A many-objective test problem
for visually examining diversity maintenance behavior in a decision space.
"""
if self._fixed_ref_point is not None:
return self._fixed_ref_point
if self._ideal_point is None or self._nadir_point is None:
raise RuntimeError(
"Reference point cannot be inferred yet: no objective values have been observed."
)
obj_range = self._nadir_point - self._ideal_point
obj_range = np.maximum(obj_range, self._dynamic_ref_min_range)
ref_point = self._nadir_point + self._dynamic_ref_scale * obj_range
return ref_point
def _UHVI(self, objective: np.ndarray, kernel_id_to_omit: int) -> float:
if self._incumbents_obj is None:
raise ValueError("UHVI unavailable: no incumbent objectives have been recorded yet.")
ref_point = self._get_reference_point()
# Build incumbents_obj excluding kernel_id_to_omit
mask = np.ones(self._kernel_size, dtype=bool)
mask[kernel_id_to_omit] = False
front = UHVIArchive2D(self._incumbents_obj[mask])
uhvi_indicator = front.uhvi(objective, ref_point)
return uhvi_indicator
def _enqueue_kernel_asks(self, kernel_id: int) -> None:
"""Enqueue all candidate solutions from a specific kernel for evaluation."""
for _ in range(self._kernels[kernel_id].population_size):
sol = self._kernels[kernel_id].ask()
self._ask_queue.append(
COMOCatCMAwM.Solution(
x=sol.x,
z=sol.z,
c=sol.c,
_v_raw=sol._v_raw,
_kernel_id=kernel_id,
_incumbent_id=None,
)
)
def _enqueue_kernel_incumbent(self, kernel_id: int) -> None:
"""Enqueue the incumbent solution of a specific kernel for evaluation."""
incumbent_sol = self.calc_incumbent_solution(kernel_id)
self._ask_queue.append(
COMOCatCMAwM.Solution(
x=incumbent_sol.x,
z=incumbent_sol.z,
c=incumbent_sol.c,
_v_raw=incumbent_sol._v_raw,
_kernel_id=None,
_incumbent_id=kernel_id,
)
)
def _update_validation(self) -> bool:
kid = self.current_kernel_id
# all other kernels' incumbents must be evaluated
if (self._incumbents_mask | (1 << kid)) != (1 << self._kernel_size) - 1:
return False
# must have exactly one full batch of tells for this kernel
if len(self._tell_lists[kid]) < self._kernels[kid].population_size:
return False
elif len(self._tell_lists[kid]) > self._kernels[kid].population_size:
raise RuntimeError(
f"tell-list overflow for kernel {kid}: "
f"size={len(self._tell_lists[kid])} > "
f"population_size={self._kernels[kid].population_size}."
)
return True
def _kernel_tell(self, kernel_id: int) -> None:
assert len(self._tell_lists[kernel_id]) == self._kernels[kernel_id].population_size, (
"Tell list size does not match the corresponding kernel's population size."
)
expected_mask = (1 << self._kernel_size) - 1
assert (self._incumbents_mask | (1 << kernel_id)) == expected_mask, (
"All incumbents other than kernel_id must already be evaluated."
)
solutions = []
for sol in self._tell_lists[kernel_id]:
catcmawm_sol = CatCMAwM.Solution(sol[0].x, sol[0].z, sol[0].c, sol[0]._v_raw)
obj = self._coerce_objective_space_point(sol[1])
uhvi = self._UHVI(obj, kernel_id)
# UHVI is maximized; negate for CatCMAwM's minimization
solutions.append((catcmawm_sol, -uhvi))
self._kernels[kernel_id].tell(solutions)
self._tell_lists[kernel_id].clear()
def ask(self) -> COMOCatCMAwM.Solution:
"""Retrieve a candidate solution from the internal evaluation queue.
Returns:
Solution: A Solution object containing continuous (x),
integer (z), and/or categorical (c) variables.
"""
if not self._ask_queue:
raise AskQueueEmpty(
"No solutions available to ask. Check ask_queue_size or iterate with ask_iter()."
)
sol = self._ask_queue.popleft()
return sol
def ask_iter(self, limit: int | None = None) -> Iterator[COMOCatCMAwM.Solution]:
"""Yield solutions until the ask-queue is empty or 'limit' is reached.
Does not raise even when the queue becomes empty."""
i = 0
while self.ask_queue_size and (limit is None or i < limit):
yield self.ask()
i += 1
@overload
def tell( # NOQA: E704
self, observation: Tuple[COMOCatCMAwM.Solution, Sequence[float]]
) -> None: ...
@overload
def tell( # NOQA: E704
self, observation: List[Tuple[COMOCatCMAwM.Solution, Sequence[float]]]
) -> None: ...
def tell(
self,
observation: (
Tuple[COMOCatCMAwM.Solution, Sequence[float]]
| List[Tuple[COMOCatCMAwM.Solution, Sequence[float]]]
),
) -> None:
"""Update the optimizer with the evaluation results of candidate solutions.
Args:
observation: A single (Solution, objective_values) pair or
a list of such pairs.
"""
# normalize to a list of pairs
if isinstance(observation, list):
solutions = observation
elif isinstance(observation, tuple) and len(observation) == 2:
solutions = [observation]
else:
raise TypeError(
"tell expects either a (Solution, Sequence[float]) or a list of such tuples."
)
for sol in solutions:
obj = self._coerce_objective_space_point(sol[1])
self._update_ideal_nadir(obj)
kernel_id = sol[0]._kernel_id
incumbent_id = sol[0]._incumbent_id
if kernel_id is not None and incumbent_id is None:
self._tell_lists[kernel_id].append(sol)
elif kernel_id is None and incumbent_id is not None:
self._incumbents_sol[incumbent_id] = CatCMAwM.Solution(
sol[0].x, sol[0].z, sol[0].c, sol[0]._v_raw
)
if self._incumbents_obj is None:
raise RuntimeError("Incumbent objectives buffer is not initialized.")
self._incumbents_obj[incumbent_id] = sol[1]
# Set evaluated flag for this incumbent
self._incumbents_mask |= 1 << incumbent_id
else:
pass
if self._update_validation():
self._kernel_tell(self.current_kernel_id)
self._enqueue_kernel_incumbent(self.current_kernel_id)
# Clear evaluated flag for the current kernel
self._incumbents_mask &= ~(1 << self.current_kernel_id)
self._increment_kernel_index()
self._enqueue_kernel_asks(self.current_kernel_id)
cmaes-0.13.1/cmaes/_dxnesic.py000066400000000000000000000337431524175644700161530ustar00rootroot00000000000000from __future__ import annotations
import math
import sys
import numpy as np
from typing import cast
from typing import Optional
_EPS = 1e-8
_MEAN_MAX = 1e32
_SIGMA_MAX = 1e32
class DXNESIC:
"""DX-NES-IC stochastic optimizer class with ask-and-tell interface.
Example:
.. code::
import numpy as np
from cmaes import DXNESIC
def quadratic(x1, x2):
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
optimizer = DXNESIC(mean=np.zeros(2), sigma=1.3)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x = optimizer.ask()
value = quadratic(x[0], x[1])
solutions.append((x, value))
print(f"#{generation} {value} (x1={x[0]}, x2 = {x[1]})")
# Tell evaluation values.
optimizer.tell(solutions)
Args:
mean:
Initial mean vector of multi-variate gaussian distributions.
sigma:
Initial standard deviation of covariance matrix.
bounds:
Lower and upper domain boundaries for each parameter (optional).
n_max_resampling:
A maximum number of resampling parameters (default: 100).
If all sampled parameters are infeasible, the last sampled one
will be clipped with lower and upper bounds.
seed:
A seed number (optional).
population_size:
A population size (optional).
cov:
A covariance matrix (optional).
"""
# Paper: https://ieeexplore.ieee.org/abstract/document/9504865
def __init__(
self,
mean: np.ndarray,
sigma: float,
bounds: Optional[np.ndarray] = None,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
):
assert sigma > 0, "sigma must be non-zero positive value"
assert np.all(np.abs(mean) < _MEAN_MAX), (
f"Abs of all elements of mean vector must be less than {_MEAN_MAX}"
)
n_dim = len(mean)
assert n_dim > 1, "The dimension of mean must be larger than 1"
if population_size is None:
population_size = 4 + math.floor(3 * math.log(n_dim))
assert population_size > 0, "popsize must be non-zero positive value."
w_rank_hat = np.log(population_size / 2 + 1) - np.log(np.arange(1, population_size + 1))
w_rank_hat[np.where(w_rank_hat < 0)] = 0
w_rank = w_rank_hat / sum(w_rank_hat) - (1.0 / population_size)
mu_eff = 1 / sum((w_rank + (1.0 / population_size)) ** 2)
# learning rate for the cumulation for the step-size control
c_sigma = (mu_eff + 2) / (n_dim + mu_eff + 5)
assert c_sigma < 1, "invalid learning rate for cumulation for the step-size control"
# distance weight parameter
h_inv = _get_h_inv(n_dim)
self._n_dim = n_dim
self._popsize = population_size
self._mu_eff = mu_eff
self._h_inv = h_inv
self._c_sigma = c_sigma
# E||N(0, I)||
self._chi_n = math.sqrt(self._n_dim) * (
1.0 - (1.0 / (4.0 * self._n_dim)) + 1.0 / (21.0 * (self._n_dim**2))
)
# weights
self._w_rank = w_rank
self._w_rank_hat = w_rank_hat
# for antithetic sampling
self._zsym: Optional[np.ndarray] = None
# learning rate
self._eta_mean = 1.0
self._eta_move_sigma = 1.0
self._c_gamma = 1.0 / (3.0 * (n_dim - 1.0))
self._d_gamma = min(1.0, n_dim / population_size)
self._gamma = 1.0
# evolution path
self._p_sigma = np.zeros(n_dim)
# distribution parameter
self._mean = mean.copy()
self._sigma = sigma
self._B = np.eye(n_dim)
# bounds contains low and high of each parameter.
assert bounds is None or _is_valid_bounds(bounds, mean), "invalid bounds"
self._bounds = bounds
self._n_max_resampling = n_max_resampling
self._g = 0
self._rng = np.random.RandomState(seed)
# Termination criteria
self._tolx = 1e-12 * sigma
self._tolxup = 1e4
self._tolfun = 1e-12
self._tolconditioncov = 1e14
self._funhist_term = 10 + math.ceil(30 * n_dim / population_size)
self._funhist_values = np.empty(self._funhist_term * 2)
@property
def dim(self) -> int:
"""A number of dimensions"""
return self._n_dim
@property
def population_size(self) -> int:
"""A population size"""
return self._popsize
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when multi-variate gaussian distribution is updated."""
return self._g
def _alpha_dist(self, num_feasible: int) -> float:
return (
self._h_inv
* min(1.0, math.sqrt(float(self._popsize) / self._n_dim))
* math.sqrt(float(num_feasible) / self._popsize)
)
def _w_dist_hat(self, z: np.ndarray, num_feasible: int) -> float:
return math.exp(self._alpha_dist(num_feasible) * np.linalg.norm(z))
def _eta_stag_sigma(self, num_feasible: int) -> float:
return math.tanh((0.024 * num_feasible + 0.7 * self._n_dim + 20.0) / (self._n_dim + 12.0))
def _eta_conv_sigma(self, num_feasible: int) -> float:
return 2.0 * math.tanh(
(0.025 * num_feasible + 0.75 * self._n_dim + 10.0) / (self._n_dim + 4.0)
)
def _eta_move_B(self, num_feasible: int) -> float:
return 180 * self._n_dim * math.tanh(0.02 * num_feasible) / (47 * (self._n_dim**2) + 6400)
def _eta_stag_B(self, num_feasible: int) -> float:
return 168 * self._n_dim * math.tanh(0.02 * num_feasible) / (47 * (self._n_dim**2) + 6400)
def _eta_conv_B(self, num_feasible: int) -> float:
return 12 * self._n_dim * math.tanh(0.02 * num_feasible) / (47 * (self._n_dim**2) + 6400)
def reseed_rng(self, seed: int) -> None:
self._rng.seed(seed)
def set_bounds(self, bounds: Optional[np.ndarray]) -> None:
"""Update boundary constraints"""
assert bounds is None or _is_valid_bounds(bounds, self._mean), "invalid bounds"
self._bounds = bounds
def ask(self) -> np.ndarray:
"""Sample a parameter"""
for i in range(self._n_max_resampling):
x = self._sample_solution()
if self._is_feasible(x):
return x
x = self._sample_solution()
x = self._repair_infeasible_params(x)
return x
def _sample_solution(self) -> np.ndarray:
# antithetic sampling
if self._zsym is None:
z = self._rng.randn(self._n_dim) # ~ N(0, I)
self._zsym = z
else:
z = -self._zsym
self._zsym = None
x = self._mean + self._sigma * self._B.dot(z) # ~ N(m, σ^2 B B^T)
return x
def _is_feasible(self, param: np.ndarray) -> bool:
if self._bounds is None:
return True
return cast(
bool,
np.all(param >= self._bounds[:, 0]) and np.all(param <= self._bounds[:, 1]),
) # Cast bool_ to bool.
def _repair_infeasible_params(self, param: np.ndarray) -> np.ndarray:
if self._bounds is None:
return param
# clip with lower and upper bound.
param = np.where(param < self._bounds[:, 0], self._bounds[:, 0], param)
param = np.where(param > self._bounds[:, 1], self._bounds[:, 1], param)
return param
def tell(self, solutions: list[tuple[np.ndarray, float]]) -> None:
"""Tell evaluation values"""
assert len(solutions) == self._popsize, "Must tell popsize-length solutions."
for s in solutions:
assert np.all(np.abs(s[0]) < _MEAN_MAX), (
f"Abs of all param values must be less than {_MEAN_MAX} to avoid overflow errors"
)
# counting # feasible solutions
lamb_feas = len([s[1] for s in solutions if s[1] < sys.maxsize])
self._g += 1
solutions.sort(key=lambda s: s[1])
# Stores 'best' and 'worst' values of the
# last 'self._funhist_term' generations.
funhist_idx = 2 * (self.generation % self._funhist_term)
self._funhist_values[funhist_idx] = solutions[0][1]
self._funhist_values[funhist_idx + 1] = solutions[-1][1]
z_k = np.array(
[np.linalg.inv(self._sigma * self._B).dot(s[0] - self._mean) for s in solutions]
)
# Evolution path
z_w = np.sum(z_k.T * self._w_rank, axis=1)
self._p_sigma = (1 - self._c_sigma) * self._p_sigma + math.sqrt(
self._c_sigma * (2 - self._c_sigma) * self._mu_eff
) * z_w
norm_p_sigma = np.linalg.norm(self._p_sigma)
# switching learning rate depending on search situation
movement_phase = norm_p_sigma >= self._chi_n
# distance weight
w_dist_tmp = np.array(
[
self._w_rank_hat[i] * self._w_dist_hat(z_k[i, :], lamb_feas)
for i in range(self.population_size)
]
)
w_dist = w_dist_tmp / sum(w_dist_tmp) - 1.0 / self.population_size
# switching weights and learning rate
w = w_dist if movement_phase else self._w_rank
eta_sigma = (
self._eta_move_sigma
if norm_p_sigma >= self._chi_n
else (
self._eta_stag_sigma(lamb_feas)
if norm_p_sigma >= 0.1 * self._chi_n
else self._eta_conv_sigma(lamb_feas)
)
)
eta_B = (
self._eta_move_B(lamb_feas)
if norm_p_sigma >= self._chi_n
else (
self._eta_stag_B(lamb_feas)
if norm_p_sigma >= 0.1 * self._chi_n
else self._eta_conv_B(lamb_feas)
)
)
# natural gradient estimation in local coordinate
G_delta = np.sum([w[i] * z_k[i, :] for i in range(self.population_size)], axis=0)
G_M = np.sum(
[
w[i] * (np.outer(z_k[i, :], z_k[i, :]) - np.eye(self._n_dim))
for i in range(self.population_size)
],
axis=0,
)
G_sigma = G_M.trace() / self._n_dim
G_B = G_M - G_sigma * np.eye(self._n_dim)
# parameter update
bBBT = self._B @ self._B.T
self._mean += self._eta_mean * self._sigma * np.dot(self._B, G_delta)
self._sigma *= math.exp((eta_sigma / 2.0) * G_sigma)
# self._B = self._B.dot(expm((eta_B / 2.0) * G_B))
self._B = self._B.dot(_expm((eta_B / 2.0) * G_B))
aBBT = self._B @ self._B.T
# emphasizing expansion
e, v = np.linalg.eigh(bBBT)
tau_vec = [
(v[:, i].reshape(self._n_dim, 1).T @ aBBT @ v[:, i].reshape(self._n_dim, 1))
/ (v[:, i].reshape(self._n_dim, 1).T @ bBBT @ v[:, i].reshape(self._n_dim, 1))
- 1
for i in range(self._n_dim)
]
flg_tau = [1.0 if tau_vec[i] > 0 else 0.0 for i in range(self._n_dim)]
tau = max(tau_vec)
gamma = max(
(1.0 - self._c_gamma) * self._gamma
+ self._c_gamma * math.sqrt(1.0 + self._d_gamma * tau),
1.0,
)
if movement_phase:
Q = (gamma - 1.0) * np.sum(
[flg_tau[i] * np.outer(v[:, i], v[:, i]) for i in range(self._n_dim)],
axis=0,
) + np.eye(self._n_dim)
stepQ = math.pow(np.linalg.det(Q), 1.0 / self._n_dim)
self._sigma *= stepQ
self._B = Q @ self._B / stepQ
def should_stop(self) -> bool:
A = self._B.dot(self._B.T)
A = (A + A.T) / 2
E2, V = np.linalg.eigh(A)
E = np.sqrt(np.where(E2 < 0, _EPS, E2))
diagA = np.diag(A)
# Stop if the range of function values of the recent generation is below tolfun.
if (
self.generation > self._funhist_term
and np.max(self._funhist_values) - np.min(self._funhist_values) < self._tolfun
):
return True
# Stop if detecting divergent behavior.
if self._sigma * np.max(E) > self._tolxup:
return True
# No effect coordinates: stop if adding 0.2-standard deviations
# in any single coordinate does not change m.
if np.any(self._mean == self._mean + (0.2 * self._sigma * np.sqrt(diagA))):
return True
# No effect axis: stop if adding 0.1-standard deviation vector in
# any principal axis direction of C does not change m. "pycma" check
# axis one by one at each generation.
i = self.generation % self.dim
if np.all(self._mean == self._mean + (0.1 * self._sigma * E[i] * V[:, i])):
return True
# Stop if the condition number of the covariance matrix exceeds 1e14.
condition_cov = np.max(E) / np.min(E)
if condition_cov > self._tolconditioncov:
return True
return False
def _is_valid_bounds(bounds: Optional[np.ndarray], mean: np.ndarray) -> bool:
if bounds is None:
return True
if (mean.size, 2) != bounds.shape:
return False
if not np.all(bounds[:, 0] <= mean):
return False
if not np.all(mean <= bounds[:, 1]):
return False
return True
def _get_h_inv(dim: int) -> float:
def f(a: float) -> float:
return ((1.0 + a * a) * math.exp(a * a / 2.0) / 0.24) - 10.0 - dim
def f_prime(a: float) -> float:
return (1.0 / 0.24) * a * math.exp(a * a / 2.0) * (3.0 + a * a)
h_inv = 6.0
while abs(f(h_inv)) > 1e-10:
last = h_inv
h_inv = h_inv - 0.5 * (f(h_inv) / f_prime(h_inv))
if abs(h_inv - last) < 1e-16:
# Exit early since no further improvements are happening
break
return h_inv
def _expm(mat: np.ndarray) -> np.ndarray:
D, U = np.linalg.eigh(mat)
expD = np.exp(D)
return U @ np.diag(expD) @ U.T
cmaes-0.13.1/cmaes/_mapcma.py000066400000000000000000000335421524175644700157510ustar00rootroot00000000000000from __future__ import annotations
import math
import numpy as np
from typing import Any
from typing import cast
from typing import Optional
_EPS = 1e-8
_MEAN_MAX = 1e32
_SIGMA_MAX = 1e32
class MAPCMA:
"""MAP-CMA stochastic optimizer class with ask-and-tell interface.
The only difference from the CMA-ES is the additional term in the mean vector update.
Example:
.. code::
import numpy as np
from cmaes import MAPCMA
def quadratic(x1, x2):
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
optimizer = MAPCMA(mean=np.zeros(2), sigma=1.3)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x = optimizer.ask()
value = quadratic(x[0], x[1])
solutions.append((x, value))
print(f"#{generation} {value} (x1={x[0]}, x2 = {x[1]})")
# Tell evaluation values.
optimizer.tell(solutions)
Args:
mean:
Initial mean vector of multi-variate gaussian distributions.
sigma:
Initial standard deviation of covariance matrix.
bounds:
Lower and upper domain boundaries for each parameter (optional).
n_max_resampling:
A maximum number of resampling parameters (default: 100).
If all sampled parameters are infeasible, the last sampled one
will be clipped with lower and upper bounds.
seed:
A seed number (optional).
population_size:
A population size (optional).
cov:
A covariance matrix (optional).
momentum_r:
Scaling ratio of momentum update (optional).
"""
# Paper: https://arxiv.org/abs/2406.16506
def __init__(
self,
mean: np.ndarray,
sigma: float,
bounds: Optional[np.ndarray] = None,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
cov: Optional[np.ndarray] = None,
momentum_r: Optional[float] = None,
):
assert sigma > 0, "sigma must be non-zero positive value"
assert np.all(np.abs(mean) < _MEAN_MAX), (
f"Abs of all elements of mean vector must be less than {_MEAN_MAX}"
)
n_dim = len(mean)
assert n_dim > 1, "The dimension of mean must be larger than 1"
if population_size is None:
population_size = 4 + math.floor(3 * math.log(n_dim))
assert population_size > 0, "popsize must be non-zero positive value."
mu = population_size // 2
# MAPCMA uses positive weights, in accordance with the paper
# (CMA uses negative weights)
weights_prime = np.array(
[
math.log((population_size + 1) / 2) - math.log(i + 1) if i < mu else 0
for i in range(population_size)
]
)
weights = weights_prime / weights_prime.sum()
mu_eff = 1 / ((weights**2).sum())
# learning rate for the rank-one update
alpha_cov = 2
c1 = alpha_cov / ((n_dim + 1.3) ** 2 + mu_eff)
# learning rate for the rank-μ update
cmu = min(
1 - c1 - 1e-8, # 1e-8 is for large popsize.
alpha_cov * (mu_eff - 2 + 1 / mu_eff) / ((n_dim + 2) ** 2 + alpha_cov * mu_eff / 2),
)
assert c1 <= 1 - cmu, "invalid learning rate for the rank-one update"
assert cmu <= 1 - c1, "invalid learning rate for the rank-μ update"
# scaling ratio of momentum update
if momentum_r is None:
momentum_r = n_dim
assert momentum_r > 0, "scaling ratio of momentum update must be non-zero positive value."
self._r = momentum_r
# learning rate for the cumulation for the step-size control
c_sigma = (mu_eff + 2) / (n_dim + mu_eff + 5)
d_sigma = 1 + 2 * max(0, math.sqrt((mu_eff - 1) / (n_dim + 1)) - 1) + c_sigma
assert c_sigma < 1, "invalid learning rate for cumulation for the step-size control"
# learning rate for cumulation for the rank-one update
cc = (4 + mu_eff / n_dim) / (n_dim + 4 + 2 * mu_eff / n_dim)
assert cc <= 1, "invalid learning rate for cumulation for the rank-one update"
self._n_dim = n_dim
self._popsize = population_size
self._mu = mu
self._mu_eff = mu_eff
self._cc = cc
self._c1 = c1
self._cmu = cmu
self._c_sigma = c_sigma
self._d_sigma = d_sigma
# ensuring cm + cm * c1 / (r * cmu) = 1
self._cm = 1 / (1 + c1 / (self._r * cmu))
# E||N(0, I)||
self._chi_n = math.sqrt(self._n_dim) * (
1.0 - (1.0 / (4.0 * self._n_dim)) + 1.0 / (21.0 * (self._n_dim**2))
)
self._weights = weights
# evolution path
self._p_sigma = np.zeros(n_dim)
self._pc = np.zeros(n_dim)
self._mean = mean.copy()
if cov is None:
self._C = np.eye(n_dim)
else:
assert cov.shape == (n_dim, n_dim), "Invalid shape of covariance matrix"
self._C = cov
self._sigma = sigma
self._D: Optional[np.ndarray] = None
self._B: Optional[np.ndarray] = None
# bounds contains low and high of each parameter.
assert bounds is None or _is_valid_bounds(bounds, mean), "invalid bounds"
self._bounds = bounds
self._n_max_resampling = n_max_resampling
self._g = 0
self._rng = np.random.RandomState(seed)
# Termination criteria
self._tolx = 1e-12 * sigma
self._tolxup = 1e4
self._tolfun = 1e-12
self._tolconditioncov = 1e14
self._funhist_term = 10 + math.ceil(30 * n_dim / population_size)
self._funhist_values = np.empty(self._funhist_term * 2)
def __getstate__(self) -> dict[str, Any]:
attrs = {}
for name in self.__dict__:
# Remove _rng in pickle serialized object.
if name == "_rng":
continue
if name == "_C":
sym1d = _compress_symmetric(self._C)
attrs["_c_1d"] = sym1d
continue
attrs[name] = getattr(self, name)
return attrs
def __setstate__(self, state: dict[str, Any]) -> None:
state["_C"] = _decompress_symmetric(state["_c_1d"])
del state["_c_1d"]
self.__dict__.update(state)
# Set _rng for unpickled object.
setattr(self, "_rng", np.random.RandomState())
@property
def dim(self) -> int:
"""A number of dimensions"""
return self._n_dim
@property
def population_size(self) -> int:
"""A population size"""
return self._popsize
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when multi-variate gaussian distribution is updated."""
return self._g
@property
def mean(self) -> np.ndarray:
"""Mean Vector"""
return self._mean
def reseed_rng(self, seed: int) -> None:
self._rng.seed(seed)
def set_bounds(self, bounds: Optional[np.ndarray]) -> None:
"""Update boundary constraints"""
assert bounds is None or _is_valid_bounds(bounds, self._mean), "invalid bounds"
self._bounds = bounds
def ask(self) -> np.ndarray:
"""Sample a parameter"""
for i in range(self._n_max_resampling):
x = self._sample_solution()
if self._is_feasible(x):
return x
x = self._sample_solution()
x = self._repair_infeasible_params(x)
return x
def _eigen_decomposition(self) -> tuple[np.ndarray, np.ndarray]:
if self._B is not None and self._D is not None:
return self._B, self._D
self._C = (self._C + self._C.T) / 2
D2, B = np.linalg.eigh(self._C)
D = np.sqrt(np.where(D2 < 0, _EPS, D2))
self._C = np.dot(np.dot(B, np.diag(D**2)), B.T)
self._B, self._D = B, D
return B, D
def _sample_solution(self) -> np.ndarray:
B, D = self._eigen_decomposition()
z = self._rng.randn(self._n_dim) # ~ N(0, I)
y = cast(np.ndarray, B.dot(np.diag(D))).dot(z) # ~ N(0, C)
x = self._mean + self._sigma * y # ~ N(m, σ^2 C)
return x
def _is_feasible(self, param: np.ndarray) -> bool:
if self._bounds is None:
return True
return cast(
bool,
np.all(param >= self._bounds[:, 0]) and np.all(param <= self._bounds[:, 1]),
) # Cast bool_ to bool.
def _repair_infeasible_params(self, param: np.ndarray) -> np.ndarray:
if self._bounds is None:
return param
# clip with lower and upper bound.
param = np.where(param < self._bounds[:, 0], self._bounds[:, 0], param)
param = np.where(param > self._bounds[:, 1], self._bounds[:, 1], param)
return param
def tell(self, solutions: list[tuple[np.ndarray, float]]) -> None:
"""Tell evaluation values"""
assert len(solutions) == self._popsize, "Must tell popsize-length solutions."
for s in solutions:
assert np.all(np.abs(s[0]) < _MEAN_MAX), (
f"Abs of all param values must be less than {_MEAN_MAX} to avoid overflow errors"
)
self._g += 1
solutions.sort(key=lambda s: s[1])
# Stores 'best' and 'worst' values of the
# last 'self._funhist_term' generations.
funhist_idx = 2 * (self.generation % self._funhist_term)
self._funhist_values[funhist_idx] = solutions[0][1]
self._funhist_values[funhist_idx + 1] = solutions[-1][1]
# Sample new population of search_points, for k=1, ..., popsize
B, D = self._eigen_decomposition()
self._B, self._D = None, None
x_k = np.array([s[0] for s in solutions]) # ~ N(m, σ^2 C)
y_k = (x_k - self._mean) / self._sigma # ~ N(0, C)
# Selection and recombination
y_w = np.sum(y_k.T * self._weights, axis=1)
# Evolution paths
# MAP-CMA does not employ the Heaviside function h_sigma for simplifying the update rules.
C_2 = cast(
np.ndarray, cast(np.ndarray, B.dot(np.diag(1 / D))).dot(B.T)
) # C^(-1/2) = B D^(-1) B^T
self._p_sigma = (1 - self._c_sigma) * self._p_sigma + math.sqrt(
self._c_sigma * (2 - self._c_sigma) * self._mu_eff
) * C_2.dot(y_w)
self._pc = (1 - self._cc) * self._pc + math.sqrt(
self._cc * (2 - self._cc) * self._mu_eff
) * y_w
# Mean vector update (rank-μ + momentum update)
self._mean += self._cm * (
self._sigma * y_w + self._c1 / self._r / self._cmu * self._sigma * self._pc
)
# Covariance matrix adaption
rank_one = np.outer(self._pc, self._pc)
rank_mu = np.sum(
np.array([w * np.outer(y, y) for w, y in zip(self._weights, y_k)]), axis=0
)
self._C = (
(1 - self._c1 - self._cmu * np.sum(self._weights)) * self._C
+ self._c1 * rank_one
+ self._cmu * rank_mu
)
# Step-size control
norm_p_sigma = np.linalg.norm(self._p_sigma)
self._sigma *= np.exp((self._c_sigma / self._d_sigma) * (norm_p_sigma / self._chi_n - 1))
self._sigma = min(self._sigma, _SIGMA_MAX)
def should_stop(self) -> bool:
B, D = self._eigen_decomposition()
dC = np.diag(self._C)
# Stop if the range of function values of the recent generation is below tolfun.
if (
self.generation > self._funhist_term
and np.max(self._funhist_values) - np.min(self._funhist_values) < self._tolfun
):
return True
# Stop if the std of the normal distribution is smaller than tolx
# in all coordinates and pc is smaller than tolx in all components.
if np.all(self._sigma * dC < self._tolx) and np.all(self._sigma * self._pc < self._tolx):
return True
# Stop if detecting divergent behavior.
if self._sigma * np.max(D) > self._tolxup:
return True
# No effect coordinates: stop if adding 0.2-standard deviations
# in any single coordinate does not change m.
if np.any(self._mean == self._mean + (0.2 * self._sigma * np.sqrt(dC))):
return True
# No effect axis: stop if adding 0.1-standard deviation vector in
# any principal axis direction of C does not change m. "pycma" check
# axis one by one at each generation.
i = self.generation % self.dim
if np.all(self._mean == self._mean + (0.1 * self._sigma * D[i] * B[:, i])):
return True
# Stop if the condition number of the covariance matrix exceeds 1e14.
condition_cov = np.max(D) / np.min(D)
if condition_cov > self._tolconditioncov:
return True
return False
def _is_valid_bounds(bounds: Optional[np.ndarray], mean: np.ndarray) -> bool:
if bounds is None:
return True
if (mean.size, 2) != bounds.shape:
return False
if not np.all(bounds[:, 0] <= mean):
return False
if not np.all(mean <= bounds[:, 1]):
return False
return True
def _compress_symmetric(sym2d: np.ndarray) -> np.ndarray:
assert len(sym2d.shape) == 2 and sym2d.shape[0] == sym2d.shape[1]
n = sym2d.shape[0]
dim = (n * (n + 1)) // 2
sym1d = np.zeros(dim)
start = 0
for i in range(n):
sym1d[start : start + n - i] = sym2d[i][i:] # noqa: E203
start += n - i
return sym1d
def _decompress_symmetric(sym1d: np.ndarray) -> np.ndarray:
n = int(np.sqrt(sym1d.size * 2))
assert (n * (n + 1)) // 2 == sym1d.size
R, C = np.triu_indices(n)
out = np.zeros((n, n), dtype=sym1d.dtype)
out[R, C] = sym1d
out[C, R] = sym1d
return out
cmaes-0.13.1/cmaes/_sepcma.py000066400000000000000000000272031524175644700157600ustar00rootroot00000000000000from __future__ import annotations
import math
import numpy as np
from typing import Any
from typing import cast
from typing import Optional
_EPS = 1e-8
_MEAN_MAX = 1e32
_SIGMA_MAX = 1e32
class SepCMA:
"""Separable CMA-ES stochastic optimizer class with ask-and-tell interface.
Example:
.. code::
import numpy as np
from cmaes import SepCMA
def quadratic(x1, x2):
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
optimizer = SepCMA(mean=np.zeros(2), sigma=1.3)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x = optimizer.ask()
value = quadratic(x[0], x[1])
solutions.append((x, value))
print(f"#{generation} {value} (x1={x[0]}, x2 = {x[1]})")
# Tell evaluation values.
optimizer.tell(solutions)
Args:
mean:
Initial mean vector of multi-variate gaussian distributions.
sigma:
Initial standard deviation of covariance matrix.
bounds:
Lower and upper domain boundaries for each parameter (optional).
n_max_resampling:
A maximum number of resampling parameters (default: 100).
If all sampled parameters are infeasible, the last sampled one
will be clipped with lower and upper bounds.
seed:
A seed number (optional).
population_size:
A population size (optional).
"""
def __init__(
self,
mean: np.ndarray,
sigma: float,
bounds: Optional[np.ndarray] = None,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
):
assert sigma > 0, "sigma must be non-zero positive value"
assert np.all(np.abs(mean) < _MEAN_MAX), (
f"Abs of all elements of mean vector must be less than {_MEAN_MAX}"
)
n_dim = len(mean)
assert n_dim > 1, "The dimension of mean must be larger than 1"
if population_size is None:
population_size = 4 + math.floor(3 * math.log(n_dim)) # (eq. 48)
assert population_size > 0, "popsize must be non-zero positive value."
mu = population_size // 2
# (eq.49)
weights_prime = np.array([math.log(mu + 1) - math.log(i + 1) for i in range(mu)])
weights = weights_prime / sum(weights_prime)
mu_eff = 1 / sum(weights**2)
# learning rate for the rank-one update
alpha_cov = 2
c1 = alpha_cov / ((n_dim + 1.3) ** 2 + mu_eff)
# learning rate for the rank-μ update
cmu_full = 2 / mu_eff / ((n_dim + np.sqrt(2)) ** 2) + (1 - 1 / mu_eff) * min(
1, (2 * mu_eff - 1) / ((n_dim + 2) ** 2 + mu_eff)
)
cmu = (n_dim + 2) / 3 * cmu_full
cm = 1 # (eq. 54)
# learning rate for the cumulation for the step-size control
c_sigma = (mu_eff + 2) / (n_dim + mu_eff + 3)
d_sigma = 1 + 2 * max(0, math.sqrt((mu_eff - 1) / (n_dim + 1)) - 1) + c_sigma
assert c_sigma < 1, "invalid learning rate for cumulation for the step-size control"
# learning rate for cumulation for the rank-one update
cc = 4 / (n_dim + 4)
assert cc <= 1, "invalid learning rate for cumulation for the rank-one update"
self._n_dim = n_dim
self._popsize = population_size
self._mu = mu
self._mu_eff = mu_eff
self._cc = cc
self._c1 = c1
self._cmu = cmu
self._c_sigma = c_sigma
self._d_sigma = d_sigma
self._cm = cm
# E||N(0, I)|| (p.28)
self._chi_n = math.sqrt(self._n_dim) * (
1.0 - (1.0 / (4.0 * self._n_dim)) + 1.0 / (21.0 * (self._n_dim**2))
)
self._weights = weights
# evolution path
self._p_sigma = np.zeros(n_dim)
self._pc = np.zeros(n_dim)
self._mean = mean
self._sigma = sigma
self._D: Optional[np.ndarray] = None
self._C: np.ndarray = np.ones(n_dim)
# bounds contains low and high of each parameter.
assert bounds is None or _is_valid_bounds(bounds, mean), "invalid bounds"
self._bounds = bounds
self._n_max_resampling = n_max_resampling
self._g = 0
self._rng = np.random.RandomState(seed)
# Termination criteria
self._tolx = 1e-12 * sigma
self._tolxup = 1e4
self._tolfun = 1e-12
self._tolconditioncov = 1e14
self._funhist_term = 10 + math.ceil(30 * n_dim / population_size)
self._funhist_values = np.empty(self._funhist_term * 2)
@property
def dim(self) -> int:
"""A number of dimensions"""
return self._n_dim
@property
def population_size(self) -> int:
"""A population size"""
return self._popsize
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when multi-variate gaussian distribution is updated."""
return self._g
@property
def mean(self) -> np.ndarray:
"""Mean Vector"""
return self._mean
def reseed_rng(self, seed: int) -> None:
self._rng.seed(seed)
def __getstate__(self) -> dict[str, Any]:
attrs = {}
for name in self.__dict__:
# Remove _rng in pickle serialized object.
if name == "_rng":
continue
attrs[name] = getattr(self, name)
return attrs
def __setstate__(self, state: dict[str, Any]) -> None:
self.__dict__.update(state)
# Set _rng for unpickled object.
setattr(self, "_rng", np.random.RandomState())
def set_bounds(self, bounds: Optional[np.ndarray]) -> None:
"""Update boundary constraints"""
assert bounds is None or _is_valid_bounds(bounds, self._mean), "invalid bounds"
self._bounds = bounds
def ask(self) -> np.ndarray:
"""Sample a parameter"""
for i in range(self._n_max_resampling):
x = self._sample_solution()
if self._is_feasible(x):
return x
x = self._sample_solution()
x = self._repair_infeasible_params(x)
return x
def _eigen_decomposition(self) -> np.ndarray:
if self._D is not None:
return self._D
self._D = np.sqrt(np.where(self._C < 0, _EPS, self._C))
return self._D
def _sample_solution(self) -> np.ndarray:
D = self._eigen_decomposition()
z = self._rng.randn(self._n_dim) # ~ N(0, I)
y = D * z # ~ N(0, C)
x = self._mean + self._sigma * y # ~ N(m, σ^2 C)
return x
def _is_feasible(self, param: np.ndarray) -> bool:
if self._bounds is None:
return True
return cast(
bool,
np.all(param >= self._bounds[:, 0]) and np.all(param <= self._bounds[:, 1]),
) # Cast bool_ to bool
def _repair_infeasible_params(self, param: np.ndarray) -> np.ndarray:
if self._bounds is None:
return param
# clip with lower and upper bound.
param = np.where(param < self._bounds[:, 0], self._bounds[:, 0], param)
param = np.where(param > self._bounds[:, 1], self._bounds[:, 1], param)
return param
def tell(self, solutions: list[tuple[np.ndarray, float]]) -> None:
"""Tell evaluation values"""
assert len(solutions) == self._popsize, "Must tell popsize-length solutions."
for s in solutions:
assert np.all(np.abs(s[0]) < _MEAN_MAX), (
f"Abs of all param values must be less than {_MEAN_MAX} to avoid overflow errors"
)
self._g += 1
solutions.sort(key=lambda s: s[1])
# Stores 'best' and 'worst' values of the
# last 'self._funhist_term' generations.
funhist_idx = 2 * (self.generation % self._funhist_term)
self._funhist_values[funhist_idx] = solutions[0][1]
self._funhist_values[funhist_idx + 1] = solutions[-1][1]
# Sample new population of search_points, for k=1, ..., popsize
D = self._eigen_decomposition()
self._D = None
x_k = np.array([s[0] for s in solutions]) # ~ N(m, σ^2 C)
y_k = (x_k - self._mean) / self._sigma # ~ N(0, C)
# Selection and recombination
y_w = np.sum(y_k[: self._mu].T * self._weights[: self._mu], axis=1)
self._mean += self._cm * self._sigma * y_w
# Step-size control
self._p_sigma = (1 - self._c_sigma) * self._p_sigma + math.sqrt(
self._c_sigma * (2 - self._c_sigma) * self._mu_eff
) * (y_w / D)
norm_p_sigma = np.linalg.norm(self._p_sigma)
self._sigma *= np.exp((self._c_sigma / self._d_sigma) * (norm_p_sigma / self._chi_n - 1))
self._sigma = min(self._sigma, _SIGMA_MAX)
# Covariance matrix adaption
h_sigma_cond_left = norm_p_sigma / math.sqrt(
1 - (1 - self._c_sigma) ** (2 * (self._g + 1))
)
h_sigma_cond_right = (1.4 + 2 / (self._n_dim + 1)) * self._chi_n
h_sigma = 1.0 if h_sigma_cond_left < h_sigma_cond_right else 0.0 # (p.28)
# (eq.45)
self._pc = (1 - self._cc) * self._pc + h_sigma * math.sqrt(
self._cc * (2 - self._cc) * self._mu_eff
) * y_w
delta_h_sigma = (1 - h_sigma) * self._cc * (2 - self._cc) # (p.28)
assert delta_h_sigma <= 1
# (eq.47)
rank_one = self._pc**2
rank_mu = np.sum(np.array([w * (y**2) for w, y in zip(self._weights, y_k)]), axis=0)
self._C = (
(1 + self._c1 * delta_h_sigma - self._c1 - self._cmu * np.sum(self._weights)) * self._C
+ self._c1 * rank_one
+ self._cmu * rank_mu
)
def should_stop(self) -> bool:
D = self._eigen_decomposition()
# Stop if the range of function values of the recent generation is below tolfun.
if (
self.generation > self._funhist_term
and np.max(self._funhist_values) - np.min(self._funhist_values) < self._tolfun
):
return True
# Stop if the std of the normal distribution is smaller than tolx
# in all coordinates and pc is smaller than tolx in all components.
if np.all(self._sigma * self._C < self._tolx) and np.all(
self._sigma * self._pc < self._tolx
):
return True
# Stop if detecting divergent behavior.
if self._sigma * np.max(D) > self._tolxup:
return True
# No effect coordinates: stop if adding 0.2-standard deviations
# in any single coordinate does not change m.
if np.any(self._mean == self._mean + (0.2 * self._sigma * np.sqrt(self._C))):
return True
# No effect axis: stop if adding 0.1-standard deviation vector in
# any principal axis direction of C does not change m. "pycma" check
# axis one by one at each generation.
i = self.generation % self.dim
if np.all(self._mean == self._mean + (0.1 * self._sigma * D[i] * np.ones(self._n_dim))):
return True
# Stop if the condition number of the covariance matrix exceeds 1e14.
condition_cov = np.max(D) / np.min(D)
if condition_cov > self._tolconditioncov:
return True
return False
def _is_valid_bounds(bounds: Optional[np.ndarray], mean: np.ndarray) -> bool:
if bounds is None:
return True
if (mean.size, 2) != bounds.shape:
return False
if not np.all(bounds[:, 0] <= mean):
return False
if not np.all(mean <= bounds[:, 1]):
return False
return True
cmaes-0.13.1/cmaes/_stats.py000066400000000000000000000017511524175644700156460ustar00rootroot00000000000000import math
import numpy as np
@np.vectorize
def norm_cdf(x: float, loc: float = 0.0, scale: float = 1.0) -> float:
x = (x - loc) / scale
x = x / 2**0.5
z = abs(x)
if z < 1 / 2**0.5:
y = 0.5 + 0.5 * math.erf(x)
else:
y = 0.5 * math.erfc(z)
if x > 0:
y = 1.0 - y
return y
@np.vectorize
def chi2_ppf(q: float) -> float:
"""
only deal with the special case df=1, loc=0, scale=1
solve chi2.cdf(x; df=1) = erf(sqrt(x/2)) = q with bisection method
"""
if q == 0:
return 0.0
if q == 1:
return math.inf
a, b = 0.0, 100.0
if q < 0.9:
for _ in range(100):
m = (a + b) / 2
if math.erf(math.sqrt(m / 2)) < q:
a = m
else:
b = m
else:
for _ in range(100):
m = (a + b) / 2
if math.erfc(math.sqrt(m / 2)) > 1.0 - q:
a = m
else:
b = m
return m
cmaes-0.13.1/cmaes/_uhvi_archiving.py000066400000000000000000000156271524175644700175240ustar00rootroot00000000000000"""
_uhvi_archiving.py
This module implements the UHVI (uncrowded hypervolume improvement) evaluation.
Parts of this implementation are adapted from the `moarchiving` library.
Source: https://github.com/CMA-ES/moarchiving/blob/development/moarchiving/moarchiving.py
-------------------------------------------------------------------------------
ORIGINAL LICENSE FOR moarchiving:
The BSD 3-Clause License
Copyright (c) 2018-2025 Inria
Authors: Nikolaus Hansen, Nace Sever, Mila Nedić, Tea Tušar
Redistribution and use in source and binary forms, with or without
modification, are permitted provided that the following conditions
are met:
1. Redistributions of source code must retain the above copyright and
authors notice, this list of conditions and the following disclaimer.
2. Redistributions in binary form must reproduce the above copyright
and authors notice, this list of conditions and the following
disclaimer in the documentation and/or other materials provided with
the distribution.
3. Neither the name of the copyright holder nor the names of its
contributors nor the authors names may be used to endorse or promote
products derived from this software without specific prior written
permission.
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
AUTHORS OR CONTRIBUTORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES
OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE,
ARISING FROM, OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER
DEALINGS IN THE SOFTWARE.
-------------------------------------------------------------------------------
"""
from __future__ import annotations
import numpy as np
from math import sqrt
from bisect import bisect_left
from typing import List, Tuple
Point2D = Tuple[float, float]
class UHVIArchive2D:
"""
Minimal 2D archive to evaluate Uncrowded Hypervolume Improvement (UHVI).
This class maintains a lexicographically sorted Pareto front and computes
the improvement a new point brings to the hypervolume.
"""
def __init__(self, list_of_f_pairs: np.ndarray) -> None:
"""
Initialize the archive and perform non-dominated sorting.
Args:
list_of_f_pairs: Initial set of objective pairs (e.g., [[f1, f2], ...]).
"""
pts: List[Point2D] = [(float(p[0]), float(p[1])) for p in list_of_f_pairs]
pts.sort()
front: List[Point2D] = []
best_f2 = float("inf")
for f1, f2 in pts:
if f2 < best_f2:
front.append((f1, f2))
best_f2 = f2
self.front: List[Point2D] = front
@staticmethod
def _to_point(x: np.ndarray) -> Point2D:
return (float(x[0]), float(x[1]))
@staticmethod
def _dominates(p1: Point2D, p2: Point2D) -> bool:
"""Check if p1 weakly Pareto-dominates p2."""
return p1[0] <= p2[0] and p1[1] <= p2[1]
@staticmethod
def _in_domain(p: Point2D, r: Point2D) -> bool:
"""Check if the point is within the reference domain."""
return p[0] < r[0] and p[1] < r[1]
def _dominated_or_equal_by_front(self, p: Point2D) -> bool:
if not self.front:
return False
i = bisect_left(self.front, p)
if i > 0 and self._dominates(self.front[i - 1], p):
return True
if i < len(self.front) and self._dominates(self.front[i], p):
return True
return False
def _distance_to_pareto_front(self, p: Point2D, r: Point2D) -> float:
"""
Compute Euclidean distance to the empirical non-domination front.
If the point is non-dominated and in-domain, distance is 0.0.
"""
if self._in_domain(p, r) and not self._dominated_or_equal_by_front(p):
return 0.0
ref_d0 = max(0.0, p[0] - r[0])
ref_d1 = max(0.0, p[1] - r[1])
if not self.front:
return sqrt(ref_d0 * ref_d0 + ref_d1 * ref_d1)
# Distances to the two outer kink points (use one coordinate of the reference point).
best_sq = min(
max(0.0, p[0] - self.front[0][0]) ** 2 + ref_d1**2,
ref_d0**2 + max(0.0, p[1] - self.front[-1][1]) ** 2,
)
if len(self.front) == 1:
return sqrt(best_sq)
start = bisect_left(self.front, p)
# inner kink points: (front[idx].f1, front[idx-1].f2)
for idx in range(start, 0, -1):
if idx == len(self.front):
continue
right = self.front[idx]
left = self.front[idx - 1]
sq = max(0.0, p[0] - right[0]) ** 2 + max(0.0, p[1] - left[1]) ** 2
if sq < best_sq:
best_sq = sq
if right[1] >= p[1] or idx == 1:
break
return sqrt(best_sq)
@staticmethod
def _hypervolume_2d(sub: List[Point2D], ref: Point2D) -> float:
"""
Hypervolume of a 2D non-dominated sorted list (minimization) w.r.t. `ref`.
"""
r0, r1 = ref
hv = 0.0
i = 0
while i < len(sub) and not (sub[i][0] < r0 and sub[i][1] < r1):
i += 1
if i < len(sub):
hv += (r0 - sub[i][0]) * (r1 - sub[i][1])
i += 1
while i < len(sub) and (sub[i][0] < r0 and sub[i][1] < r1):
hv += (r0 - sub[i][0]) * (sub[i - 1][1] - sub[i][1])
i += 1
return hv
def uhvi(self, s: np.ndarray, r: np.ndarray) -> float:
"""
Compute the Uncrowded Hypervolume Improvement (UHVI).
Args:
s: The objective pair to evaluate.
r: The reference point for hypervolume calculation.
Returns:
float: Positive value for HVI, negative for distance to the front.
"""
sp = self._to_point(s)
rp = self._to_point(r)
# Exact match on the current front -> zero improvement.
for p in self.front:
if p == sp:
return 0.0
dist = self._distance_to_pareto_front(sp, rp)
if dist > 0.0:
return -dist
# Non-dominated and in the reference domain -> hypervolume improvement (HVI).
i0 = bisect_left(self.front, sp)
i1 = i0
while i1 < len(self.front) and sp[1] <= self.front[i1][1]:
i1 += 1
# Reference point for the local sub-front used in local HVI computation.
r0 = self.front[i1][0] if i1 < len(self.front) else rp[0]
r1 = self.front[i0 - 1][1] if i0 > 0 else rp[1]
local_ref: Point2D = (r0, r1)
sub = self.front[i0:i1]
hv0 = self._hypervolume_2d(sub, local_ref)
# Since s dominates the extracted sublist, the local hypervolume after insertion
# is the rectangle area between s and the local reference point.
hv1 = (r0 - sp[0]) * (r1 - sp[1])
return hv1 - hv0
cmaes-0.13.1/cmaes/_warm_start.py000066400000000000000000000046631524175644700167000ustar00rootroot00000000000000from __future__ import annotations
import math
import numpy as np
def get_warm_start_mgd(
source_solutions: list[tuple[np.ndarray, float]],
gamma: float = 0.1,
alpha: float = 0.1,
) -> tuple[np.ndarray, float, np.ndarray]:
"""Estimates a promising distribution of the source task, then
returns a multivariate gaussian distribution (the mean vector
and the covariance matrix) used for initialization of the CMA-ES.
Args:
source_solutions:
List of solutions (parameter, value) on a source task.
gamma:
top-(gamma x 100)% solutions are selected from a set of solutions
on a source task. (default: 0.1).
alpha:
prior parameter for the initial covariance matrix (default: 0.1).
Returns:
The tuple of mean vector, sigma, and covariance matrix.
"""
# Paper: https://arxiv.org/abs/2012.06932
assert 0 < gamma <= 1, "gamma should be in (0, 1]"
if len(source_solutions) == 0:
raise ValueError("solutions should contain one or more items.")
# Select top-(gamma x 100)% solutions
source_solutions = sorted(source_solutions, key=lambda t: t[1])
gamma_n = math.floor(len(source_solutions) * gamma)
assert gamma_n >= 1, "One or more solutions must be selected from a source task"
dim = len(source_solutions[0][0])
top_gamma_solutions = np.empty(
shape=(
gamma_n,
dim,
),
dtype=float,
)
for i in range(gamma_n):
top_gamma_solutions[i] = source_solutions[i][0]
# Estimation of a Promising Distribution of a Source Task.
first_term = alpha**2 * np.eye(dim)
cov_term = np.zeros(shape=(dim, dim), dtype=float)
for i in range(gamma_n):
cov_term += np.dot(
top_gamma_solutions[i, :].reshape(dim, 1),
top_gamma_solutions[i, :].reshape(dim, 1).T,
)
second_term = cov_term / gamma_n
mean_term = np.zeros(
shape=(
dim,
1,
),
dtype=float,
)
for i in range(gamma_n):
mean_term += top_gamma_solutions[i, :].reshape(dim, 1)
mean_term /= gamma_n
third_term = np.dot(mean_term, mean_term.T)
mu = mean_term
mean = mu[:, 0]
Sigma = first_term + second_term - third_term
det_sigma = np.linalg.det(Sigma)
sigma = math.pow(det_sigma, 1.0 / 2.0 / dim)
cov = Sigma / math.pow(det_sigma, 1.0 / dim)
return mean, sigma, cov
cmaes-0.13.1/cmaes/_xnes.py000066400000000000000000000213541524175644700154660ustar00rootroot00000000000000from __future__ import annotations
import math
import numpy as np
from typing import cast
from typing import Optional
_EPS = 1e-8
_MEAN_MAX = 1e32
_SIGMA_MAX = 1e32
class XNES:
"""xNES stochastic optimizer class with ask-and-tell interface.
Example:
.. code::
import numpy as np
from cmaes import XNES
def quadratic(x1, x2):
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
optimizer = XNES(mean=np.zeros(2), sigma=1.3)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x = optimizer.ask()
value = quadratic(x[0], x[1])
solutions.append((x, value))
print(f"#{generation} {value} (x1={x[0]}, x2 = {x[1]})")
# Tell evaluation values.
optimizer.tell(solutions)
Args:
mean:
Initial mean vector of multi-variate gaussian distributions.
sigma:
Initial standard deviation of covariance matrix.
bounds:
Lower and upper domain boundaries for each parameter (optional).
n_max_resampling:
A maximum number of resampling parameters (default: 100).
If all sampled parameters are infeasible, the last sampled one
will be clipped with lower and upper bounds.
seed:
A seed number (optional).
population_size:
A population size (optional).
"""
# Paper: https://dl.acm.org/doi/10.1145/1830483.1830557
def __init__(
self,
mean: np.ndarray,
sigma: float,
bounds: Optional[np.ndarray] = None,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
):
assert sigma > 0, "sigma must be non-zero positive value"
assert np.all(np.abs(mean) < _MEAN_MAX), (
f"Abs of all elements of mean vector must be less than {_MEAN_MAX}"
)
n_dim = len(mean)
assert n_dim > 1, "The dimension of mean must be larger than 1"
if population_size is None:
population_size = 4 + math.floor(3 * math.log(n_dim))
assert population_size > 0, "popsize must be non-zero positive value."
w_hat = np.log(population_size / 2 + 1) - np.log(np.arange(1, population_size + 1))
w_hat[np.where(w_hat < 0)] = 0
weights = w_hat / sum(w_hat) - (1.0 / population_size)
self._n_dim = n_dim
self._popsize = population_size
# weights
self._weights = weights
# learning rate
self._eta_mean = 1.0
self._eta_sigma = (3 / 5) * (3 + math.log(n_dim)) / (n_dim * math.sqrt(n_dim))
self._eta_B = self._eta_sigma
# distribution parameter
self._mean = mean.copy()
self._sigma = sigma
self._B = np.eye(n_dim)
# bounds contains low and high of each parameter.
assert bounds is None or _is_valid_bounds(bounds, mean), "invalid bounds"
self._bounds = bounds
self._n_max_resampling = n_max_resampling
self._g = 0
self._rng = np.random.RandomState(seed)
# Termination criteria
self._tolx = 1e-12 * sigma
self._tolxup = 1e4
self._tolfun = 1e-12
self._tolconditioncov = 1e14
self._funhist_term = 10 + math.ceil(30 * n_dim / population_size)
self._funhist_values = np.empty(self._funhist_term * 2)
@property
def dim(self) -> int:
"""A number of dimensions"""
return self._n_dim
@property
def population_size(self) -> int:
"""A population size"""
return self._popsize
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when multi-variate gaussian distribution is updated."""
return self._g
def reseed_rng(self, seed: int) -> None:
self._rng.seed(seed)
def set_bounds(self, bounds: Optional[np.ndarray]) -> None:
"""Update boundary constraints"""
assert bounds is None or _is_valid_bounds(bounds, self._mean), "invalid bounds"
self._bounds = bounds
def ask(self) -> np.ndarray:
"""Sample a parameter"""
for i in range(self._n_max_resampling):
x = self._sample_solution()
if self._is_feasible(x):
return x
x = self._sample_solution()
x = self._repair_infeasible_params(x)
return x
def _sample_solution(self) -> np.ndarray:
z = self._rng.randn(self._n_dim) # ~ N(0, I)
x = self._mean + self._sigma * self._B.dot(z) # ~ N(m, σ^2 B B^T)
return x
def _is_feasible(self, param: np.ndarray) -> bool:
if self._bounds is None:
return True
return cast(
bool,
np.all(param >= self._bounds[:, 0]) and np.all(param <= self._bounds[:, 1]),
) # Cast bool_ to bool.
def _repair_infeasible_params(self, param: np.ndarray) -> np.ndarray:
if self._bounds is None:
return param
# clip with lower and upper bound.
param = np.where(param < self._bounds[:, 0], self._bounds[:, 0], param)
param = np.where(param > self._bounds[:, 1], self._bounds[:, 1], param)
return param
def tell(self, solutions: list[tuple[np.ndarray, float]]) -> None:
"""Tell evaluation values"""
assert len(solutions) == self._popsize, "Must tell popsize-length solutions."
for s in solutions:
assert np.all(np.abs(s[0]) < _MEAN_MAX), (
f"Abs of all param values must be less than {_MEAN_MAX} to avoid overflow errors"
)
self._g += 1
solutions.sort(key=lambda s: s[1])
# Stores 'best' and 'worst' values of the
# last 'self._funhist_term' generations.
funhist_idx = 2 * (self.generation % self._funhist_term)
self._funhist_values[funhist_idx] = solutions[0][1]
self._funhist_values[funhist_idx + 1] = solutions[-1][1]
z_k = np.array(
[np.linalg.inv(self._sigma * self._B).dot(s[0] - self._mean) for s in solutions]
)
# natural gradient estimation in local coordinate
G_delta = np.sum(
[self._weights[i] * z_k[i, :] for i in range(self.population_size)], axis=0
)
G_M = np.sum(
[
self._weights[i] * (np.outer(z_k[i, :], z_k[i, :]) - np.eye(self._n_dim))
for i in range(self.population_size)
],
axis=0,
)
G_sigma = G_M.trace() / self._n_dim
G_B = G_M - G_sigma * np.eye(self._n_dim)
# parameter update
self._mean += self._eta_mean * self._sigma * np.dot(self._B, G_delta)
self._sigma *= math.exp((self._eta_sigma / 2.0) * G_sigma)
self._B = self._B.dot(_expm((self._eta_B / 2.0) * G_B))
def should_stop(self) -> bool:
A = self._B.dot(self._B.T)
A = (A + A.T) / 2
E2, V = np.linalg.eigh(A)
E = np.sqrt(np.where(E2 < 0, _EPS, E2))
diagA = np.diag(A)
# Stop if the range of function values of the recent generation is below tolfun.
if (
self.generation > self._funhist_term
and np.max(self._funhist_values) - np.min(self._funhist_values) < self._tolfun
):
return True
# Stop if detecting divergent behavior.
if self._sigma * np.max(E) > self._tolxup:
return True
# No effect coordinates: stop if adding 0.2-standard deviations
# in any single coordinate does not change m.
if np.any(self._mean == self._mean + (0.2 * self._sigma * np.sqrt(diagA))):
return True
# No effect axis: stop if adding 0.1-standard deviation vector in
# any principal axis direction of C does not change m. "pycma" check
# axis one by one at each generation.
i = self.generation % self.dim
if np.all(self._mean == self._mean + (0.1 * self._sigma * E[i] * V[:, i])):
return True
# Stop if the condition number of the covariance matrix exceeds 1e14.
condition_cov = np.max(E) / np.min(E)
if condition_cov > self._tolconditioncov:
return True
return False
def _is_valid_bounds(bounds: Optional[np.ndarray], mean: np.ndarray) -> bool:
if bounds is None:
return True
if (mean.size, 2) != bounds.shape:
return False
if not np.all(bounds[:, 0] <= mean):
return False
if not np.all(mean <= bounds[:, 1]):
return False
return True
def _expm(mat: np.ndarray) -> np.ndarray:
D, U = np.linalg.eigh(mat)
expD = np.exp(D)
return U @ np.diag(expD) @ U.T
cmaes-0.13.1/cmaes/cma.py000066400000000000000000000003231524175644700151030ustar00rootroot00000000000000import warnings
from ._cma import CMA
__all__ = ["CMA"]
warnings.warn(
"This module is deprecated. Please import CMA class from the "
"package root (ex: from cmaes import CMA).",
FutureWarning,
)
cmaes-0.13.1/cmaes/cmasop.py000066400000000000000000000523501524175644700156340ustar00rootroot00000000000000from __future__ import annotations
import math
import numpy as np
from typing import Any
from typing import cast
from typing import Optional
from scipy.spatial import Voronoi
from scipy.stats import chi2
from scipy.stats import norm
_EPS = 1e-8
_MEAN_MAX = 1e32
_SIGMA_MAX = 1e32
class CMASoP:
"""CMA-ES-SoP stochastic optimizer class with ask-and-tell interface.
Example:
.. code::
import numpy as np
from cmaes.cma_sop import CMASoP
# numbers of dimensions in each subspace
subspace_dim_list = [2, 3, 5]
cont_dim = 10
# numbers of points in each subspace
point_num_list = [10, 20, 40]
# number of total dimensions
dim = int(np.sum(subspace_dim_list) + cont_dim)
# objective function
def quadratic(x):
coef = 1000 ** (np.arange(dim) / float(dim - 1))
return np.sum(x ** 2)
# sets_of_points (on [-5, 5])
subspace_num = len(subspace_dim_list)
sets_of_points = [(
2 * np.random.rand(point_num_list[i], subspace_dim_list[i]) - 1) * 5
for i in range(subspace_num)]
# the optimal solution is contained
for i in range(subspace_num):
sets_of_points[i][-1] = np.zeros(subspace_dim_list[i])
np.random.shuffle(sets_of_points[i])
# optimizer (CMA-ES-SoP)
optimizer = CMASoP(
sets_of_points=sets_of_points,
mean=np.random.rand(dim) * 4 + 1,
sigma=2.0,
)
best_eval = np.inf
eval_count = 0
for generation in range(400):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x, enc_x = optimizer.ask()
value = quadratic(enc_x)
# save best eval
best_eval = np.min((best_eval, value))
eval_count += 1
solutions.append((x, value))
# Tell evaluation values.
optimizer.tell(solutions)
print(f"#{generation} ({best_eval} {eval_count})")
if best_eval < 1e-4 or optimizer.should_stop():
break
Args:
sets_of_points:
List of points for each subspace.
mean:
Initial mean vector of multi-variate gaussian distributions.
sigma:
Initial standard deviation of covariance matrix.
bounds:
Lower and upper domain boundaries for each parameter (optional).
n_max_resampling:
A maximum number of resampling parameters (default: 100).
If all sampled parameters are infeasible, the last sampled one
will be clipped with lower and upper bounds.
seed:
A seed number (optional).
population_size:
A population size (optional).
cov:
A covariance matrix (optional).
margin:
A margin parameter (optional).
"""
# Paper: https://arxiv.org/abs/2408.13046
def __init__(
self,
sets_of_points: np.ndarray,
mean: np.ndarray,
sigma: float,
bounds: Optional[np.ndarray] = None,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
cov: Optional[np.ndarray] = None,
margin: Optional[float] = None,
):
# same initialization procedure as for naive cma
self._naive_cma_init_(
mean,
sigma,
bounds,
n_max_resampling,
seed,
population_size,
cov,
)
# preprocess of sets of points
if sets_of_points is not None:
self._sets_of_points = sets_of_points
self._zd = [ds.shape[1] for ds in sets_of_points]
self._point_num = [ds.shape[0] for ds in sets_of_points]
self._vor_list = [Voronoi(ds) for ds in sets_of_points]
self._subspace_mask = None
self._neighbor_matrices = self._get_neighbor_matrices()
else:
self._zd = []
# setting for margin correction and adaptation
self._margin_target = margin if margin is not None else 1 / (self._n_dim * self._popsize)
self._margin = self._margin_target * np.ones_like(self._zd)
self._margin_coeff = 1 + 1 / self._n_dim if self._margin_target > 0 else 0
def _naive_cma_init_(
self,
mean: np.ndarray,
sigma: float,
bounds: Optional[np.ndarray] = None,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
cov: Optional[np.ndarray] = None,
) -> None:
assert sigma > 0, "sigma must be non-zero positive value"
assert np.all(np.abs(mean) < _MEAN_MAX), (
f"Abs of all elements of mean vector must be less than {_MEAN_MAX}"
)
n_dim = len(mean)
assert n_dim > 0, "The dimension of mean must be positive"
if population_size is None:
population_size = 4 + math.floor(3 * math.log(n_dim))
assert population_size > 0, "popsize must be non-zero positive value."
mu = population_size // 2
weights_prime = np.array(
[math.log((population_size + 1) / 2) - math.log(i + 1) for i in range(population_size)]
)
weights_prime[weights_prime < 0] = 0
weights = weights_prime / weights_prime.sum()
mu_eff = (np.sum(weights_prime[:mu]) ** 2) / np.sum(weights_prime[:mu] ** 2)
# learning rate for the rank-one update
alpha_cov = 2
c1 = alpha_cov / ((n_dim + 1.3) ** 2 + mu_eff)
# learning rate for the rank-μ update
cmu = min(
1 - c1 - 1e-8, # 1e-8 is for large popsize.
alpha_cov * (mu_eff - 2 + 1 / mu_eff) / ((n_dim + 2) ** 2 + alpha_cov * mu_eff / 2),
)
assert c1 <= 1 - cmu, "invalid learning rate for the rank-one update"
assert cmu <= 1 - c1, "invalid learning rate for the rank-μ update"
cm = 1
# learning rate for the cumulation for the step-size control
c_sigma = (mu_eff + 2) / (n_dim + mu_eff + 5)
d_sigma = 1 + 2 * max(0, math.sqrt((mu_eff - 1) / (n_dim + 1)) - 1) + c_sigma
assert c_sigma < 1, "invalid learning rate for cumulation for the step-size control"
# learning rate for cumulation for the rank-one update
cc = (4 + mu_eff / n_dim) / (n_dim + 4 + 2 * mu_eff / n_dim)
assert cc <= 1, "invalid learning rate for cumulation for the rank-one update"
self._n_dim = n_dim
self._popsize = population_size
self._mu = mu
self._mu_eff = mu_eff
self._cc = cc
self._c1 = c1
self._cmu = cmu
self._c_sigma = c_sigma
self._d_sigma = d_sigma
self._cm = cm
# E||N(0, I)||
self._chi_n = math.sqrt(self._n_dim) * (
1.0 - (1.0 / (4.0 * self._n_dim)) + 1.0 / (21.0 * (self._n_dim**2))
)
self._weights = weights
# evolution path
self._p_sigma = np.zeros(n_dim)
self._pc = np.zeros(n_dim)
self._mean = mean.copy()
if cov is None:
self._C = np.eye(n_dim)
else:
assert cov.shape == (n_dim, n_dim), "Invalid shape of covariance matrix"
self._C = cov
self._sigma = sigma
self._D: Optional[np.ndarray] = None
self._B: Optional[np.ndarray] = None
# bounds contains low and high of each parameter.
assert bounds is None or _is_valid_bounds(bounds, mean), "invalid bounds"
self._bounds = bounds
self._n_max_resampling = n_max_resampling
self._g = 0
self._rng = np.random.RandomState(seed)
# Termination criteria
self._tolx = 1e-12 * sigma
self._tolxup = 1e4
self._tolfun = 1e-12
self._tolconditioncov = 1e14
self._funhist_term = 10 + math.ceil(30 * n_dim / population_size)
self._funhist_values = np.empty(self._funhist_term * 2)
def _get_neighbor_matrices(self) -> list:
try:
# if already computed
return self._neighbor_matrices
except AttributeError:
def neighbor_matrix(i: int) -> np.ndarray:
point_num = self._point_num[i]
ridge_points = self._vor_list[i].ridge_points
res = np.zeros((point_num, point_num), dtype=bool)
res[ridge_points[:, 0], ridge_points[:, 1]] = True
return res | res.T
# compute neighboring points
self._neighbor_matrices = [
neighbor_matrix(i) for i in range(len(self._sets_of_points))
]
return self._neighbor_matrices
def __getstate__(self) -> dict[str, Any]:
attrs = {}
for name in self.__dict__:
# Remove _rng in pickle serialized object.
if name == "_rng":
continue
if name == "_C":
sym1d = _compress_symmetric(self._C)
attrs["_c_1d"] = sym1d
continue
attrs[name] = getattr(self, name)
return attrs
def __setstate__(self, state: dict[str, Any]) -> None:
state["_C"] = _decompress_symmetric(state["_c_1d"])
del state["_c_1d"]
self.__dict__.update(state)
# Set _rng for unpickled object.
setattr(self, "_rng", np.random.RandomState())
@property
def dim(self) -> int:
"""A number of dimensions"""
return self._n_dim
@property
def population_size(self) -> int:
"""A population size"""
return self._popsize
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when multi-variate gaussian distribution is updated."""
return self._g
@property
def mean(self) -> np.ndarray:
"""Mean Vector"""
return self._mean
def reseed_rng(self, seed: int) -> None:
self._rng.seed(seed)
def set_bounds(self, bounds: Optional[np.ndarray]) -> None:
"""Update boundary constraints"""
assert bounds is None or _is_valid_bounds(bounds, self._mean), "invalid bounds"
self._bounds = bounds
def ask(self) -> tuple[np.ndarray, np.ndarray]:
"""Sample a parameter"""
for i in range(self._n_max_resampling):
x = self._sample_solution()
if self._is_feasible(x):
enc_x = self._encoding(x) # eoncoded solution
return x, enc_x
x = self._sample_solution()
x = self._repair_infeasible_params(x)
enc_x = self._encoding(x) # eoncoded solution
return x, enc_x
def _eigen_decomposition(self) -> tuple[np.ndarray, np.ndarray]:
if self._B is not None and self._D is not None:
return self._B, self._D
self._C = (self._C + self._C.T) / 2
D2, B = np.linalg.eigh(self._C)
D = np.sqrt(np.where(D2 < 0, _EPS, D2))
self._C = np.dot(np.dot(B, np.diag(D**2)), B.T)
self._B, self._D = B, D
return B, D
def _sample_solution(self) -> np.ndarray:
B, D = self._eigen_decomposition()
z = self._rng.randn(self._n_dim) # ~ N(0, I)
y = cast(np.ndarray, B.dot(np.diag(D))).dot(z) # ~ N(0, C)
x = self._mean + self._sigma * y # ~ N(m, σ^2 C)
return x
def _is_feasible(self, param: np.ndarray) -> bool:
if self._bounds is None:
return True
return cast(
bool,
np.all(param >= self._bounds[:, 0]) and np.all(param <= self._bounds[:, 1]),
) # Cast bool_ to bool.
def _repair_infeasible_params(self, param: np.ndarray) -> np.ndarray:
if self._bounds is None:
return param
# clip with lower and upper bound.
param = np.where(param < self._bounds[:, 0], self._bounds[:, 0], param)
param = np.where(param > self._bounds[:, 1], self._bounds[:, 1], param)
return param
def _encoding(self, X: np.ndarray) -> np.ndarray:
X_ndim = X.ndim
X = np.atleast_2d(X)
num_cont = self._n_dim - np.sum(self._zd) # = N_continuous
if num_cont == self._n_dim:
return X
# encoding
closest_idx = self._get_closest_point_index(X)
X_z_enc = np.hstack(
[self._sets_of_points[i][closest_idx[i]] for i in range(len(self._zd))]
)
if X_ndim == 1:
return np.hstack((X[:, :num_cont], X_z_enc))[0]
else:
return np.hstack((X[:, :num_cont], X_z_enc))
def _get_closest_point_index(self, X: np.ndarray) -> list[Any]:
X = np.atleast_2d(X)
# return the closest point in i-th subspace
def get_closest(i: int) -> np.ndarray:
X_z = X[:, self._get_subspace_mask()[i]]
vor = self._vor_list[i]
dist2 = ((X_z[:, None, :] - vor.points[None, :, :]) ** 2).sum(axis=2)
return np.argmin(dist2, axis=1)
return [get_closest(i) for i in range(len(self._zd))]
def _get_subspace_mask(self) -> np.ndarray:
if self._subspace_mask is not None:
return self._subspace_mask
else:
self._subspace_mask = np.zeros((len(self._zd), self._n_dim), dtype=bool)
cont_dim = self._n_dim - np.sum(self._zd)
subspace_range = np.concatenate([[cont_dim], cont_dim + np.cumsum(self._zd)])
for i in range(len(self._zd)):
self._subspace_mask[i, subspace_range[i] : subspace_range[i + 1]] = True
return self._subspace_mask
def tell(self, solutions: list[tuple[np.ndarray, float]]) -> None:
"""Tell evaluation values"""
self._naive_cma_update(solutions)
# margin correction (if self.margin = 0, this behaves as CMA-ES)
if np.sum(self._zd) > 0 and self._margin_target > 0:
self._margin_correction()
def _naive_cma_update(self, solutions: list[tuple[np.ndarray, float]]) -> None:
assert len(solutions) == self._popsize, "Must tell popsize-length solutions."
for s in solutions:
assert np.all(np.abs(s[0]) < _MEAN_MAX), (
f"Abs of all param values must be less than {_MEAN_MAX} to avoid overflow errors"
)
self._g += 1
solutions.sort(key=lambda s: s[1])
# Stores 'best' and 'worst' values of the
# last 'self._funhist_term' generations.
funhist_idx = 2 * (self.generation % self._funhist_term)
self._funhist_values[funhist_idx] = solutions[0][1]
self._funhist_values[funhist_idx + 1] = solutions[-1][1]
# Sample new population of search_points, for k=1, ..., popsize
B, D = self._eigen_decomposition()
self._B, self._D = None, None
x_k = np.array([s[0] for s in solutions]) # ~ N(m, σ^2 C)
y_k = (x_k - self._mean) / self._sigma # ~ N(0, C)
# Selection and recombination
y_w = np.sum(y_k[: self._mu].T * self._weights[: self._mu], axis=1)
self._mean += self._cm * self._sigma * y_w
# Step-size control
C_2 = cast(
np.ndarray, cast(np.ndarray, B.dot(np.diag(1 / D))).dot(B.T)
) # C^(-1/2) = B D^(-1) B^T
self._p_sigma = (1 - self._c_sigma) * self._p_sigma + math.sqrt(
self._c_sigma * (2 - self._c_sigma) * self._mu_eff
) * C_2.dot(y_w)
norm_p_sigma = np.linalg.norm(self._p_sigma)
self._sigma *= np.exp((self._c_sigma / self._d_sigma) * (norm_p_sigma / self._chi_n - 1))
self._sigma = min(self._sigma, _SIGMA_MAX)
# Covariance matrix adaption
h_sigma_cond_left = norm_p_sigma / math.sqrt(
1 - (1 - self._c_sigma) ** (2 * (self._g + 1))
)
h_sigma_cond_right = (1.4 + 2 / (self._n_dim + 1)) * self._chi_n
h_sigma = 1.0 if h_sigma_cond_left < h_sigma_cond_right else 0.0
self._pc = (1 - self._cc) * self._pc + h_sigma * math.sqrt(
self._cc * (2 - self._cc) * self._mu_eff
) * y_w
delta_h_sigma = (1 - h_sigma) * self._cc * (2 - self._cc)
assert delta_h_sigma <= 1
rank_one = np.outer(self._pc, self._pc)
rank_mu = np.sum(
np.array([w * np.outer(y, y) for w, y in zip(self._weights, y_k)]), axis=0
)
self._C = (
(1 + self._c1 * delta_h_sigma - self._c1 - self._cmu * np.sum(self._weights)) * self._C
+ self._c1 * rank_one
+ self._cmu * rank_mu
)
def _get_neighbor_indexes(self, m: np.ndarray) -> list[Any]:
# get neiboring points to given point
closest_index = np.array(self._get_closest_point_index(m))[:, 0]
return [self._get_neighbor_matrices()[i][closest_index[i]] for i in range(len(self._zd))]
def _margin_correction(self) -> None:
nearest_indexes = self._get_neighbor_indexes(self._mean)
for i in range(len(self._zd)):
# margin correction (eq. (10)-(15))
CI = np.sqrt(chi2.ppf(q=1.0 - self._margin[i], df=1))
target_nearest_points = self._sets_of_points[i][nearest_indexes[i]]
m_z = self._mean[self._get_subspace_mask()[i]]
if len(target_nearest_points) == 0:
return
self._rng.shuffle(target_nearest_points)
for x_near_z in target_nearest_points:
y_near_z = (x_near_z - m_z) / self._sigma
y_near = np.zeros(self._n_dim)
y_near[self._get_subspace_mask()[i]] = y_near_z # eq. (14)
B, D = self._eigen_decomposition()
invSqrtC = B @ np.diag(1 / D) @ B.T
z_near = np.dot(invSqrtC, y_near)
dist = np.linalg.norm(z_near) / 2 # midpoint (eq. (13))
if dist > CI:
beta = (dist**2 - CI**2) / ((dist**2) * (CI**2))
self._C = self._C + beta * np.outer(y_near, y_near)
self._B, self._D = None, None
# margin adaptation (eq. (16))
Y_near_z = (target_nearest_points - m_z) / self._sigma
Y_near = np.zeros((len(Y_near_z), self._n_dim))
Y_near[:, self._get_subspace_mask()[i]] = Y_near_z
B, D = self._eigen_decomposition()
corrected_invSqrtC = B @ np.diag(1 / D) @ B.T
self._B, self._D = None, None
Z_near = np.dot(Y_near, corrected_invSqrtC)
dist = np.linalg.norm(Z_near, axis=1) / 2 # midpoint
current_margin = np.mean(1 - norm.cdf(dist))
# eq. (16)
if current_margin > self._margin_target:
self._margin[i] /= self._margin_coeff
else:
self._margin[i] *= self._margin_coeff
def should_stop(self) -> bool:
B, D = self._eigen_decomposition()
dC = np.diag(self._C)
# Stop if the range of function values of the recent generation is below tolfun.
if (
self.generation > self._funhist_term
and np.max(self._funhist_values) - np.min(self._funhist_values) < self._tolfun
):
return True
# Stop if the std of the normal distribution is smaller than tolx
# in all coordinates and pc is smaller than tolx in all components.
if np.all(self._sigma * dC < self._tolx) and np.all(self._sigma * self._pc < self._tolx):
return True
# Stop if detecting divergent behavior.
if self._sigma * np.max(D) > self._tolxup:
return True
# No effect coordinates: stop if adding 0.2-standard deviations
# in any single coordinate does not change m.
if np.any(self._mean == self._mean + (0.2 * self._sigma * np.sqrt(dC))):
return True
# No effect axis: stop if adding 0.1-standard deviation vector in
# any principal axis direction of C does not change m. "pycma" check
# axis one by one at each generation.
i = self.generation % self.dim
if np.all(self._mean == self._mean + (0.1 * self._sigma * D[i] * B[:, i])):
return True
# Stop if the condition number of the covariance matrix exceeds 1e14.
condition_cov = np.max(D) / np.min(D)
if condition_cov > self._tolconditioncov:
return True
return False
def _is_valid_bounds(bounds: Optional[np.ndarray], mean: np.ndarray) -> bool:
if bounds is None:
return True
if (mean.size, 2) != bounds.shape:
return False
if not np.all(bounds[:, 0] <= mean):
return False
if not np.all(mean <= bounds[:, 1]):
return False
return True
def _compress_symmetric(sym2d: np.ndarray) -> np.ndarray:
assert len(sym2d.shape) == 2 and sym2d.shape[0] == sym2d.shape[1]
n = sym2d.shape[0]
dim = (n * (n + 1)) // 2
sym1d = np.zeros(dim)
start = 0
for i in range(n):
sym1d[start : start + n - i] = sym2d[i][i:] # noqa: E203
start += n - i
return sym1d
def _decompress_symmetric(sym1d: np.ndarray) -> np.ndarray:
n = int(np.sqrt(sym1d.size * 2))
assert (n * (n + 1)) // 2 == sym1d.size
R, C = np.triu_indices(n)
out = np.zeros((n, n), dtype=sym1d.dtype)
out[R, C] = sym1d
out[C, R] = sym1d
return out
cmaes-0.13.1/cmaes/safe_cma.py000066400000000000000000000567521524175644700161220ustar00rootroot00000000000000from __future__ import annotations
import math
import gpytorch.distributions
import numpy as np
from typing import Any
from typing import cast
from typing import Optional
import scipy
import gpytorch
import torch
_EPS = 1e-8
_MEAN_MAX = 1e32
_SIGMA_MAX = 1e32
class SafeCMA:
"""Safe CMA-ES stochastic optimizer class with ask-and-tell interface.
Example:
.. code::
import numpy as np
from cmaes import SafeCMA
# number of dimensions
dim = 5
# objective function
def quadratic(x):
coef = 1000 ** (np.arange(dim) / float(dim - 1))
return np.sum((x * coef) ** 2)
# safety function
def safe_function(x):
return x[0]
# safe seeds
safe_seeds_num = 10
safe_seeds = (np.random.rand(safe_seeds_num, dim) * 2 - 1) * 5
safe_seeds[:, 0] = - np.abs(safe_seeds[:, 0])
# evaluation of safe seeds (with a single safety function)
seeds_evals = np.array([quadratic(x) for x in safe_seeds])
seeds_safe_evals = np.stack([[safe_function(x)] for x in safe_seeds])
safety_threshold = np.array([0])
# optimizer (safe CMA-ES)
optimizer = SafeCMA(
sigma=1.,
safety_threshold=safety_threshold,
safe_seeds=safe_seeds,
seeds_evals=seeds_evals,
seeds_safe_evals=seeds_safe_evals,
)
unsafe_eval_counts = 0
best_eval = np.inf
for generation in range(400):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x = optimizer.ask()
value = quadratic(x)
safe_value = np.array([safe_function(x)])
# save best eval
best_eval = np.min((best_eval, value))
unsafe_eval_counts += (safe_value > safety_threshold)
solutions.append((x, value, safe_value))
# Tell evaluation values.
optimizer.tell(solutions)
print(f"#{generation} ({best_eval} {unsafe_eval_counts})")
if optimizer.should_stop():
break
Args:
safe_seeds:
Solutions whose safe function values are above the safety thresholds.
Safe CMA-ES uses the safe seed with the best evaluation value as
the initial mean vector of multi-variate Gaussian distributions.
seeds_evals:
Evaluation values of safe seeds on the objective function.
seeds_safe_evals:
Evaluation values of safe seeds on the safe functions.
safety_threshold:
Safety thresholds for each safe functions.
sigma:
Initial standard deviation of covariance matrix.
Safe CMA-ES modifies sigma when more than two safe seeds are given.
bounds:
Lower and upper domain boundaries for each parameter (optional).
n_max_resampling:
A maximum number of resampling parameters (default: 100).
If all sampled parameters are infeasible, the last sampled one
will be clipped with lower and upper bounds.
seed:
A seed number (optional).
population_size:
A population size (optional).
cov:
A covariance matrix (optional).
"""
# Paper: https://arxiv.org/abs/2405.10534
def __init__(
self,
safe_seeds: np.ndarray,
seeds_evals: np.ndarray,
seeds_safe_evals: np.ndarray,
safety_threshold: np.ndarray,
sigma: float,
bounds: Optional[np.ndarray] = None,
n_max_resampling: int = 100,
seed: Optional[int] = None,
population_size: Optional[int] = None,
cov: Optional[np.ndarray] = None,
):
# safety threshold
self.safety_threshold = safety_threshold
self.safety_func_num = len(safety_threshold)
# safe seeds
self.safe_seeds = safe_seeds
self.seeds_evals = seeds_evals
self.seeds_safe_evals = seeds_safe_evals
n_dim = len(safe_seeds[0])
assert n_dim > 1, "The dimension of mean must be larger than 1"
if population_size is None:
population_size = 4 + math.floor(3 * math.log(n_dim))
assert population_size > 0, "popsize must be non-zero positive value."
mu = population_size // 2
# hyperparameters for safe CMAES
self.kernel = gpytorch.kernels.RBFKernel()
self.kernel.lengthscale = 8.0 * n_dim
self.lip_penalty_coef = 1.0
self.lip_penalty_inc_rate = 10 # alpha
self.lip_penalty_dec_rate = self.lip_penalty_inc_rate ** (1.0 / n_dim)
self.lip_ite = 5 # T_data
self.sample_num_lip = population_size * self.lip_ite
self.sample_log_num = population_size * self.lip_ite
self.init_L_base = 10 # zeta_init
self.init_L = 100
self.gamma = 0.9
# log for safe CMAES
self.sampled_points = safe_seeds.copy()
self.sampled_safe_evals = seeds_safe_evals.copy()
# safe CMA-ES do not use negative weights
weights_prime = np.array(
np.log((population_size + 1) / 2) - np.log(np.arange(population_size) + 1)
)
weights_prime[weights_prime < 0] = 0
mu_eff = (np.sum(weights_prime[:mu]) ** 2) / np.sum(weights_prime[:mu] ** 2)
weights = weights_prime / weights_prime.sum()
# learning rate for the rank-one update
alpha_cov = 2
c1 = alpha_cov / ((n_dim + 1.3) ** 2 + mu_eff)
# learning rate for the rank-μ update
cmu = min(
1 - c1 - 1e-8, # 1e-8 is for large popsize.
alpha_cov * (mu_eff - 2 + 1 / mu_eff) / ((n_dim + 2) ** 2 + alpha_cov * mu_eff / 2),
)
assert c1 <= 1 - cmu, "invalid learning rate for the rank-one update"
assert cmu <= 1 - c1, "invalid learning rate for the rank-μ update"
cm = 1
# learning rate for the cumulation for the step-size control
c_sigma = (mu_eff + 2) / (n_dim + mu_eff + 5)
d_sigma = 1 + 2 * max(0, math.sqrt((mu_eff - 1) / (n_dim + 1)) - 1) + c_sigma
assert c_sigma < 1, "invalid learning rate for cumulation for the step-size control"
# learning rate for cumulation for the rank-one update
cc = (4 + mu_eff / n_dim) / (n_dim + 4 + 2 * mu_eff / n_dim)
assert cc <= 1, "invalid learning rate for cumulation for the rank-one update"
self._n_dim = n_dim
self._popsize = population_size
self._mu = mu
self._mu_eff = mu_eff
self._cc = cc
self._c1 = c1
self._cmu = cmu
self._c_sigma = c_sigma
self._d_sigma = d_sigma
self._cm = cm
# E||N(0, I)||
self._chi_n = math.sqrt(self._n_dim) * (
1.0 - (1.0 / (4.0 * self._n_dim)) + 1.0 / (21.0 * (self._n_dim**2))
)
self._weights = weights
# evolution path
self._p_sigma = np.zeros(n_dim)
self._pc = np.zeros(n_dim)
if cov is None:
self._C = np.eye(n_dim)
else:
assert cov.shape == (n_dim, n_dim), "Invalid shape of covariance matrix"
self._C = cov
self._D: Optional[np.ndarray] = None
self._B: Optional[np.ndarray] = None
self._rng = np.random.RandomState(seed)
# initial distribution parameter
self._sigma = sigma
mean, sigma = self._init_distribution(sigma)
assert sigma > 0, "sigma must be non-zero positive value"
assert np.all(np.abs(mean) < _MEAN_MAX), (
f"Abs of all elements of mean vector must be less than {_MEAN_MAX}"
)
self._mean = mean.copy()
self._sigma = sigma
# bounds contains low and high of each parameter.
assert bounds is None or _is_valid_bounds(bounds, mean), "invalid bounds"
self._bounds = bounds
self._n_max_resampling = n_max_resampling
self._g = 0
# Termination criteria
self._tolx = 1e-12 * sigma
self._tolxup = 1e4
self._tolfun = 1e-12
self._tolconditioncov = 1e14
self._funhist_term = 10 + math.ceil(30 * n_dim / population_size)
self._funhist_values = np.empty(self._funhist_term * 2)
def _compute_lipschitz_constant(self) -> np.ndarray:
likelihood = gpytorch.likelihoods.GaussianLikelihood(
noise_constraint=gpytorch.constraints.GreaterThan(0)
)
likelihood.noise = 0
B, D = self._eigen_decomposition()
invSqrtC = cast(np.ndarray, B.dot(np.diag(1 / D)).dot(B.T))
num_data = int(np.min((len(self.sampled_safe_evals), self.sample_num_lip)))
prev_x = self.sampled_points[-num_data:]
z_points = (prev_x - self._mean).dot(invSqrtC) / self._sigma
target_safe_evals = self.sampled_safe_evals[-num_data:]
evals_mean = np.mean(target_safe_evals, axis=0)
evals_std = np.std(target_safe_evals, axis=0)
modified_evals = (target_safe_evals - evals_mean) / evals_std
# function that returns the negative norm of gradient
def df(x: np.ndarray, model: ExactGPModel) -> float | np.ndarray:
out_scalar = x.ndim == 1
x = np.atleast_2d(x)
grad_norm = torch.zeros(len(x))
X = torch.autograd.Variable(torch.Tensor(np.atleast_2d(x)), requires_grad=True)
mean = likelihood(model(X)).mean
dxdmean = torch.autograd.grad(mean.sum(), X)[0]
grad_norm = torch.sqrt(torch.sum(dxdmean * dxdmean, dim=1))
if out_scalar:
grad_norm = grad_norm.mean().to(torch.float64)
return -grad_norm.item()
return -grad_norm.detach().numpy()
def elementwise_df(i: int) -> float:
samples = self._rng.randn(self.sample_num_lip, self._n_dim)
samples = np.concatenate([samples, z_points], axis=0)
model = ExactGPModel(z_points, modified_evals[:, i], likelihood, self.kernel)
try:
pred_samples = df(samples, model) * evals_std[i]
except Exception:
# if fail to optimize
return self.lipschitz_constant[i]
if np.isnan(pred_samples).any():
return self.lipschitz_constant[i]
x0 = samples[np.argmin(pred_samples)]
try:
bounds = np.tile([-3, 3], (self._n_dim, 1))
res = scipy.optimize.minimize(
df,
x0,
method="L-BFGS-B",
bounds=bounds,
args=(model),
options={"maxiter": 200},
)
result_value = res.fun * evals_std[i]
if not np.isnan(result_value):
return -float(result_value)
else:
return -np.min(pred_samples)
except Exception:
# if fail to optimize
return -np.min(pred_samples)
return np.array([elementwise_df(i) for i in range(self.safety_func_num)])
def __getstate__(self) -> dict[str, Any]:
attrs = {}
for name in self.__dict__:
# Remove _rng in pickle serialized object.
if name == "_rng":
continue
if name == "_C":
sym1d = _compress_symmetric(self._C)
attrs["_c_1d"] = sym1d
continue
attrs[name] = getattr(self, name)
return attrs
def __setstate__(self, state: dict[str, Any]) -> None:
state["_C"] = _decompress_symmetric(state["_c_1d"])
del state["_c_1d"]
self.__dict__.update(state)
# Set _rng for unpickled object.
setattr(self, "_rng", np.random.RandomState())
@property
def dim(self) -> int:
"""A number of dimensions"""
return self._n_dim
@property
def population_size(self) -> int:
"""A population size"""
return self._popsize
@property
def generation(self) -> int:
"""Generation number which is monotonically incremented
when multi-variate gaussian distribution is updated."""
return self._g
@property
def mean(self) -> np.ndarray:
"""Mean Vector"""
return self._mean
def reseed_rng(self, seed: int) -> None:
self._rng.seed(seed)
def set_bounds(self, bounds: Optional[np.ndarray]) -> None:
"""Update boundary constraints"""
assert bounds is None or _is_valid_bounds(bounds, self._mean), "invalid bounds"
self._bounds = bounds
def _init_distribution(self, sigma: float) -> tuple[np.ndarray, float]:
# set initial mean vector
best_seed_id = np.argmin(self.seeds_evals)
mean = self.safe_seeds[best_seed_id]
self._mean = mean.copy() # (eq. 26)
# set initial step-size
if len(self.sampled_points) > 1:
lip = self._compute_lipschitz_constant()
if len(self.sampled_safe_evals) < self.sample_num_lip:
exponent = 1 / len(self.sampled_safe_evals)
lip = lip * (self.init_L_base**exponent)
lip = np.clip(lip, self.init_L, None)
else:
lip = np.ones(self.safety_func_num) * self.init_L
self.lipschitz_constant = lip
slack = self.safety_threshold - self.seeds_safe_evals[best_seed_id]
delta = np.min((slack) / self.lipschitz_constant)
gauss_tr = np.sqrt(scipy.stats.chi2.ppf(self.gamma, df=self._n_dim))
sigma = sigma * np.min((delta / gauss_tr, 1)) # (eq. 27)
return mean, sigma
def ask(self) -> np.ndarray:
"""Sample a parameter"""
for i in range(self._n_max_resampling):
x = self._sample_solution()
if self._is_feasible(x):
return x
x = self._sample_solution()
x = self._repair_infeasible_params(x)
return x
def _eigen_decomposition(self) -> tuple[np.ndarray, np.ndarray]:
if self._B is not None and self._D is not None:
return self._B, self._D
self._C = (self._C + self._C.T) / 2
D2, B = np.linalg.eigh(self._C)
D = np.sqrt(np.where(D2 < 0, _EPS, D2))
self._C = np.dot(np.dot(B, np.diag(D**2)), B.T)
self._B, self._D = B, D
return B, D
def _sample_solution(self) -> np.ndarray:
B, D = self._eigen_decomposition()
z = self._rng.randn(self._n_dim) # ~ N(0, I)
invSqrtC = cast(np.ndarray, B.dot(np.diag(1 / D)).dot(B.T))
if self.sampled_safe_evals is not None:
log_num = np.min([self.sample_log_num, len(self.sampled_points)])
prev_x = self.sampled_points[-log_num:]
prev_safe_evals = self.sampled_safe_evals[-log_num:]
sampled_z_points = (prev_x - self._mean).dot(invSqrtC) / self._sigma
# radius: radius of trust region around evaluated points
slack = self.safety_threshold[:, None, None] - prev_safe_evals[None, :, :]
radius = np.min(slack / self.lipschitz_constant[:, None, None], axis=(0, 2)) # (eq.13)
radius[radius < 0] = -np.inf
# dist: distance between current samples and evaluated points
dist = np.sqrt(((z[None, :] - sampled_z_points) ** 2).sum(axis=1))
invalid_dist = np.clip(np.min(dist[None, :] - radius), 0, np.inf)
argmin_sample_id = np.argmin(dist[None, :] - radius)
closest_z_sample = sampled_z_points[argmin_sample_id]
ratio = invalid_dist / dist[argmin_sample_id]
z = (1 - ratio) * z + ratio * closest_z_sample # (eq.15)
y = cast(np.ndarray, B.dot(np.diag(D)).dot(B.T)).dot(z) # ~ N(0, C)
x = self._mean + self._sigma * y # ~ N(m, σ^2 C)
return x
def _is_feasible(self, param: np.ndarray) -> bool:
if self._bounds is None:
return True
return cast(
bool,
np.all(param >= self._bounds[:, 0]) and np.all(param <= self._bounds[:, 1]),
) # Cast bool_ to bool.
def _repair_infeasible_params(self, param: np.ndarray) -> np.ndarray:
if self._bounds is None:
return param
# clip with lower and upper bound.
param = np.where(param < self._bounds[:, 0], self._bounds[:, 0], param)
param = np.where(param > self._bounds[:, 1], self._bounds[:, 1], param)
return param
def tell(self, solutions: list[tuple[np.ndarray, float, float]]) -> None:
self._naive_cma_update(solutions)
X = np.stack([s[0] for s in solutions])
safe_evals = np.array([s[2] for s in solutions])
self._add_evaluated_point(X, safe_evals)
self.lipschitz_constant = self._compute_lipschitz_constant() # (eq.19)
if len(self.sampled_safe_evals) < self.sample_num_lip:
exponent = 1 / len(self.sampled_safe_evals) # (eq.22)
self.lipschitz_constant *= self.init_L_base**exponent
inv_num = float(np.sum(safe_evals > self.safety_threshold))
if inv_num > 0:
self.lip_penalty_coef *= self.lip_penalty_inc_rate ** (inv_num / self._popsize)
else:
self.lip_penalty_coef /= self.lip_penalty_dec_rate
self.lip_penalty_coef = np.max((self.lip_penalty_coef, 1))
self.lipschitz_constant *= self.lip_penalty_coef # (eq.24)
def _add_evaluated_point(self, X: np.ndarray, safe_evals: np.ndarray) -> None:
self.sampled_points = np.concatenate([self.sampled_points, X], axis=0)
self.sampled_safe_evals = np.vstack([self.sampled_safe_evals, safe_evals])
def _naive_cma_update(self, solutions: list[tuple[np.ndarray, float, float]]) -> None:
"""Tell evaluation values"""
assert len(solutions) == self._popsize, "Must tell popsize-length solutions."
for s in solutions:
assert np.all(np.abs(s[0]) < _MEAN_MAX), (
f"Abs of all param values must be less than {_MEAN_MAX} to avoid overflow errors"
)
self._g += 1
solutions.sort(key=lambda s: s[1])
# Stores 'best' and 'worst' values of the
# last 'self._funhist_term' generations.
funhist_idx = 2 * (self.generation % self._funhist_term)
self._funhist_values[funhist_idx] = solutions[0][1]
self._funhist_values[funhist_idx + 1] = solutions[-1][1]
# Sample new population of search_points, for k=1, ..., popsize
B, D = self._eigen_decomposition()
self._B, self._D = None, None
x_k = np.array([s[0] for s in solutions]) # ~ N(m, σ^2 C)
y_k = (x_k - self._mean) / self._sigma # ~ N(0, C)
# Selection and recombination
y_w = np.sum(y_k[: self._mu].T * self._weights[: self._mu], axis=1)
self._mean += self._cm * self._sigma * y_w # (eq.7)
# Step-size control
C_2 = cast(
np.ndarray, cast(np.ndarray, B.dot(np.diag(1 / D))).dot(B.T)
) # C^(-1/2) = B D^(-1) B^T
self._p_sigma = (1 - self._c_sigma) * self._p_sigma + math.sqrt(
self._c_sigma * (2 - self._c_sigma) * self._mu_eff
) * C_2.dot(y_w)
norm_p_sigma = np.linalg.norm(self._p_sigma)
self._sigma *= np.exp(
(self._c_sigma / self._d_sigma) * (norm_p_sigma / self._chi_n - 1)
) # (eq.8)
self._sigma = min(self._sigma, _SIGMA_MAX)
# Covariance matrix adaption
h_sigma_cond_left = norm_p_sigma / math.sqrt(
1 - (1 - self._c_sigma) ** (2 * (self._g + 1))
)
h_sigma_cond_right = (1.4 + 2 / (self._n_dim + 1)) * self._chi_n
h_sigma = 1.0 if h_sigma_cond_left < h_sigma_cond_right else 0.0
self._pc = (1 - self._cc) * self._pc + h_sigma * math.sqrt(
self._cc * (2 - self._cc) * self._mu_eff
) * y_w
rank_one = np.outer(self._pc, self._pc)
rank_mu = np.sum(
np.array([w * np.outer(y, y) for w, y in zip(self._weights, y_k)]), axis=0
)
delta_h_sigma = (1 - h_sigma) * self._cc * (2 - self._cc)
assert delta_h_sigma <= 1
self._C = (
(1 + self._c1 * delta_h_sigma - self._c1 - self._cmu * np.sum(self._weights)) * self._C
+ self._c1 * rank_one
+ self._cmu * rank_mu
) # (eq.9)
def should_stop(self) -> bool:
B, D = self._eigen_decomposition()
dC = np.diag(self._C)
# Stop if the range of function values of the recent generation is below tolfun.
if (
self.generation > self._funhist_term
and np.max(self._funhist_values) - np.min(self._funhist_values) < self._tolfun
):
return True
# Stop if the std of the normal distribution is smaller than tolx
# in all coordinates and pc is smaller than tolx in all components.
if np.all(self._sigma * dC < self._tolx) and np.all(self._sigma * self._pc < self._tolx):
return True
# Stop if detecting divergent behavior.
if self._sigma * np.max(D) > self._tolxup:
return True
# No effect coordinates: stop if adding 0.2-standard deviations
# in any single coordinate does not change m.
if np.any(self._mean == self._mean + (0.2 * self._sigma * np.sqrt(dC))):
return True
# No effect axis: stop if adding 0.1-standard deviation vector in
# any principal axis direction of C does not change m. "pycma" check
# axis one by one at each generation.
i = self.generation % self.dim
if np.all(self._mean == self._mean + (0.1 * self._sigma * D[i] * B[:, i])):
return True
# Stop if the condition number of the covariance matrix exceeds 1e14.
condition_cov = np.max(D) / np.min(D)
if condition_cov > self._tolconditioncov:
return True
return False
def _is_valid_bounds(bounds: Optional[np.ndarray], mean: np.ndarray) -> bool:
if bounds is None:
return True
if (mean.size, 2) != bounds.shape:
return False
if not np.all(bounds[:, 0] <= mean):
return False
if not np.all(mean <= bounds[:, 1]):
return False
return True
def _compress_symmetric(sym2d: np.ndarray) -> np.ndarray:
assert len(sym2d.shape) == 2 and sym2d.shape[0] == sym2d.shape[1]
n = sym2d.shape[0]
dim = (n * (n + 1)) // 2
sym1d = np.zeros(dim)
start = 0
for i in range(n):
sym1d[start : start + n - i] = sym2d[i][i:] # noqa: E203
start += n - i
return sym1d
def _decompress_symmetric(sym1d: np.ndarray) -> np.ndarray:
n = int(np.sqrt(sym1d.size * 2))
assert (n * (n + 1)) // 2 == sym1d.size
R, C = np.triu_indices(n)
out = np.zeros((n, n), dtype=sym1d.dtype)
out[R, C] = sym1d
out[C, R] = sym1d
return out
class ExactGPModel(gpytorch.models.ExactGP):
def __init__(
self,
train_x: np.ndarray,
train_y: np.ndarray,
likelihood: gpytorch.likelihoods.Likelihood,
kernel: gpytorch.kernels.Kernel,
) -> None:
super(ExactGPModel, self).__init__(
torch.from_numpy(train_x), torch.from_numpy(train_y), likelihood
)
self.mean_module = gpytorch.means.ConstantMean()
self.covar_module = kernel
self.eval()
likelihood.eval()
def forward(self, x: torch.Tensor) -> gpytorch.distributions.Distribution:
mean_x = self.mean_module(x)
covar_x = self.covar_module(x)
return gpytorch.distributions.MultivariateNormal(mean_x, covar_x)
cmaes-0.13.1/examples/000077500000000000000000000000001524175644700145215ustar00rootroot00000000000000cmaes-0.13.1/examples/bipop_cma.py000066400000000000000000000047421524175644700170330ustar00rootroot00000000000000import math
import numpy as np
from cmaes import CMA
def ackley(x1, x2):
return (
-20 * math.exp(-0.2 * math.sqrt(0.5 * (x1**2 + x2**2)))
- math.exp(0.5 * (math.cos(2 * math.pi * x1) + math.cos(2 * math.pi * x2)))
+ math.e
+ 20
)
def main():
seed = 0
rng = np.random.RandomState(0)
bounds = np.array([[-32.768, 32.768], [-32.768, 32.768]])
lower_bounds, upper_bounds = bounds[:, 0], bounds[:, 1]
mean = lower_bounds + (rng.rand(2) * (upper_bounds - lower_bounds))
sigma0 = 32.768 * 2 / 5 # 1/5 of the domain width
sigma = sigma0
optimizer = CMA(mean=mean, sigma=sigma, bounds=bounds, seed=0)
n_restarts = 0 # A small restart doesn't count in the n_restarts
small_n_eval, large_n_eval = 0, 0
popsize0 = optimizer.population_size
inc_popsize = 2
# Initial run is with "normal" population size; it is
# the large population before first doubling, but its
# budget accounting is the same as in case of small
# population.
poptype = "small"
while n_restarts <= 5:
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = ackley(x[0], x[1])
solutions.append((x, value))
# print("{:10.5f} {:6.2f} {:6.2f}".format(value, x[0], x[1]))
optimizer.tell(solutions)
if optimizer.should_stop():
seed += 1
n_eval = optimizer.population_size * optimizer.generation
if poptype == "small":
small_n_eval += n_eval
else: # poptype == "large"
large_n_eval += n_eval
if small_n_eval < large_n_eval:
poptype = "small"
popsize_multiplier = inc_popsize**n_restarts
popsize = math.floor(popsize0 * popsize_multiplier ** (rng.uniform() ** 2))
sigma = sigma0 * 10 ** (-2 * rng.uniform())
else:
poptype = "large"
n_restarts += 1
popsize = popsize0 * (inc_popsize**n_restarts)
sigma = sigma0
mean = lower_bounds + (rng.rand(2) * (upper_bounds - lower_bounds))
optimizer = CMA(
mean=mean,
sigma=sigma,
bounds=bounds,
seed=seed,
population_size=popsize,
)
print("Restart CMA-ES with popsize={} ({})".format(popsize, poptype))
if __name__ == "__main__":
main()
cmaes-0.13.1/examples/catcma.py000066400000000000000000000031661524175644700163310ustar00rootroot00000000000000import numpy as np
from cmaes import CatCMA
def sphere_com(x, c):
dim_co = len(x)
dim_ca = len(c)
if dim_co < 2:
raise ValueError("dimension must be greater one")
sphere = sum(x * x)
com = dim_ca - sum(c[:, 0])
return sphere + com
def rosenbrock_clo(x, c):
dim_co = len(x)
dim_ca = len(c)
if dim_co < 2:
raise ValueError("dimension must be greater one")
rosenbrock = sum(100 * (x[:-1] ** 2 - x[1:]) ** 2 + (x[:-1] - 1) ** 2)
clo = dim_ca - (c[:, 0].argmin() + c[:, 0].prod() * dim_ca)
return rosenbrock + clo
def mc_proximity(x, c, cat_num):
dim_co = len(x)
dim_ca = len(c)
if dim_co < 2:
raise ValueError("dimension must be greater one")
if dim_co != dim_ca:
raise ValueError(
"number of dimensions of continuous and categorical variables "
"must be equal in mc_proximity"
)
c_index = np.argmax(c, axis=1) / cat_num
return sum((x - c_index) ** 2) + sum(c_index)
if __name__ == "__main__":
cont_dim = 5
cat_dim = 5
cat_num = np.array([3, 4, 5, 5, 5])
# cat_num = 3 * np.ones(cat_dim, dtype=np.int64)
optimizer = CatCMA(mean=3.0 * np.ones(cont_dim), sigma=1.0, cat_num=cat_num)
for generation in range(200):
solutions = []
for _ in range(optimizer.population_size):
x, c = optimizer.ask()
value = mc_proximity(x, c, cat_num)
if generation % 10 == 0:
print(f"#{generation} {value}")
solutions.append(((x, c), value))
optimizer.tell(solutions)
if optimizer.should_stop():
break
cmaes-0.13.1/examples/catcma_with_margin.py000066400000000000000000000052401524175644700207140ustar00rootroot00000000000000import numpy as np
from cmaes import CatCMAwM
def SphereIntCOM(x, z, c):
return sum(x * x) + sum(z * z) + len(c) - sum(c[:, 0])
def SphereInt(x, z):
return sum(x * x) + sum(z * z)
def SphereCOM(x, c):
return sum(x * x) + len(c) - sum(c[:, 0])
def f_cont_int_cat():
# [lower_bound, upper_bound] for each continuous variable
X = [[-5, 5], [-5, 5]]
# possible values for each integer variable
Z = [[-1, 0, 1], [-2, -1, 0, 1, 2]]
# number of categories for each categorical variable
C = [3, 3]
optimizer = CatCMAwM(x_space=X, z_space=Z, c_space=C)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
sol = optimizer.ask()
value = SphereIntCOM(sol.x, sol.z, sol.c)
solutions.append((sol, value))
print(f"#{generation} {sol} evaluation: {value}")
optimizer.tell(solutions)
def f_cont_int():
# [lower_bound, upper_bound] for each continuous variable
X = [[-np.inf, np.inf], [-np.inf, np.inf]]
# possible values for each integer variable
Z = [[-2, -1, 0, 1, 2], [-2, -1, 0, 1, 2]]
# initial distribution parameters (Optional)
# If you know a promising solution for X and Z, set init_mean to that value.
init_mean = np.ones(len(X) + len(Z))
init_cov = np.diag(np.ones(len(X) + len(Z)))
init_sigma = 1.0
optimizer = CatCMAwM(x_space=X, z_space=Z, mean=init_mean, cov=init_cov, sigma=init_sigma)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
sol = optimizer.ask()
value = SphereInt(sol.x, sol.z)
solutions.append((sol, value))
print(f"#{generation} {sol} evaluation: {value}")
optimizer.tell(solutions)
def f_cont_cat():
# [lower_bound, upper_bound] for each continuous variable
X = [[-5, 5], [-5, 5]]
# number of categories for each categorical variable
C = [3, 5]
# initial distribution parameters (Optional)
init_cat_param = np.array(
[
[0.5, 0.3, 0.2, 0.0, 0.0], # zero-padded at the end
[0.2, 0.2, 0.2, 0.2, 0.2], # each row must sum to 1
]
)
optimizer = CatCMAwM(x_space=X, c_space=C, cat_param=init_cat_param)
for generation in range(50):
solutions = []
for _ in range(optimizer.population_size):
sol = optimizer.ask()
value = SphereCOM(sol.x, sol.c)
solutions.append((sol, value))
print(f"#{generation} {sol} evaluation: {value}")
optimizer.tell(solutions)
if __name__ == "__main__":
f_cont_int_cat()
# f_cont_int()
# f_cont_cat()
cmaes-0.13.1/examples/cma_sop.py000066400000000000000000000116341524175644700165210ustar00rootroot00000000000000import numpy as np
from cmaes.cmasop import CMASoP
def example1():
"""
example with benchmark on sets of points
"""
# number of total dimensions
dim = 10
# number of dimensions in each subspace
subspace_dim = 2
# number of points in each subspace
point_num = 10
# objective function
def quadratic(x):
coef = 1000 ** (np.arange(dim) / float(dim - 1))
return np.sum((x * coef) ** 2)
# sets_of_points (on [-5, 5])
discrete_subspace_num = dim // subspace_dim
sets_of_points = (2 * np.random.rand(discrete_subspace_num, point_num, subspace_dim) - 1) * 5
# add the optimal solution (for benchmark function)
sets_of_points[:, -1] = np.zeros(subspace_dim)
np.random.shuffle(sets_of_points)
# optimizer (CMA-ES-SoP)
optimizer = CMASoP(
sets_of_points=sets_of_points,
mean=np.random.rand(dim) * 4 + 1,
sigma=2.0,
)
best_eval = np.inf
eval_count = 0
for generation in range(200):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x, enc_x = optimizer.ask()
value = quadratic(enc_x)
# save best eval
best_eval = np.min((best_eval, value))
eval_count += 1
solutions.append((x, value))
# Tell evaluation values.
optimizer.tell(solutions)
print(f"#{generation} ({best_eval} {eval_count})")
if best_eval < 1e-4 or optimizer.should_stop():
break
def example2():
"""
example with benchmark on mixed variable (sets of points and continuous variable)
"""
# number of total dimensions
dim = 10
# number of dimensions in each subspace
subspace_dim = 2
# number of points in each subspace
point_num = 10
# objective function
def quadratic(x):
coef = 1000 ** (np.arange(dim) / float(dim - 1))
return np.sum((x * coef) ** 2)
# sets_of_points (on [-5, 5])
# almost half of the subspaces are continuous spaces
discrete_subspace_num = (dim // 2) // subspace_dim
sets_of_points = (2 * np.random.rand(discrete_subspace_num, point_num, subspace_dim) - 1) * 5
# add the optimal solution (for benchmark function)
sets_of_points[:, -1] = np.zeros(subspace_dim)
np.random.shuffle(sets_of_points)
# optimizer (CMA-ES-SoP)
optimizer = CMASoP(
sets_of_points=sets_of_points,
mean=np.random.rand(dim) * 4 + 1,
sigma=2.0,
)
best_eval = np.inf
eval_count = 0
for generation in range(200):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x, enc_x = optimizer.ask()
value = quadratic(enc_x)
# save best eval
best_eval = np.min((best_eval, value))
eval_count += 1
solutions.append((x, value))
# Tell evaluation values.
optimizer.tell(solutions)
print(f"#{generation} ({best_eval} {eval_count})")
if best_eval < 1e-4 or optimizer.should_stop():
break
def example3():
"""
example with benchmark on mixed variable
(continuous variable and sets of points with different numbers of dimensions and points)
"""
# numbers of dimensions in each subspace
subspace_dim_list = [2, 3, 5]
cont_dim = 10
# numbers of points in each subspace
point_num_list = [10, 20, 40]
# number of total dimensions
dim = int(np.sum(subspace_dim_list) + cont_dim)
# objective function
def quadratic(x):
coef = 1000 ** (np.arange(dim) / float(dim - 1))
return np.sum((coef * x) ** 2)
# sets_of_points (on [-5, 5])
discrete_subspace_num = len(subspace_dim_list)
sets_of_points = [
(2 * np.random.rand(point_num_list[i], subspace_dim_list[i]) - 1) * 5
for i in range(discrete_subspace_num)
]
# add the optimal solution (for benchmark function)
for i in range(discrete_subspace_num):
sets_of_points[i][-1] = np.zeros(subspace_dim_list[i])
np.random.shuffle(sets_of_points[i])
# optimizer (CMA-ES-SoP)
optimizer = CMASoP(
sets_of_points=sets_of_points,
mean=np.random.rand(dim) * 4 + 1,
sigma=2.0,
)
best_eval = np.inf
eval_count = 0
for generation in range(400):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x, enc_x = optimizer.ask()
value = quadratic(enc_x)
# save best eval
best_eval = np.min((best_eval, value))
eval_count += 1
solutions.append((x, value))
# Tell evaluation values.
optimizer.tell(solutions)
print(f"#{generation} ({best_eval} {eval_count})")
if best_eval < 1e-4 or optimizer.should_stop():
break
if __name__ == "__main__":
example1()
example2()
# example3()
cmaes-0.13.1/examples/cma_with_margin_binary.py000066400000000000000000000025151524175644700215720ustar00rootroot00000000000000import numpy as np
from cmaes import CMAwM
def ellipsoid_onemax(x, n_zdim):
n = len(x)
n_rdim = n - n_zdim
r = 10
if len(x) < 2:
raise ValueError("dimension must be greater one")
ellipsoid = sum([(1000 ** (i / (n_rdim - 1)) * x[i]) ** 2 for i in range(n_rdim)])
onemax = n_zdim - (0.0 < x[(n - n_zdim) :]).sum()
return ellipsoid + r * onemax
def main():
binary_dim, continuous_dim = 10, 10
dim = binary_dim + continuous_dim
bounds = np.concatenate(
[
np.tile([-np.inf, np.inf], (continuous_dim, 1)),
np.tile([0, 1], (binary_dim, 1)),
]
)
steps = np.concatenate([np.zeros(continuous_dim), np.ones(binary_dim)])
optimizer = CMAwM(mean=np.zeros(dim), sigma=2.0, bounds=bounds, steps=steps)
print(" evals f(x)")
print("====== ==========")
evals = 0
while True:
solutions = []
for _ in range(optimizer.population_size):
x_for_eval, x_for_tell = optimizer.ask()
value = ellipsoid_onemax(x_for_eval, binary_dim)
evals += 1
solutions.append((x_for_tell, value))
if evals % 300 == 0:
print(f"{evals:5d} {value:10.5f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
if __name__ == "__main__":
main()
cmaes-0.13.1/examples/cma_with_margin_integer.py000066400000000000000000000023031524175644700217360ustar00rootroot00000000000000import numpy as np
from cmaes import CMAwM
def ellipsoid_int(x, _):
n = len(x)
if len(x) < 2:
raise ValueError("dimension must be greater one")
return sum([(1000 ** (i / (n - 1)) * x[i]) ** 2 for i in range(n)])
def main():
integer_dim, continuous_dim = 10, 10
dim = integer_dim + continuous_dim
bounds = np.concatenate(
[
np.tile([-np.inf, np.inf], (continuous_dim, 1)),
np.tile([-10, 11], (integer_dim, 1)),
]
)
steps = np.concatenate([np.zeros(continuous_dim), np.ones(integer_dim)])
optimizer = CMAwM(mean=5 * np.ones(dim), sigma=2.0, bounds=bounds, steps=steps)
print(" evals f(x)")
print("====== ==========")
evals = 0
while True:
solutions = []
for _ in range(optimizer.population_size):
x_for_eval, x_for_tell = optimizer.ask()
value = ellipsoid_int(x_for_eval, integer_dim)
evals += 1
solutions.append((x_for_tell, value))
if evals % 300 == 0:
print(f"{evals:5d} {value:10.5f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
if __name__ == "__main__":
main()
cmaes-0.13.1/examples/como_catcma_with_margin.py000066400000000000000000000022261524175644700217320ustar00rootroot00000000000000import numpy as np
from cmaes import COMOCatCMAwM
def DSIntLFTL(x, z, c, cat_num):
Sphere1 = sum((x / 10) ** 2) / len(x)
Sphere2 = sum((x / 10 - 1) ** 2) / len(x)
SphereInt1 = sum((z / 10) ** 2) / len(z)
SphereInt2 = sum((z / 10 - 1) ** 2) / len(z)
c_idx = c.argmax(axis=1)
LF = (len(c) - (c_idx == 0).cumprod().sum()) / len(c)
TL = (len(c) - (c_idx == np.asarray(cat_num) - 1)[::-1].cumprod().sum()) / len(c)
obj1 = Sphere1 + SphereInt1 + LF
obj2 = Sphere2 + SphereInt2 + TL
return [obj1, obj2]
if __name__ == "__main__":
# [lower_bound, upper_bound] for each continuous variable
X = [[-5, 15]] * 3
# possible values for each integer variable
Z = [range(-5, 16)] * 3
# number of categories for each categorical variable
C = [5] * 3
optimizer = COMOCatCMAwM(x_space=X, z_space=Z, c_space=C)
evals = 0
while evals < 7000:
solutions = []
for sol in optimizer.ask_iter():
value = DSIntLFTL(sol.x, sol.z, sol.c, C)
evals += 1
solutions.append((sol, value))
optimizer.tell(solutions)
print(evals, optimizer.incumbent_objectives)
cmaes-0.13.1/examples/ellipsoid_function.py000066400000000000000000000014571524175644700207730ustar00rootroot00000000000000import numpy as np
from cmaes import CMA
def ellipsoid(x):
n = len(x)
if len(x) < 2:
raise ValueError("dimension must be greater one")
return sum([(1000 ** (i / (n - 1)) * x[i]) ** 2 for i in range(n)])
def main():
dim = 40
optimizer = CMA(mean=3 * np.ones(dim), sigma=2.0)
print(" evals f(x)")
print("====== ==========")
evals = 0
while True:
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = ellipsoid(x)
evals += 1
solutions.append((x, value))
if evals % 3000 == 0:
print(f"{evals:5d} {value:10.5f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
if __name__ == "__main__":
main()
cmaes-0.13.1/examples/ipop_cma.py000066400000000000000000000032101524175644700166560ustar00rootroot00000000000000import math
import numpy as np
from cmaes import CMA
def ackley(x1, x2):
return (
-20 * math.exp(-0.2 * math.sqrt(0.5 * (x1**2 + x2**2)))
- math.exp(0.5 * (math.cos(2 * math.pi * x1) + math.cos(2 * math.pi * x2)))
+ math.e
+ 20
)
def main():
seed = 0
rng = np.random.RandomState(1)
bounds = np.array([[-32.768, 32.768], [-32.768, 32.768]])
lower_bounds, upper_bounds = bounds[:, 0], bounds[:, 1]
mean = lower_bounds + (rng.rand(2) * (upper_bounds - lower_bounds))
sigma = 32.768 * 2 / 5 # 1/5 of the domain width
optimizer = CMA(mean=mean, sigma=sigma, bounds=bounds, seed=0)
# Multiplier for increasing population size before each restart.
inc_popsize = 2
print(" g f(x1,x2) x1 x2 ")
print("=== ========== ====== ======")
for generation in range(200):
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = ackley(x[0], x[1])
solutions.append((x, value))
print(f"{generation:3d} {value:10.5f} {x[0]:6.2f} {x[1]:6.2f}")
optimizer.tell(solutions)
if optimizer.should_stop():
seed += 1
popsize = optimizer.population_size * inc_popsize
mean = lower_bounds + (rng.rand(2) * (upper_bounds - lower_bounds))
optimizer = CMA(
mean=mean,
sigma=sigma,
bounds=bounds,
seed=seed,
population_size=popsize,
)
print("Restart CMA-ES with popsize={}".format(popsize))
if __name__ == "__main__":
main()
cmaes-0.13.1/examples/lra_cma.py000066400000000000000000000013251524175644700164720ustar00rootroot00000000000000import numpy as np
from cmaes import CMA
def rastrigin(x):
dim = len(x)
if dim < 2:
raise ValueError("dimension must be greater one")
return 10 * dim + sum(x**2 - 10 * np.cos(2 * np.pi * x))
if __name__ == "__main__":
dim = 40
optimizer = CMA(mean=3 * np.ones(dim), sigma=2.0, seed=10, lr_adapt=True)
for generation in range(50000):
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = rastrigin(x)
if generation % 500 == 0:
print(f"#{generation} {value}")
solutions.append((x, value))
optimizer.tell(solutions)
if optimizer.should_stop():
break
cmaes-0.13.1/examples/mapcma.py000066400000000000000000000014471524175644700163370ustar00rootroot00000000000000import numpy as np
from cmaes import MAPCMA
def rosenbrock(x):
dim = len(x)
if dim < 2:
raise ValueError("dimension must be greater one")
return sum(100 * (x[:-1] ** 2 - x[1:]) ** 2 + (x[:-1] - 1) ** 2)
if __name__ == "__main__":
dim = 20
optimizer = MAPCMA(mean=np.zeros(dim), sigma=0.5, momentum_r=dim)
print(" evals f(x)")
print("====== ==========")
evals = 0
while True:
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = rosenbrock(x)
evals += 1
solutions.append((x, value))
if evals % 1000 == 0:
print(f"{evals:5d} {value:10.5f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
cmaes-0.13.1/examples/optuna_sampler.py000066400000000000000000000006561524175644700201330ustar00rootroot00000000000000import optuna
def objective(trial: optuna.Trial):
x1 = trial.suggest_float("x1", -4, 4)
x2 = trial.suggest_float("x2", -4, 4)
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
def main():
optuna.logging.set_verbosity(optuna.logging.INFO)
study = optuna.create_study(sampler=optuna.samplers.CmaEsSampler())
study.optimize(objective, n_trials=250, gc_after_trial=False)
if __name__ == "__main__":
main()
cmaes-0.13.1/examples/quadratic_2d_function.py000066400000000000000000000012631524175644700213440ustar00rootroot00000000000000import numpy as np
from cmaes import CMA
def quadratic(x1, x2):
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
def main():
optimizer = CMA(mean=np.zeros(2), sigma=1.3)
print(" g f(x1,x2) x1 x2 ")
print("=== ========== ====== ======")
while True:
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = quadratic(x[0], x[1])
solutions.append((x, value))
print(f"{optimizer.generation:3d} {value:10.5f} {x[0]:6.2f} {x[1]:6.2f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
if __name__ == "__main__":
main()
cmaes-0.13.1/examples/safecma.py000066400000000000000000000067611524175644700165040ustar00rootroot00000000000000import numpy as np
from cmaes.safe_cma import SafeCMA
def example1():
"""
example with a single safety function
"""
# number of dimensions
dim = 5
# objective function
def quadratic(x):
coef = 1000 ** (np.arange(dim) / float(dim - 1))
return np.sum((x * coef) ** 2)
# safety function
def safe_function(x):
return x[0]
# safe seeds
safe_seeds_num = 10
safe_seeds = (np.random.rand(safe_seeds_num, dim) * 2 - 1) * 5
safe_seeds[:, 0] = -np.abs(safe_seeds[:, 0])
# evaluation of safe seeds (with a single safety function)
seeds_evals = np.array([quadratic(x) for x in safe_seeds])
seeds_safe_evals = np.stack([[safe_function(x)] for x in safe_seeds])
safety_threshold = np.array([0])
# optimizer (safe CMA-ES)
optimizer = SafeCMA(
sigma=1.0,
safety_threshold=safety_threshold,
safe_seeds=safe_seeds,
seeds_evals=seeds_evals,
seeds_safe_evals=seeds_safe_evals,
)
unsafe_eval_counts = 0
best_eval = np.inf
for generation in range(400):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x = optimizer.ask()
value = quadratic(x)
safe_value = np.array([safe_function(x)])
# save best eval
best_eval = np.min((best_eval, value))
unsafe_eval_counts += safe_value > safety_threshold
solutions.append((x, value, safe_value))
# Tell evaluation values.
optimizer.tell(solutions)
print(f"#{generation} ({best_eval} {unsafe_eval_counts})")
if optimizer.should_stop():
break
def example2():
"""
example with multiple safety functions
"""
# number of dimensions
dim = 5
# objective function
def quadratic(x):
coef = 1000 ** (np.arange(dim) / float(dim - 1))
return np.sum((x * coef) ** 2)
# safety functions
def safe_function1(x):
return x[0]
def safe_function2(x):
return x[1]
# safe seeds
safe_seeds_num = 10
safe_seeds = (np.random.rand(safe_seeds_num, dim) * 2 - 1) * 5
safe_seeds[:, 0] = -np.abs(safe_seeds[:, 0])
safe_seeds[:, 1] = -np.abs(safe_seeds[:, 1])
# evaluation of safe seeds (with multiple safety functions)
seeds_evals = np.array([quadratic(x) for x in safe_seeds])
seeds_safe_evals = np.stack([[safe_function1(x), safe_function2(x)] for x in safe_seeds])
safety_threshold = np.array([0, 0])
# optimizer (safe CMA-ES)
optimizer = SafeCMA(
sigma=1.0,
safety_threshold=safety_threshold,
safe_seeds=safe_seeds,
seeds_evals=seeds_evals,
seeds_safe_evals=seeds_safe_evals,
)
unsafe_eval_counts = 0
best_eval = np.inf
for generation in range(400):
solutions = []
for _ in range(optimizer.population_size):
# Ask a parameter
x = optimizer.ask()
value = quadratic(x)
safe_value = np.array([safe_function1(x), safe_function2(x)])
# save best eval
best_eval = np.min((best_eval, value))
unsafe_eval_counts += safe_value > safety_threshold
solutions.append((x, value, safe_value))
# Tell evaluation values.
optimizer.tell(solutions)
print(f"#{generation} ({best_eval} {unsafe_eval_counts})")
if optimizer.should_stop():
break
if __name__ == "__main__":
example1()
example2()
cmaes-0.13.1/examples/sep_cma.py000066400000000000000000000014651524175644700165100ustar00rootroot00000000000000import numpy as np
from cmaes import SepCMA
def ellipsoid(x):
n = len(x)
if len(x) < 2:
raise ValueError("dimension must be greater one")
return sum([(1000 ** (i / (n - 1)) * x[i]) ** 2 for i in range(n)])
def main():
dim = 40
optimizer = SepCMA(mean=3 * np.ones(dim), sigma=2.0)
print(" evals f(x)")
print("====== ==========")
evals = 0
while True:
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = ellipsoid(x)
evals += 1
solutions.append((x, value))
if evals % 3000 == 0:
print(f"{evals:5d} {value:10.5f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
if __name__ == "__main__":
main()
cmaes-0.13.1/examples/ws_cma.py000066400000000000000000000023421524175644700163450ustar00rootroot00000000000000import numpy as np
from cmaes import CMA, get_warm_start_mgd
def source_task(x1: float, x2: float) -> float:
b = 0.4
return (x1 - b) ** 2 + (x2 - b) ** 2
def target_task(x1: float, x2: float) -> float:
b = 0.6
return (x1 - b) ** 2 + (x2 - b) ** 2
def main() -> None:
# Generate solutions from a source task
source_solutions = []
for _ in range(1000):
x = np.random.random(2)
value = source_task(x[0], x[1])
source_solutions.append((x, value))
# Estimate a promising distribution of the source task
ws_mean, ws_sigma, ws_cov = get_warm_start_mgd(source_solutions, gamma=0.1, alpha=0.1)
optimizer = CMA(mean=ws_mean, sigma=ws_sigma, cov=ws_cov)
# Run WS-CMA-ES
print(" g f(x1,x2) x1 x2 ")
print("=== ========== ====== ======")
while True:
solutions = []
for _ in range(optimizer.population_size):
x = optimizer.ask()
value = target_task(x[0], x[1])
solutions.append((x, value))
print(f"{optimizer.generation:3d} {value:10.5f} {x[0]:6.2f} {x[1]:6.2f}")
optimizer.tell(solutions)
if optimizer.should_stop():
break
if __name__ == "__main__":
main()
cmaes-0.13.1/fuzzing.py000066400000000000000000000020111524175644700147430ustar00rootroot00000000000000import sys
import atheris
import hypothesis.extra.numpy as npst
from hypothesis import given, strategies as st
from cmaes import CMA
@given(data=st.data())
def test_cma_tell(data):
dim = data.draw(st.integers(min_value=2, max_value=100))
mean = data.draw(npst.arrays(dtype=float, shape=dim))
sigma = data.draw(st.floats(min_value=1e-16))
n_iterations = data.draw(st.integers(min_value=1))
try:
optimizer = CMA(mean, sigma)
except AssertionError:
return
popsize = optimizer.population_size
for _ in range(n_iterations):
tell_solutions = data.draw(
st.lists(
st.tuples(npst.arrays(dtype=float, shape=dim), st.floats()),
min_size=popsize,
max_size=popsize,
)
)
optimizer.ask()
try:
optimizer.tell(tell_solutions)
except AssertionError:
return
optimizer.ask()
atheris.Setup(sys.argv, test_cma_tell.hypothesis.fuzz_one_input)
atheris.Fuzz()
cmaes-0.13.1/pyproject.toml000066400000000000000000000047531524175644700156300ustar00rootroot00000000000000[build-system]
requires = ["setuptools>=61"]
build-backend = "setuptools.build_meta"
[project]
name = "cmaes"
description = "Lightweight Covariance Matrix Adaptation Evolution Strategy (CMA-ES) implementation for Python 3."
readme = "README.md"
authors = [
{ name = "Masashi Shibata", "email" = "m.shibata1020@gmail.com" }
]
maintainers = [
{ name = "Masahiro Nomura", "email" = "masahironomura5325@gmail.com" },
{ name = "Ryoki Hamano", "email" = "hamano_ryoki_xa@cyberagent.co.jp" },
{ name = "Kazuhiro Ota", "email" = "ota_kazuhiro@cyberagent.co.jp" },
{ name = "Naoki Hamada", "email" = "hamada_naoki@cyberagent.co.jp" }
]
requires-python = ">=3.9"
license = "MIT"
classifiers = [
"Development Status :: 4 - Beta",
"Intended Audience :: Developers",
"Programming Language :: Python",
"Programming Language :: Python :: 3",
"Programming Language :: Python :: 3.9",
"Programming Language :: Python :: 3.10",
"Programming Language :: Python :: 3.11",
"Programming Language :: Python :: 3.12",
"Programming Language :: Python :: 3.13",
"Programming Language :: Python :: 3.14",
"Programming Language :: Python :: 3 :: Only",
"Intended Audience :: Science/Research",
]
dependencies = ["numpy"]
dynamic = ["version"]
[project.optional-dependencies]
cmawm = ["scipy"]
[project.urls]
"Homepage" = "https://github.com/CyberAgentAILab/cmaes"
[tool.setuptools.dynamic]
version = {attr = "cmaes.__version__"}
[tool.setuptools]
packages = ["cmaes"]
include-package-data = false
[tool.mypy]
ignore_missing_imports = true
disallow_untyped_defs = true
[tool.ruff]
line-length = 99
extend-exclude = ["*.md"]
exclude = [
".eggs",
".git",
".mypy_cache",
".venv",
"_build",
"build",
"dist",
"venv",
]
[tool.ruff.lint]
select = [
"E", # pycodestyle errors
"W", # pycodestyle warnings
"F", # pyflakes
"I", # isort
]
ignore = [
"I001", # Import block is unsorted
"E203",
]
[tool.uv]
exclude-newer = "1 week"
exclude-newer-package = { torch = false }
[[tool.uv.index]]
name = "pytorch-cpu"
url = "https://download.pytorch.org/whl/cpu"
explicit = true
[tool.uv.sources]
torch = [
{ index = "pytorch-cpu" },
]
[dependency-groups]
dev = [
# lint
"mypy",
"ruff",
# tests
"pytest",
# visualization
"matplotlib",
]
optional = [
# for Safe CMA-ES
"torch",
"gpytorch",
# for CMA with margin
"scipy",
]
benchmark = [
"kurobako",
"cma",
"optuna",
]
cmaes-0.13.1/tests/000077500000000000000000000000001524175644700140455ustar00rootroot00000000000000cmaes-0.13.1/tests/__init__.py000066400000000000000000000000001524175644700161440ustar00rootroot00000000000000cmaes-0.13.1/tests/test_boundary.py000066400000000000000000000040371524175644700173050ustar00rootroot00000000000000import numpy as np
from unittest import TestCase
from cmaes import CMA, SepCMA
CMA_CLASSES = [CMA, SepCMA]
class TestCMABoundary(TestCase):
def test_valid_dimension(self):
for CmaClass in CMA_CLASSES:
with self.subTest(f"Class: {CmaClass.__name__}"):
CmaClass(mean=np.zeros(2), sigma=1.3, bounds=np.array([[-10, 10], [-10, 10]]))
def test_invalid_dimension(self):
for CmaClass in CMA_CLASSES:
with self.subTest(f"Class: {CmaClass.__name__}"):
with self.assertRaises(AssertionError):
CmaClass(mean=np.zeros(2), sigma=1.3, bounds=np.array([-10, 10]))
def test_mean_located_out_of_bounds(self):
mean = np.zeros(5)
bounds = np.empty(shape=(5, 2))
bounds[:, 0], bounds[:, 1] = 1.0, 5.0
for CmaClass in CMA_CLASSES:
with self.subTest(f"Class: {CmaClass.__name__}"):
with self.assertRaises(AssertionError):
CmaClass(mean=mean, sigma=1.3, bounds=bounds)
def test_set_valid_bounds(self):
for CmaClass in CMA_CLASSES:
with self.subTest(f"Class: {CmaClass.__name__}"):
optimizer = CmaClass(mean=np.zeros(2), sigma=1.3)
optimizer.set_bounds(bounds=np.array([[-10, 10], [-10, 10]]))
def test_set_invalid_bounds(self):
for CmaClass in CMA_CLASSES:
with self.subTest(f"Class: {CmaClass.__name__}"):
optimizer = CmaClass(mean=np.zeros(2), sigma=1.3)
with self.assertRaises(AssertionError):
optimizer.set_bounds(bounds=np.array([-10, 10]))
def test_set_bounds_which_does_not_contain_mean(self):
for CmaClass in CMA_CLASSES:
with self.subTest(f"Class: {CmaClass.__name__}"):
optimizer = CmaClass(mean=np.zeros(2), sigma=1.3)
bounds = np.empty(shape=(5, 2))
bounds[:, 0], bounds[:, 1] = 1.0, 5.0
with self.assertRaises(AssertionError):
optimizer.set_bounds(bounds)
cmaes-0.13.1/tests/test_cmawm.py000066400000000000000000000022571524175644700165700ustar00rootroot00000000000000import warnings
import numpy as np
from numpy.testing import assert_almost_equal
from unittest import TestCase
from cmaes import CMA, CMAwM
class TestCMAwM(TestCase):
def test_no_discrete_spaces(self):
mean = np.zeros(2)
bounds = np.array([[-10, 10], [-10, 10]])
steps = np.array([0, 0])
sigma = 1.3
seed = 1
cma_optimizer = CMA(mean=mean, sigma=sigma, bounds=bounds, seed=seed)
with warnings.catch_warnings():
warnings.simplefilter("ignore", category=UserWarning)
cmawm_optimizer = CMAwM(mean=mean, sigma=sigma, bounds=bounds, steps=steps, seed=seed)
for i in range(100):
solutions = []
for _ in range(cma_optimizer.population_size):
cma_x = cma_optimizer.ask()
cmawm_x_encoded, cmawm_x_for_tell = cmawm_optimizer.ask()
assert_almost_equal(cma_x, cmawm_x_encoded)
assert_almost_equal(cma_x, cmawm_x_for_tell)
objective = (cma_x[0] - 3) ** 2 + cma_x[1] ** 2
solutions.append((cma_x, objective))
cma_optimizer.tell(solutions)
cmawm_optimizer.tell(solutions)
cmaes-0.13.1/tests/test_compress_symmetric.py000066400000000000000000000021611524175644700214050ustar00rootroot00000000000000import numpy as np
from unittest import TestCase
from cmaes._cma import _decompress_symmetric, _compress_symmetric
class TestCompressSymmetric(TestCase):
def test_compress_symmetric_odd(self):
sym2d = np.array([[1, 2], [2, 3]])
actual = _compress_symmetric(sym2d)
expected = np.array([1, 2, 3])
self.assertTrue(np.all(np.equal(actual, expected)))
def test_compress_symmetric_even(self):
sym2d = np.array([[1, 2, 3], [2, 4, 5], [3, 5, 6]])
actual = _compress_symmetric(sym2d)
expected = np.array([1, 2, 3, 4, 5, 6])
self.assertTrue(np.all(np.equal(actual, expected)))
def test_decompress_symmetric_odd(self):
sym1d = np.array([1, 2, 3])
actual = _decompress_symmetric(sym1d)
expected = np.array([[1, 2], [2, 3]])
self.assertTrue(np.all(np.equal(actual, expected)))
def test_decompress_symmetric_even(self):
sym1d = np.array([1, 2, 3, 4, 5, 6])
actual = _decompress_symmetric(sym1d)
expected = np.array([[1, 2, 3], [2, 4, 5], [3, 5, 6]])
self.assertTrue(np.all(np.equal(actual, expected)))
cmaes-0.13.1/tests/test_stats.py000066400000000000000000000026701524175644700166210ustar00rootroot00000000000000import math
from unittest import TestCase
from cmaes import _stats
# Test Cases in this file is generated by SciPy v1.9.3
class TestNormCDF(TestCase):
def test_standard_normal_distribution(self):
self.assertAlmostEqual(_stats.norm_cdf(-30), 4.906713927147907e-198, places=205)
self.assertAlmostEqual(_stats.norm_cdf(-10), 7.619853024160469e-24, places=30)
self.assertAlmostEqual(_stats.norm_cdf(-1), 0.15865525393145707)
self.assertAlmostEqual(_stats.norm_cdf(0), 0.5)
self.assertAlmostEqual(_stats.norm_cdf(1), 0.8413447460685429)
self.assertAlmostEqual(
_stats.norm_cdf(8),
0.9999999999999993338661852249060757458209991455078125,
places=30,
)
self.assertAlmostEqual(_stats.norm_cdf(10), 1.0)
def test_mu_and_sigma(self):
self.assertAlmostEqual(_stats.norm_cdf(1, loc=2, scale=3), 0.36944134018176367)
class TestChi2PPF(TestCase):
def test(self):
self.assertAlmostEqual(_stats.chi2_ppf(0.0), 0.0)
self.assertAlmostEqual(_stats.chi2_ppf(0.00000001), 1.5707963267948962e-16, places=25)
self.assertAlmostEqual(_stats.chi2_ppf(0.5), 0.454936423119572)
self.assertAlmostEqual(_stats.chi2_ppf(0.99999999), 32.84125335146885)
self.assertAlmostEqual(
_stats.chi2_ppf(0.999999999999999777955395074969), 67.39648382445012
)
self.assertAlmostEqual(_stats.chi2_ppf(1.0), math.inf)
cmaes-0.13.1/tests/test_termination_criterion.py000066400000000000000000000016121524175644700220650ustar00rootroot00000000000000import numpy as np
from unittest import TestCase
from cmaes import CMA
class TestTerminationCriterion(TestCase):
def test_stop_if_objective_values_are_not_changed(self):
optimizer = CMA(mean=np.zeros(2), sigma=1.3)
popsize = optimizer.population_size
rng = np.random.RandomState(seed=1)
for i in range(optimizer._funhist_term + 1):
self.assertFalse(optimizer.should_stop())
optimizer.tell([(rng.randn(2), 0.01) for _ in range(popsize)])
self.assertTrue(optimizer.should_stop())
def test_stop_if_detect_divergent_behavior(self):
optimizer = CMA(mean=np.zeros(2), sigma=1e-4)
popsize = optimizer.population_size
nd_rng = np.random.RandomState(1)
solutions = [(100 * nd_rng.randn(2), 0.01) for _ in range(popsize)]
optimizer.tell(solutions)
self.assertTrue(optimizer.should_stop())
cmaes-0.13.1/tests/test_warm_start.py000066400000000000000000000006201524175644700176370ustar00rootroot00000000000000import numpy as np
from unittest import TestCase
from cmaes import CMA, get_warm_start_mgd
class TestWarmStartCMA(TestCase):
def test_dimension(self):
optimizer = CMA(mean=np.zeros(10), sigma=1.3)
source_solutions = [(optimizer.ask(), 0.0) for _ in range(100)]
ws_mean, ws_sigma, ws_cov = get_warm_start_mgd(source_solutions)
self.assertEqual(ws_mean.size, 10)
cmaes-0.13.1/tools/000077500000000000000000000000001524175644700140435ustar00rootroot00000000000000cmaes-0.13.1/tools/cmaes_visualizer.py000066400000000000000000000200761524175644700177670ustar00rootroot00000000000000"""
Usage:
cmaes_visualizer.py OPTIONS
Optional arguments:
-h, --help show this help message and exit
--function {quadratic,himmelblau,rosenbrock,six-hump-camel}
--seed SEED
--frames FRAMES
--interval INTERVAL
--pop-per-frame POP_PER_FRAME
--restart-strategy {ipop,bipop}
Example:
python3 cmaes_visualizer.py --function six-hump-camel --pop-per-frame 2
python3 tools/cmaes_visualizer.py --function himmelblau \
--restart-strategy ipop --frames 500 --interval 10 --pop-per-frame 6
"""
import argparse
import math
import numpy as np
from scipy import stats
from matplotlib.colors import LinearSegmentedColormap
import matplotlib.pyplot as plt
import matplotlib.animation as animation
from pylab import rcParams
from cmaes._cma import CMA
parser = argparse.ArgumentParser()
parser.add_argument(
"--function",
choices=["quadratic", "himmelblau", "rosenbrock", "six-hump-camel"],
)
parser.add_argument(
"--seed",
type=int,
default=1,
)
parser.add_argument(
"--frames",
type=int,
default=100,
)
parser.add_argument(
"--interval",
type=int,
default=20,
)
parser.add_argument(
"--pop-per-frame",
type=int,
default=1,
)
parser.add_argument(
"--restart-strategy",
choices=["ipop", "bipop"],
default="",
)
args = parser.parse_args()
rcParams["figure.figsize"] = 10, 5
fig, (ax1, ax2) = plt.subplots(1, 2)
color_dict = {
"red": ((0.0, 0.0, 0.0), (1.0, 1.0, 1.0)),
"green": ((0.0, 0.0, 0.0), (1.0, 1.0, 1.0)),
"blue": ((0.0, 1.0, 1.0), (1.0, 1.0, 1.0)),
"yellow": ((1.0, 1.0, 1.0), (1.0, 1.0, 1.0)),
}
bw = LinearSegmentedColormap("BlueWhile", color_dict)
def himmelblau(x1, x2):
return (x1**2 + x2 - 11.0) ** 2 + (x1 + x2**2 - 7.0) ** 2
def himmelblau_contour(x1, x2):
return np.log(himmelblau(x1, x2) + 1)
def quadratic(x1, x2):
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
def quadratic_contour(x1, x2):
return np.log(quadratic(x1, x2) + 1)
def rosenbrock(x1, x2):
return 100 * (x2 - x1**2) ** 2 + (x1 - 1) ** 2
def rosenbrock_contour(x1, x2):
return np.log(rosenbrock(x1, x2) + 1)
def six_hump_camel(x1, x2):
return (4 - 2.1 * (x1**2) + (x1**4) / 3) * (x1**2) + x1 * x2 + (-4 + 4 * x2**2) * (x2**2)
def six_hump_camel_contour(x1, x2):
return np.log(six_hump_camel(x1, x2) + 1.0316)
function_name = ""
if args.function == "quadratic":
function_name = "Quadratic function"
objective = quadratic
contour_function = quadratic_contour
global_minimums = [
(3.0, -2.0),
]
# input domain
x1_lower_bound, x1_upper_bound = -4, 4
x2_lower_bound, x2_upper_bound = -4, 4
elif args.function == "himmelblau":
function_name = "Himmelblau function"
objective = himmelblau
contour_function = himmelblau_contour
global_minimums = [
(3.0, 2.0),
(-2.805118, 3.131312),
(-3.779310, -3.283186),
(3.584428, -1.848126),
]
# input domain
x1_lower_bound, x1_upper_bound = -4, 4
x2_lower_bound, x2_upper_bound = -4, 4
elif args.function == "rosenbrock":
# https://www.sfu.ca/~ssurjano/rosen.html
function_name = "Rosenbrock function"
objective = rosenbrock
contour_function = rosenbrock_contour
global_minimums = [
(1, 1),
]
# input domain
x1_lower_bound, x1_upper_bound = -5, 10
x2_lower_bound, x2_upper_bound = -5, 10
elif args.function == "six-hump-camel":
# https://www.sfu.ca/~ssurjano/camel6.html
function_name = "Six-hump camel function"
objective = six_hump_camel
contour_function = six_hump_camel_contour
global_minimums = [
(0.0898, -0.7126),
(-0.0898, 0.7126),
]
# input domain
x1_lower_bound, x1_upper_bound = -3, 3
x2_lower_bound, x2_upper_bound = -2, 2
else:
raise ValueError("invalid function type")
seed = args.seed
bounds = np.array([[x1_lower_bound, x1_upper_bound], [x2_lower_bound, x2_upper_bound]])
sigma0 = (x1_upper_bound - x2_lower_bound) / 5
optimizer = CMA(mean=np.zeros(2), sigma=sigma0, bounds=bounds, seed=seed)
solutions = []
trial_number = 0
rng = np.random.RandomState(seed)
# Variables for IPOP and BIPOP
inc_popsize = 2
n_restarts = 0 # A small restart doesn't count in the n_restarts
small_n_eval, large_n_eval = 0, 0
popsize0 = optimizer.population_size
poptype = "small"
def init():
ax1.set_xlim(x1_lower_bound, x1_upper_bound)
ax1.set_ylim(x2_lower_bound, x2_upper_bound)
ax2.set_xlim(x1_lower_bound, x1_upper_bound)
ax2.set_ylim(x2_lower_bound, x2_upper_bound)
# Plot 4 local minimum value
for m in global_minimums:
ax1.plot(m[0], m[1], "y*", ms=10)
ax2.plot(m[0], m[1], "y*", ms=10)
# Plot contour of himmelblau function
x1 = np.arange(x1_lower_bound, x1_upper_bound, 0.01)
x2 = np.arange(x2_lower_bound, x2_upper_bound, 0.01)
x1, x2 = np.meshgrid(x1, x2)
ax1.contour(x1, x2, contour_function(x1, x2), 30, cmap=bw)
def get_next_popsize_sigma():
global n_restarts, poptype, small_n_eval, large_n_eval
if args.restart_strategy == "ipop":
n_restarts += 1
popsize = optimizer.population_size * inc_popsize
print(f"Restart CMA-ES with popsize={popsize} at trial={trial_number}")
return popsize, sigma0
elif args.restart_strategy == "bipop":
n_eval = optimizer.population_size * optimizer.generation
if poptype == "small":
small_n_eval += n_eval
else: # poptype == "large"
large_n_eval += n_eval
if small_n_eval < large_n_eval:
poptype = "small"
popsize_multiplier = inc_popsize**n_restarts
popsize = math.floor(popsize0 * popsize_multiplier ** (rng.uniform() ** 2))
sigma = sigma0 * 10 ** (-2 * rng.uniform())
else:
poptype = "large"
n_restarts += 1
popsize = popsize0 * (inc_popsize**n_restarts)
sigma = sigma0
print(f"Restart CMA-ES with popsize={popsize} ({poptype}) at trial={trial_number}")
return popsize, sigma
raise Exception("must not reach here")
def update(frame):
global solutions, optimizer, trial_number
if len(solutions) == optimizer.population_size:
optimizer.tell(solutions)
solutions = []
if optimizer.should_stop():
popsize, sigma = get_next_popsize_sigma()
lower_bounds, upper_bounds = bounds[:, 0], bounds[:, 1]
mean = lower_bounds + (rng.rand(2) * (upper_bounds - lower_bounds))
optimizer = CMA(
mean=mean,
sigma=sigma,
bounds=bounds,
seed=seed,
population_size=popsize,
)
n_sample = min(optimizer.population_size - len(solutions), args.pop_per_frame)
for i in range(n_sample):
x = optimizer.ask()
evaluation = objective(x[0], x[1])
# Plot sample points
ax1.plot(x[0], x[1], "o", c="r", label="2d", alpha=0.5)
solution = (
x,
evaluation,
)
solutions.append(solution)
trial_number += n_sample
# Update title
if args.restart_strategy == "ipop":
fig.suptitle(
f"IPOP-CMA-ES {function_name} trial={trial_number} popsize={optimizer.population_size}"
)
elif args.restart_strategy == "bipop":
fig.suptitle(
f"BIPOP-CMA-ES {function_name} trial={trial_number} "
f"popsize={optimizer.population_size} ({poptype})"
)
else:
fig.suptitle(f"CMA-ES {function_name} trial={trial_number}")
# Plot multivariate gaussian distribution of CMA-ES
x, y = np.mgrid[x1_lower_bound:x1_upper_bound:0.01, x2_lower_bound:x2_upper_bound:0.01]
rv = stats.multivariate_normal(optimizer._mean, optimizer._C)
pos = np.dstack((x, y))
ax2.contourf(x, y, rv.pdf(pos))
if frame % 50 == 0:
print(f"Processing frame {frame}")
def main():
ani = animation.FuncAnimation(
fig,
update,
frames=args.frames,
init_func=init,
blit=False,
interval=args.interval,
)
ani.save(f"./tmp/{args.function}.mp4")
if __name__ == "__main__":
main()
cmaes-0.13.1/tools/optuna_profile.py000066400000000000000000000021011524175644700174350ustar00rootroot00000000000000import argparse
import cProfile
import logging
import pstats
import optuna
parser = argparse.ArgumentParser()
parser.add_argument("--storage", choices=["memory", "sqlite"], default="memory")
parser.add_argument("--params", type=int, default=100)
parser.add_argument("--trials", type=int, default=1000)
args = parser.parse_args()
def objective(trial: optuna.Trial):
val = 0
for i in range(args.params):
xi = trial.suggest_uniform(str(i), -4, 4)
val += (xi - 2) ** 2
return val
def main():
logging.disable(level=logging.INFO)
storage = None
if args.storage == "sqlite":
storage = f"sqlite:///db-{args.trials}-{args.params}.sqlite3"
sampler = optuna.samplers.CmaEsSampler()
study = optuna.create_study(sampler=sampler, storage=storage)
profiler = cProfile.Profile()
profiler.runcall(study.optimize, objective, n_trials=args.trials, gc_after_trial=False)
profiler.dump_stats("profile.stats")
stats = pstats.Stats("profile.stats")
stats.sort_stats("time").print_stats(5)
if __name__ == "__main__":
main()
cmaes-0.13.1/tools/ws_cmaes_visualizer.py000066400000000000000000000156531524175644700205050ustar00rootroot00000000000000"""
Usage:
python3 tools/ws_cmaes_visualizer.py OPTIONS
Optional arguments:
-h, --help show this help message and exit
--function {quadratic,himmelblau,rosenbrock,six-hump-camel,sphere,rot-ellipsoid}
--seed SEED
--alpha ALPHA
--gamma GAMMA
--frames FRAMES
--interval INTERVAL
--pop-per-frame POP_PER_FRAME
Example:
python3 ws_cmaes_visualizer.py --function rot-ellipsoid
"""
import argparse
import math
import numpy as np
from scipy import stats
from matplotlib.colors import LinearSegmentedColormap
import matplotlib.pyplot as plt
import matplotlib.animation as animation
from pylab import rcParams
from cmaes import get_warm_start_mgd
parser = argparse.ArgumentParser()
parser.add_argument(
"--function",
choices=[
"quadratic",
"himmelblau",
"rosenbrock",
"six-hump-camel",
"sphere",
"rot-ellipsoid",
],
)
parser.add_argument(
"--seed",
type=int,
default=1,
)
parser.add_argument(
"--alpha",
type=float,
default=0.1,
)
parser.add_argument(
"--gamma",
type=float,
default=0.1,
)
parser.add_argument(
"--frames",
type=int,
default=100,
)
parser.add_argument(
"--interval",
type=int,
default=20,
)
parser.add_argument(
"--pop-per-frame",
type=int,
default=10,
)
args = parser.parse_args()
rcParams["figure.figsize"] = 10, 5
fig, (ax1, ax2) = plt.subplots(1, 2)
color_dict = {
"red": ((0.0, 0.0, 0.0), (1.0, 1.0, 1.0)),
"green": ((0.0, 0.0, 0.0), (1.0, 1.0, 1.0)),
"blue": ((0.0, 1.0, 1.0), (1.0, 1.0, 1.0)),
"yellow": ((1.0, 1.0, 1.0), (1.0, 1.0, 1.0)),
}
bw = LinearSegmentedColormap("BlueWhile", color_dict)
def himmelbleu(x1, x2):
return (x1**2 + x2 - 11.0) ** 2 + (x1 + x2**2 - 7.0) ** 2
def himmelbleu_contour(x1, x2):
return np.log(himmelbleu(x1, x2) + 1)
def quadratic(x1, x2):
return (x1 - 3) ** 2 + (10 * (x2 + 2)) ** 2
def quadratic_contour(x1, x2):
return np.log(quadratic(x1, x2) + 1)
def rosenbrock(x1, x2):
return 100 * (x2 - x1**2) ** 2 + (x1 - 1) ** 2
def rosenbrock_contour(x1, x2):
return np.log(rosenbrock(x1, x2) + 1)
def six_hump_camel(x1, x2):
return (4 - 2.1 * (x1**2) + (x1**4) / 3) * (x1**2) + x1 * x2 + (-4 + 4 * x2**2) * (x2**2)
def six_hump_camel_contour(x1, x2):
return np.log(six_hump_camel(x1, x2) + 1.0316)
def sphere(x1, x2):
offset = 0.6
return (x1 - offset) ** 2 + (x2 - offset) ** 2
def sphere_contour(x1, x2):
return np.log(sphere(x1, x2) + 1)
def ellipsoid(x1, x2):
offset = 0.6
scale = 5**2
return (x1 - offset) ** 2 + scale * (x2 - offset) ** 2
def rot_ellipsoid(x1, x2):
rot_x1 = math.sqrt(3.0) / 2.0 * x1 + 1.0 / 2.0 * x2
rot_x2 = 1.0 / 2.0 * x1 + math.sqrt(3.0) / 2.0 * x2
return ellipsoid(rot_x1, rot_x2)
def rot_ellipsoid_contour(x1, x2):
return np.log(rot_ellipsoid(x1, x2) + 1)
function_name = ""
if args.function == "quadratic":
function_name = "Quadratic function"
objective = quadratic
contour_function = quadratic_contour
global_minimums = [
(3.0, -2.0),
]
# input domain
x1_lower_bound, x1_upper_bound = -4, 4
x2_lower_bound, x2_upper_bound = -4, 4
elif args.function == "himmelblau":
function_name = "Himmelblau function"
objective = himmelbleu
contour_function = himmelbleu_contour
global_minimums = [
(3.0, 2.0),
(-2.805118, 3.131312),
(-3.779310, -3.283186),
(3.584428, -1.848126),
]
# input domain
x1_lower_bound, x1_upper_bound = -4, 4
x2_lower_bound, x2_upper_bound = -4, 4
elif args.function == "rosenbrock":
# https://www.sfu.ca/~ssurjano/rosen.html
function_name = "Rosenbrock function"
objective = rosenbrock
contour_function = rosenbrock_contour
global_minimums = [
(1, 1),
]
# input domain
x1_lower_bound, x1_upper_bound = -5, 10
x2_lower_bound, x2_upper_bound = -5, 10
elif args.function == "six-hump-camel":
# https://www.sfu.ca/~ssurjano/camel6.html
function_name = "Six-hump camel function"
objective = six_hump_camel
contour_function = six_hump_camel_contour
global_minimums = [
(0.0898, -0.7126),
(-0.0898, 0.7126),
]
# input domain
x1_lower_bound, x1_upper_bound = -3, 3
x2_lower_bound, x2_upper_bound = -2, 2
elif args.function == "sphere":
function_name = "Sphere function with offset=0.6"
objective = sphere
contour_function = sphere_contour
global_minimums = [
(0.6, 0.6),
]
# input domain
x1_lower_bound, x1_upper_bound = 0, 1
x2_lower_bound, x2_upper_bound = 0, 1
elif args.function == "rot-ellipsoid":
function_name = "Rot Ellipsoid function with offset=0.6"
objective = rot_ellipsoid
contour_function = rot_ellipsoid_contour
global_minimums = []
# input domain
x1_lower_bound, x1_upper_bound = 0, 1
x2_lower_bound, x2_upper_bound = 0, 1
else:
raise ValueError("invalid function type")
seed = args.seed
rng = np.random.RandomState(seed)
solutions = []
def init():
ax1.set_xlim(x1_lower_bound, x1_upper_bound)
ax1.set_ylim(x2_lower_bound, x2_upper_bound)
ax2.set_xlim(x1_lower_bound, x1_upper_bound)
ax2.set_ylim(x2_lower_bound, x2_upper_bound)
# Plot 4 local minimum value
for m in global_minimums:
ax1.plot(m[0], m[1], "y*", ms=10)
ax2.plot(m[0], m[1], "y*", ms=10)
# Plot contour of the function
x1 = np.arange(x1_lower_bound, x1_upper_bound, 0.01)
x2 = np.arange(x2_lower_bound, x2_upper_bound, 0.01)
x1, x2 = np.meshgrid(x1, x2)
ax1.contour(x1, x2, contour_function(x1, x2), 30, cmap=bw)
def update(frame):
for i in range(args.pop_per_frame):
x1 = (x1_upper_bound - x1_lower_bound) * rng.random() + x1_lower_bound
x2 = (x2_upper_bound - x2_lower_bound) * rng.random() + x2_lower_bound
evaluation = objective(x1, x2)
# Plot sample points
ax1.plot(x1, x2, "o", c="r", label="2d", alpha=0.5)
solution = (
np.array([x1, x2], dtype=float),
evaluation,
)
solutions.append(solution)
# Update title
fig.suptitle(
f"WS-CMA-ES {function_name} with alpha={args.alpha} and gamma={args.gamma} (frame={frame})"
)
# Plot multivariate gaussian distribution of CMA-ES
x, y = np.mgrid[x1_lower_bound:x1_upper_bound:0.01, x2_lower_bound:x2_upper_bound:0.01]
if math.floor(len(solutions) * args.alpha) > 1:
mean, sigma, cov = get_warm_start_mgd(solutions, alpha=args.alpha, gamma=args.gamma)
rv = stats.multivariate_normal(mean, cov)
pos = np.dstack((x, y))
ax2.contourf(x, y, rv.pdf(pos))
if frame % 50 == 0:
print(f"Processing frame {frame}")
def main():
ani = animation.FuncAnimation(
fig,
update,
frames=args.frames,
init_func=init,
blit=False,
interval=args.interval,
)
ani.save(f"./tmp/{args.function}.mp4")
if __name__ == "__main__":
main()